TRANSMISSION // 2611.23202v1
A Trust Checkpoint for AI Agents Crossing Organization Boundaries
Source published
ATI proposes identity, configuration and permission checks for AI agents working across organizations. Its simulated evaluation reports stronger attack containment, but the headline comparison mixes measured and inferred values, and important risks remain.
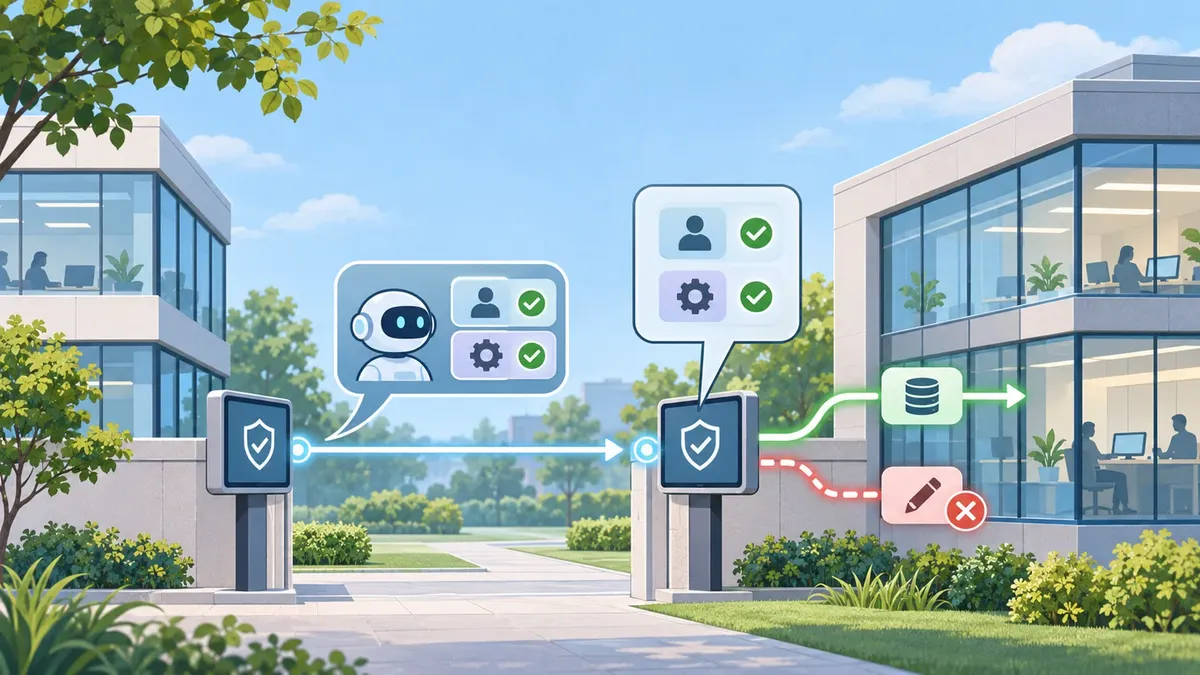
When an AI agent asks another organization to use a tool or access data, how can the recipient check who is asking, what setup it is running and whether the action is allowed? Agent Trust Infrastructure (ATI) proposes security checks outside the agent’s model. In a simulated evaluation, it contained more of the tested attacks, though the headline result needs an important qualification.
AI agents can plan tasks, call tools and pass work to other agents. When those agents belong to different organizations, a basic question becomes harder: can the receiving organization verify the caller’s identity, check its software setup and control what it may do? Viet K. Nguyen and Mohammad I. Husain propose Agent Trust Infrastructure (ATI), a security layer intended to address these questions without changing an agent’s underlying model or orchestration framework.
The authors treat each agent as a distinct security principal, like a user or software service. ATI places a reference monitor—a checkpoint that requests must pass—outside the agent’s model. Its five planes handle identity, organizational trust, configuration checks, authorization and records of actions.
In the proposed federation, each organization runs its own certificate authority, called an AgentCA. Organizations exchange public keys to establish peer trust, without relying on a single shared root authority. When a request arrives, the receiving organization’s monitor checks the agent’s cryptographic signature and certificate. It also compares the running model, approved tools and system prompt with trusted configuration values. In the prototype, these are in-process checks based on measurements reported by the host, not independent hardware-backed remote attestation. Policy checks govern tool calls, such as database reads and writes. An accountability log records checked tool actions, including those flagged for review; it does not capture every aspect of an agent’s activity.
The researchers implemented a Python reference monitor and tested it in a simulated federation of eight organizations, each with a five-agent team. The setup included six agent frameworks, but the security experiments involved only two organizations and two of those frameworks. They tested 14 attack scenarios and six benign tasks across five agent models. For each attack and model, they used five different wordings and ran three repetitions per wording. A panel of judge models assessed whether each attack had been stopped.
With all four blocking planes enabled, reported overall attack containment rose from 43% without defenses to 84%. That headline comparison needs a caveat: for three attack scenarios, A12–A14, the researchers ran only the baseline and the configuration expected to stop each attack, then filled in other entries based on how the checks work. The overall row therefore combines measured results with values inferred from the design. For the 11 scenarios evaluated consistently across configurations, the authors report an increase from 40% to 80%; that figure is their reported result, not a separate calculation independently established here.
The clearest gains came where a specific check matched a threat. Configuration checks stopped the tested model substitutions, tool tampering and system-prompt changes. Identity and certificate checks stopped several impersonation and certificate attacks. Policy checks partly reduced replay attacks and unauthorized cross-organization writes; they did not stop every attempt. The added checks took about 174 microseconds per request in the reported benchmark. Benign task success was similar in the test: 91% without ATI and 92% with all defenses enabled. These findings concern the study’s simulated tasks, not a live federation of independently administered organizations.
ATI did not address every security problem. It did not prevent prompt injection hidden in data an agent reads. It flagged, rather than blocked, a tested collusion pattern because the same behavior could also be legitimate work. Some attacks remained only partly addressed, and model behavior varied: the same attack could be refused by one model and carried out by another. Because configuration checks rely on host-reported measurements, a compromised host could falsify them; hardware-backed attestation was not implemented.
The authors also describe implementation and evaluation limits. The simulated organizations ran in one process, and the full attack suite was not repeated across all six frameworks. Performance under heavy load was not measured. The audit log can reveal edits to retained entries but does not independently detect deletion from the end of the log; a stolen organizational signing key could also undermine the record. Scalable certificate revocation and privacy protections for identity and audit metadata remain open issues.
ATI is presented as a framework-independent architecture and released as an open-source package. Its evaluation provides evidence that deterministic checks can contain certain defined attacks in a controlled setup. It does not establish production readiness or broad protection against agent security failures. This article is based on an arXiv preprint, which may not have undergone peer review; the findings should be understood in light of the testbed, attack definitions and judging procedure described by the authors.
- AI agent security
- federated identity
- configuration attestation
- zero trust
- cross-organization agents
- authorization
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
Conflux puts permission checks outside the language model
Shared method: Both papers place security decisions outside model judgment: ATI uses an external enforcement layer for identity, configuration, and policy checks, while Conflux’s ITES kernel checks action permissions against recorded principal provenance and the organization’s access-control system. The mechanisms and guarantees differ: ATI reports simulated attack-containment results, whereas Conflux gives a conditional theorem limited to represented value influence and stated assumptions.
Model review: · openai-codex/gpt-6-luna
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2611.23202v1 — Original paper
Excerpt reference:
static/papers/2611.23202v1.md:13-68
Basis: Paper text
Source SHA-256:09a99cd0eb93d7016725edbed47a8e700f90f5eb85fd1d80cdbf4218ffe386982611.08768v1 — Original paper
Excerpt reference:
static/papers/2611.08768v1.md:13-51
Basis: Paper text
Source SHA-256:da5430a6a55ab0737841f3e34e0719511603e6be78eff9ed1eb64694397b5569
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
LatentTriad screens AI agent skills before they act
Source published
Shared keywords: ai agent security
Conflux puts permission checks outside the language model
Source published
Shared keywords: ai agent security
A Signed AI Tool Can Leak Data Through an Approved Service
Source published
Shared keywords: ai agent security
MemoryDojo tests how poisoned AI memories influence later tasks
Source published
Shared keywords: ai agent security