TRANSMISSION // 2611.21605v1
Training visual agents to look, not guess
Source published
ViRA agents are trained with CrossRPO, which rewards solving groups of image questions whose answers change with a small visual detail.
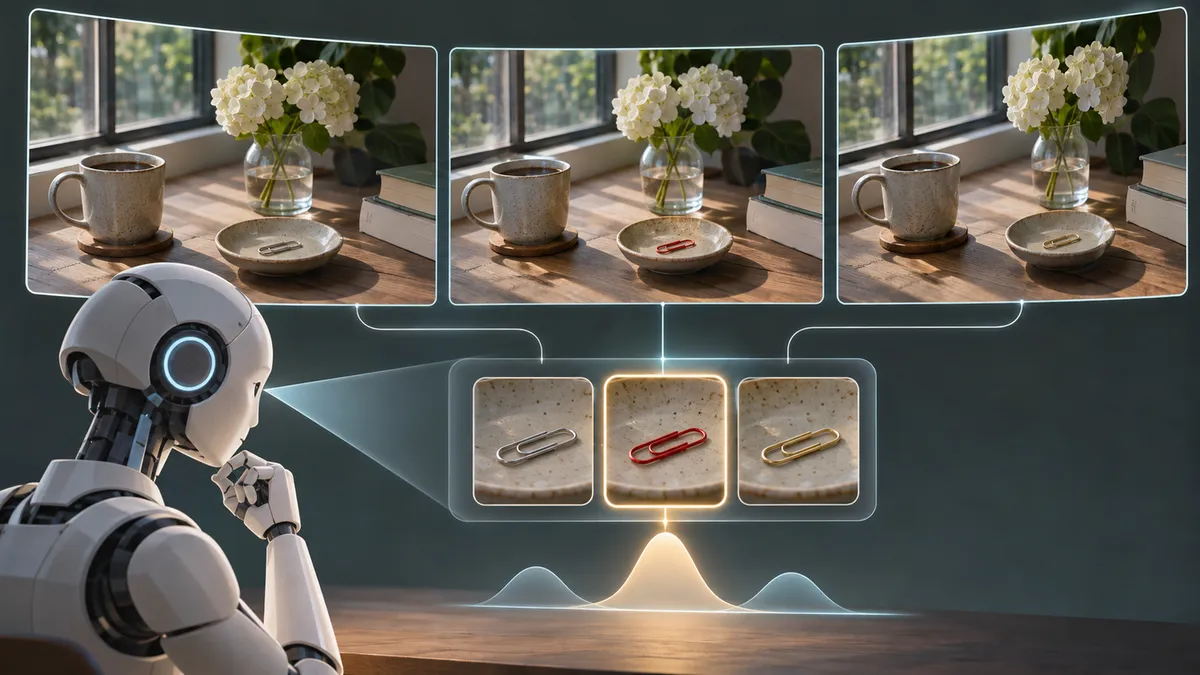
A visual AI can give a plausible answer without relying on the relevant part of an image. A new training method tries to make that shortcut less rewarding by testing whether an agent can answer questions across images that differ in a small but important way.
The problem with a plausible answer
A person looking at a detailed photograph can zoom in to inspect a small object. But a correct answer from a visual AI agent does not, by itself, show that the agent used the image evidence. If training rewards only the final answer, a guess based on context may earn the same reward as an answer reached by inspecting the relevant detail.
The paper proposes Cross-Input Relative Policy Optimization, or CrossRPO, as a way to address this problem. ViRA is the name used for the agents trained with the method: the researchers report results for ViRA-9B and ViRA-27B.
Training on contrasting images
CrossRPO trains agents on contrast sets. Each set presents the same question about several versions of an image. The versions differ in a small region containing the evidence, and the correct answer changes accordingly. The researchers’ reasoning is that solving the whole set requires reading the visual evidence rather than relying only on common sense.
The method rewards solving the entire set, rather than treating each answer in isolation. The authors also report a theoretical proof that, under their formulation, CrossRPO does not reinforce a set answered from common sense alone. That result concerns the method’s defined training setting; it does not establish that agents will always inspect evidence in other circumstances.
The researchers built ViRA-Train for training and ViRA-Bench for evaluation by editing a small object in images ranging from 21 to 120 megapixels. They also created ViRA-Bench-Real by photographing additional sets with real changes, intended to rule out traces left by editing. The two agents were each trained on about 3,500 ViRA-Train items.
What the abstract reports
At the maximum resolution on ViRA-Bench, CrossRPO achieved 63.3% set accuracy, compared with 59.3% for GRPO, another reinforcement-learning method. The abstract does not define “set accuracy,” so it is safest to read this as the authors’ reported measure of performance on contrast sets rather than assume a more specific interpretation.
The authors also report that ViRA-9B was the most accurate open model of its size on all benchmarks. ViRA-27B reportedly outperformed Claude Haiku 5.5 and GPT-6-Luna, both evaluated at their highest thinking level, on most benchmarks. These are claims reported in the abstract, not independent confirmations of the comparisons.
What the evidence does—and doesn’t—show
The source available here is the paper’s abstract. It reports the approach, selected results, and the authors’ theoretical claim, but does not give enough detail in this source to independently assess the evaluation or interpret every comparison. The abstract’s reported benchmark results also cannot establish how well the approach works beyond those evaluations.
A reasonable open question is how training on deliberately constructed contrast sets transfers to everyday images, where the relevant differences may not be arranged in advance. That is a question for further evaluation, not a reported finding. The paper is an arXiv preprint; its status alone does not tell us what independent review it has received.
The core proposal is to reward an agent for getting a group of related image questions right when a small change in visual evidence changes the answer. The authors’ proof and benchmark results support that approach within the settings they describe, but do not guarantee evidence-based answers in every use case.
- visual AI
- image question answering
- reinforcement learning
- high-resolution images
- AI evaluation
- ViRA
- CrossRPO
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
AdaAlloc helps video AI decide where to look closely
Supporting evidence: Both studies support the bounded idea that directing visual inspection toward relevant evidence can help: ViRA describes zooming into image regions and trains on contrast sets, while AdaAlloc allocates video tokens between global context and localized detail. They study different tasks and methods, so this is not a direct comparison of results.
Model review: · openai-codex/gpt-6-luna
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2611.21605v1 — Original paper
Excerpt reference:
static/papers/2611.21605v1.md:13-104
Basis: Paper text
Source SHA-256:d6d26fadcbcec9ae57abccce06be10d7d669a51dd73af884ac648d581477f5f52611.09092v1 — Original paper
Excerpt reference:
static/papers/2611.09092v1.md:398-460
Basis: Paper text
Source SHA-256:f0ee21807145c542d29097ba5e2be07fabd814eb18746c9322c4b590c6c049522611.09092v1 — Original paper
Excerpt reference:
static/papers/2611.09092v1.md:113-161
Basis: Paper text
Source SHA-256:f0ee21807145c542d29097ba5e2be07fabd814eb18746c9322c4b590c6c04952
When an AI’s training score rises but its answers get worse
Shared method: Both papers discuss GRPO: ViRA reports it as a comparator for CrossRPO, and the practical RL book explains its group-relative baseline. This is a shared algorithm reference, not evidence that their training settings or conclusions are equivalent.
Model review: · openai-codex/gpt-6-luna
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2611.21605v1 — Original paper
Excerpt reference:
static/papers/2611.21605v1.md:481-523
Basis: Paper text
Source SHA-256:d6d26fadcbcec9ae57abccce06be10d7d669a51dd73af884ac648d581477f5f52611.10844v1 — Original paper
Excerpt reference:
static/papers/2611.10844v1.md:2440-2561
Basis: Paper text
Source SHA-256:2fa4b7fa7a587fb73b334de647b00750954719cf978df4d77e7785ee0b6f1359
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
When an AI’s training score rises but its answers get worse
Source published
Shared keywords: ai evaluation, reinforcement learning
When an AI Queries a Database, How Does It Know What You Mean?
Source published
Shared keywords: ai evaluation, reinforcement learning
Can AI Improve Its Writing by Changing How It Judges Itself?
Source published
Shared keywords: ai evaluation, reinforcement learning
AtariBench exposes AI models’ difficulty turning moving images into reliable actions
Source published
Shared keywords: ai evaluation, reinforcement learning
Estimating AI Reliability With Fewer Repeated Trials
Source published
Shared keywords: ai evaluation