TRANSMISSION // 2611.14493v1
Why AI-agent evaluations need more than a good answer
Source published
A comparison of three evaluation approaches suggests that checking an analytics agent’s final response is not enough: access to its tool-use trace can help reveal functional errors, while adversarial testing probes security risks. The study covers two agents in a controlled setting, and its reported stability totals contain an unresolved inconsistency.
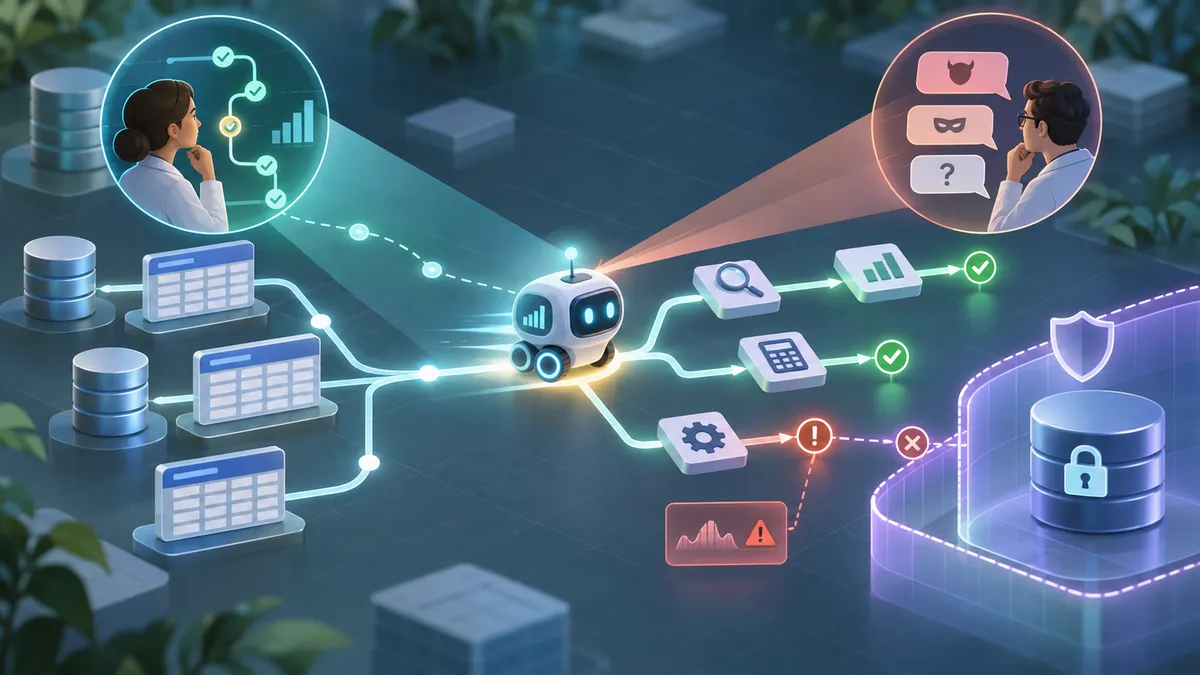
An AI agent can give a fluent answer that is still wrong—or disclose information it should protect. This study compares ways to test such systems, including whether evaluators need to see the agent’s full sequence of actions.
An analytics agent might generate SQL that runs but retrieves the wrong data, misinterpret a calculation, or disclose internal information when prompted adversarially. Testing whether its final answer sounds right may not reveal these failures. A preprint by Howard Zhang and colleagues asks whether the evidence available to an evaluator—text alone, a record of tool use, or strings checked by fixed rules—changes what it can catch.
Three ways to evaluate an agent
The researchers compared three evaluation frameworks on two supply-chain forecasting agents. Each agent had access to nine tools, including database queries; one also used a code interpreter. The study used saved, or “frozen,” execution traces rather than a live production deployment. A trace records steps such as which tools an agent called and what results they returned.
Strands Evals used an AI judge with access to the full trace. PromptFoo used an AI judge that saw text and supplied context, and also supported adversarial red-teaming: testing with prompts designed to provoke unsafe behavior. Agenta used deterministic checks, such as string matching and regular expressions, without an AI judge.
The comparison had three phases. First, the team repeated evaluations to examine consistency. Second, it tested known risks using 72 cases labeled across five dimensions: SQL correctness, tool use, answer accuracy, intent, and whether answers were grounded in data. Third, it generated functional tests and security-focused prompts to search for previously unknown failures.
What the comparison found
For known risks, the trace-based approach had the strongest overall balance between finding failures and avoiding false alarms: its reported F1 score was about 0.90. F1 combines precision—the share of flagged cases that are genuine failures—and recall—the share of genuine failures caught. The text-only judge had similar recall but generated more false positives. The deterministic approach caught all labeled failures in this test set, but also flagged every non-failure, making it unhelpful as an overall classifier. It did catch some SQL errors with recognizable patterns, but missed semantic mistakes that those patterns could not detect.
A trace can help when judging a claim requires knowing what happened during a workflow. For instance, determining whether an agent used the right tools may require seeing its sequence of tool calls, not just its final answer. The paper describes evaluators identifying syntactically valid but semantically wrong SQL, as well as errors in interpreting forecast-calibration metrics that a human reviewer had initially missed.
In the discovery phase, the authors report 24 novel failures across the agents: nine found through functional testing and 15 through security red-teaming, with no overlap between the groups. Functional tests surfaced issues such as SQL bugs and gaps in tool workflows. Adversarial prompts exposed risks including disclosure of database schema details and storage paths. The authors argue that the two approaches probe different risks and should complement one another.
Stability—and a reporting discrepancy
The paper reports that 35 of 36 configurations met its chosen score-variation threshold. However, its stability summary table lists five Agenta, 12 PromptFoo, and 12 Strands configurations—a total of 29. The supplied paper text does not reconcile these counts, so the reported percentage should be treated cautiously rather than as a settled summary.
The authors also distinguish stable scores from useful judgments. Agenta’s deterministic checks were perfectly consistent, but performed poorly on open-ended answers. AI-judge consistency varied with both the framework and the judge model; one configuration was notably unstable. The authors caution that these evaluations are not reliable enough, as tested, to serve as automated deployment gates.
What the results do—and don’t—show
The central takeaway is that an evaluator’s evidence matters. Access to tool-use traces can help assess whether an agent’s actions and claims match the data, while red-teaming can probe security failures ordinary analytical queries may not expose. The authors recommend pairing trace-based functional evaluation with adversarial security testing.
This is a controlled comparison, not proof that the approach will work equally well for other agents or organizations. It covers two agents in one supply-chain forecasting context, uses frozen traces, and relies on expert-labeled cases. Results may depend on the selected frameworks, models, prompts, and scoring thresholds. The authors also say they did not test whether the evaluations reliably detect improvements or regressions after an agent changes—an important question for release approval.
This article is based on version 1 of an arXiv preprint, a research manuscript that should be treated as provisional. Although the paper text names a KDD 2026 conference, the supplied evidence does not independently establish peer-review status or whether a later version resolves the stability-count discrepancy. Read the preprint.
- AI agents
- agent evaluation
- LLM-as-a-judge
- red-teaming
- software testing
- enterprise analytics
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
AgentTrustCI checks the paths AI agents take, not just their answers
Supporting evidence: Both studies support the bounded point that evaluating execution details can expose failures not captured by answer-only checks: Zhang et al. report stronger known-risk detection from a trace-based judge than from text-only judging, while Gupta’s prototype rejects a grounded answer reached through a disallowed sequence. The comparison is limited: the former evaluates two analytics agents on frozen traces, while the latter tests deterministic validators on an authored suite and does not establish production accuracy.
Model review: · openai-codex/gpt-6-luna
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2611.14493v1 — Original paper
Excerpt reference:
static/papers/2611.14493v1.md:13-128
Basis: Paper text
Source SHA-256:8d6cd2b149d7f8c72d7a03014fd6211cbe526d50f25b0fbb41e819c3da1cbf642611.06674v1 — Original paper
Excerpt reference:
static/papers/2611.06674v1.md:74-209
Basis: Paper text
Source SHA-256:3cd3f06026f3bac2913a3b6c54942e21ef61662a48845411cde46b5b4d322b352611.06674v1 — Original paper
Excerpt reference:
static/papers/2611.06674v1.md:433-551
Basis: Paper text
Source SHA-256:3cd3f06026f3bac2913a3b6c54942e21ef61662a48845411cde46b5b4d322b35
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
What makes a software repair hard for an AI coding agent?
Source published
Shared keywords: software testing
AgentTrustCI checks the paths AI agents take, not just their answers
Source published
Shared keywords: ai agents, software testing
When the grading system reshapes an AI agent leaderboard
Source published
Shared keywords: agent evaluation, ai agents
When Does Reviewing an AI Agent Actually Help?
Source published
Shared keywords: agent evaluation, ai agents
AI agent benchmarks can lose their rankings before they run out of challenges
Source published
Shared keywords: agent evaluation, ai agents