TRANSMISSION // 2611.14418v1
Can a Small AI Model Save Weight Reads for the Moments That Matter?
Source published
A study tested whether a local language model could use low-precision weights for most tokens, then switch to higher precision when its output looked uncertain. In replayed generations, uncertainty signals often identified where the two precisions would disagree. But a small live test did not establish that this strategy preserves accuracy, and the reported savings are based on a simulated cost model—not measured speed.
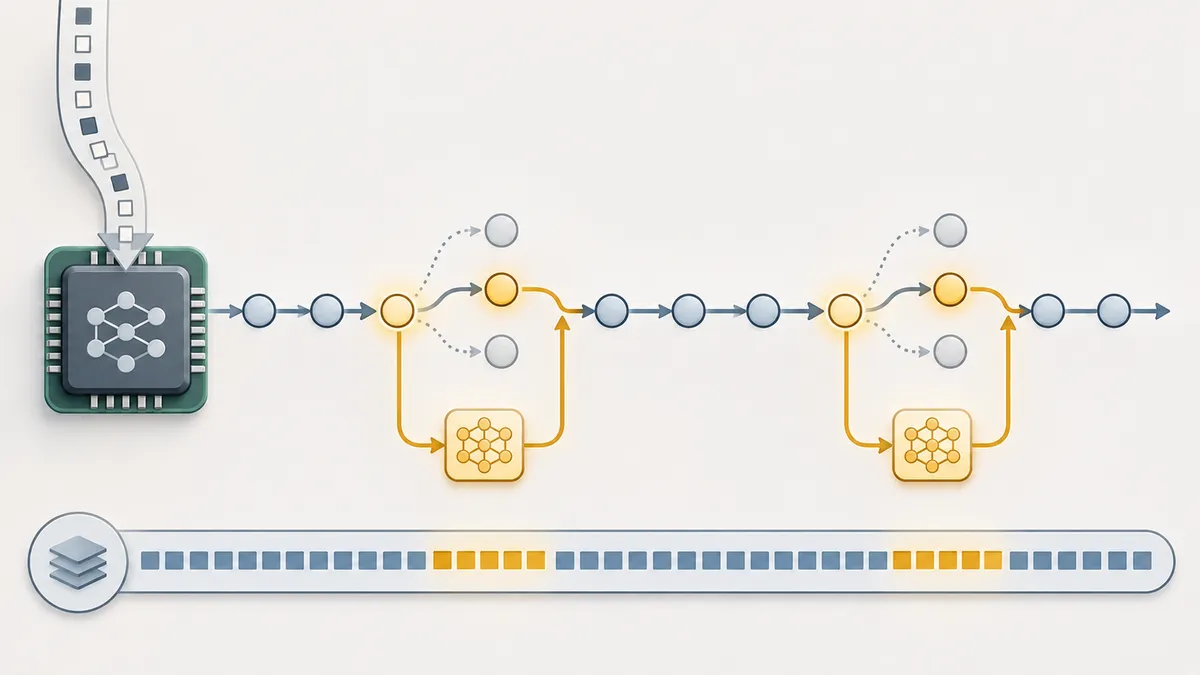
Running a language model locally can mean repeatedly moving its weights from memory. Using fewer bits per weight may reduce that traffic, but can change the model’s output. Instead of choosing one precision for every token, Mohammed Nayeem Khan, Logesh L and Aliyas Ahmad Misri tested a simple alternative: start each decoding step at low precision, and redo it at higher precision if the model’s output appears uncertain. The central question is whether that extra effort is directed to the steps where it helps—and whether the potential savings hold up in actual answers.
A precision switch, not a smaller stored model
The study used Qwen3-0.6B on GSM8K, a benchmark of grade-school maths problems. Its proposed method stores one set of weights as 8-bit values. Each token is first generated using only the top four bits; if a rule flags the resulting output as uncertain, the same step is run again using all eight bits. The full-precision result replaces the low-precision one.
The authors tested two ways to flag uncertainty. One measures entropy: broadly, how spread out the model’s probabilities are across possible next tokens. The other measures the gap between the top two logits, or scores: a narrow gap means the leading choices are close. Both rules look at the low-precision output itself.
The quantization was simulated. The weights were reconstructed as bfloat16 values for computation, rather than run through a packed low-bit inference kernel. To estimate cost, the authors counted weight bytes read per token. This is a useful first-order measure for a memory-bound decoder, but it is not a measurement of runtime or speed.
Uncertainty often marked disagreements in replay
For a replay analysis, the researchers examined 36,724 decoding steps from 150 problems, comparing low- and high-precision outputs along high-precision generation paths. The two versions chose different top tokens on 3.79% of steps. The team then asked whether the uncertainty measures could rank those disagreements highly.
They could. A measure of ranking quality called area under the ROC curve was 0.928 for entropy and 0.959 for the top-two margin; a score of 0.5 would correspond to random ranking. At an escalation budget of about 15% of steps, the entropy rule caught 78% of token-choice flips, while the margin rule caught 94%. A random gate would be expected to catch 15% at that rate. That random figure is a calculated expectation, not the result of a live random-control run.
The two signals did not rank every kind of difference alike. At the same approximate budget, entropy captured 59% of the replay’s total high-versus-low KL divergence, while margin captured 55%. KL divergence compares whole probability distributions, not just which token wins. Thus, the margin signal did better at identifying changes to the top choice, while entropy did slightly better at finding steps accounting for distributional differences in this analysis.
These results are about replayed steps—not final maths accuracy. The replay follows the high-precision path, so it cannot show what happens after an early changed token sends a live generation down a different path. The authors also note that an escalated step is treated as matching the high-precision distribution in their replay estimates.
Live answers leave the key claim uncertain
In a live evaluation of 150 problems, all-high precision scored 64.0% and all-low precision 55.3%. The entropy gate, escalating on 16% of steps, scored 62.7%. Its estimated weight-byte cost was 0.874 times the all-high configuration—about 13% lower in this model. The paired accuracy difference from all-high was −1.3 percentage points, with a 95% interval from −8.0 to +5.3. Against all-low, the difference was +7.3 points, with an interval from 0.0 to +14.7 and a reported p-value of 0.080.
Those intervals are wide. The live results do not establish that the gate matches all-high accuracy, nor do they clearly distinguish it from all-low. The paper describes the all-low comparison with a McNemar p-value of 0.053; its interval for the accuracy difference excludes zero only narrowly. These data offer a signal to investigate, not a settled accuracy result. The study also tested several configurations without correcting those comparisons for multiple testing.
What the test does—and does not—show
The work is a version 0.2 arXiv preprint, not evidence of peer-reviewed validation. Its scope is one small model, one benchmark, one simulated quantizer and greedy decoding. The planned live random control and a proposed “think at low precision, answer at high precision” test were not run. Neither were a second model, live measurements of KL divergence, or packed-kernel timing. The byte accounting excludes factors such as activation and cache traffic, dequantization and kernel overhead.
The study therefore supports a narrow conclusion: on this model’s replayed paths, low-pass uncertainty signals were informative about where low and high precision would disagree. Whether this approach reliably preserves task accuracy or improves real-device performance remains open. A particularly important comparison is verified speculative decoding: in the authors’ replay cost model, it reached zero KL at similar estimated byte cost, though it requires a different inference procedure. Larger live tests, more models and actual hardware measurements would help determine when either approach is worthwhile.
- language models
- quantization
- local AI
- uncertainty gating
- GSM8K
- inference efficiency
- preprint
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
AutoEMatic adjusts AI number precision as a model writes
Shared method: Both studies adapt precision during inference using runtime uncertainty signals: the origin escalates weight precision when output entropy or the top-two margin crosses a threshold, while AutoEMatic uses next-token entropy and layer hidden-state updates to select precision. The comparison is limited to this adaptive-precision approach: the origin tests simulated 4-to-8-bit weight escalation on Qwen3-0.6B/GSM8K, whereas AutoEMatic adapts weights, activations and KV cache with custom formats and hardware; their reported outcomes are not directly comparable.
Model review: · openai-codex/gpt-6-luna
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2611.14418v1 — Original paper
Excerpt reference:
static/papers/2611.14418v1.md:98-215
Basis: Paper text
Source SHA-256:e01acf789519ac6af4b6d49deb7d18f2bcc4f0ff2cb80fb3d82df7f25f416c0a2611.10165v1 — Original paper
Excerpt reference:
static/papers/2611.10165v1.md:13-72
Basis: Paper text
Source SHA-256:e4c300eac13fc13db4c1d9e0c75b45d590774617bb5772e68ea34d2048b6e6cd2611.10165v1 — Original paper
Excerpt reference:
static/papers/2611.10165v1.md:175-243
Basis: Paper text
Source SHA-256:e4c300eac13fc13db4c1d9e0c75b45d590774617bb5772e68ea34d2048b6e6cd
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Training AI drafters to keep more guesses in a row
Source published
Shared keywords: inference efficiency, language models
Trail turns smart home commands into constrained local decisions
Source published
Shared keywords: local ai
AlterNet tests whether language models can learn when to stop computing
Source published
Shared keywords: inference efficiency, language models
Adapting language models by trimming weights, not training them
Source published
Shared keywords: inference efficiency
Can AI agents work with less context? A study tests compact memory and selective reading
Source published
Shared keywords: inference efficiency, language models