TRANSMISSION // 2611.14387v1
Starting the Next Block Before the Current One Is Finished
Source published
A preprint proposes overlapping the denoising of adjacent text blocks to reduce waiting in diffusion language models. Tests on three models and 10 benchmarks report faster generation with broadly similar average benchmark accuracy, but the method is limited to models that can revise tokens, and the measured gains may not carry over to every serving setup.
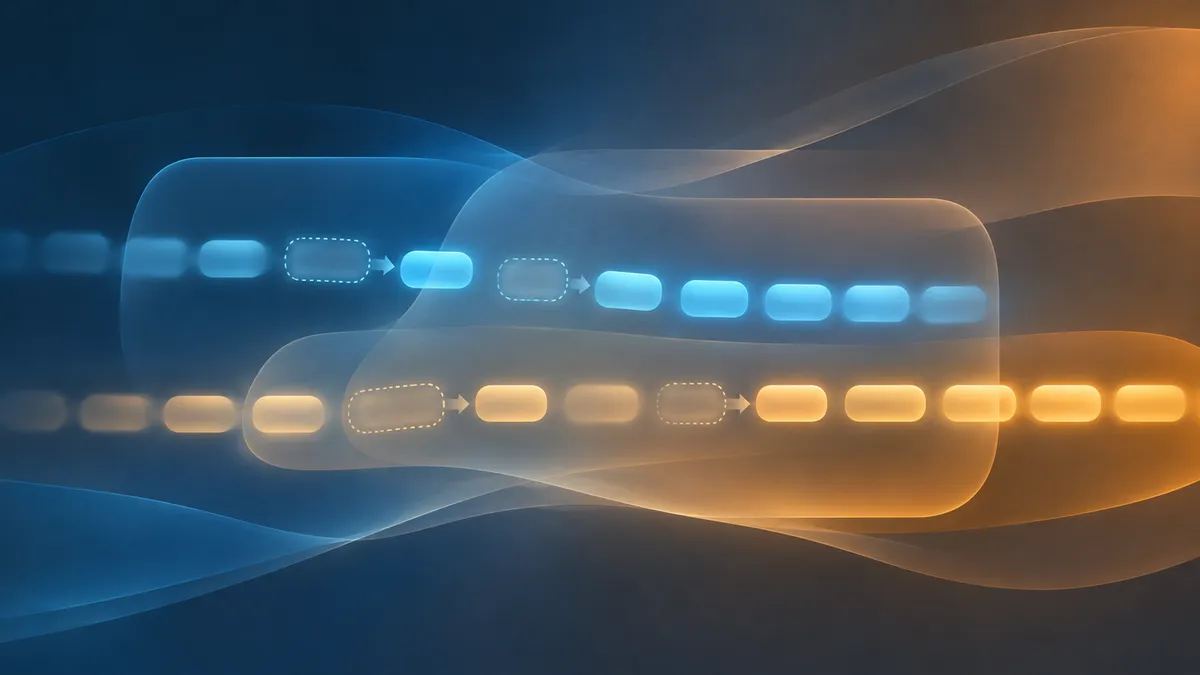
Diffusion language models refine many text tokens in parallel, but block-by-block generation can make an entire next block wait for a few slow tokens. Blurring the Block Boundaries, or B3, tries to use that waiting time by beginning the next block early. How much speed does this save, and what does the evidence say about accuracy and limits?
Diffusion language models generate text differently from the familiar approach of predicting one next token at a time. They begin with corrupted or uncertain tokens and refine multiple positions over repeated model passes. Some systems divide a long response into blocks: each block is refined before the model moves on to the next. That structure can make generation more efficient, but it also creates a bottleneck. If a few tokens in a block take longer to settle, the next block waits—even if it contains easy-to-predict words.
Amir Mann and colleagues propose a way to overlap those stages, called Blurring the Block Boundaries (B3). The central question is whether a model can begin refining the next block while finishing the current one, gaining useful work from forward passes that would otherwise produce relatively few accepted tokens.
How B3 overlaps generation
In ordinary block denoising, the model works on one block at a time. B3 starts the next block once the current block appears settled enough, then processes both in a shared forward pass. The model’s attention rules keep the current block’s predictions from depending on the future block, so those predictions remain the same as in standard decoding.
The challenge is timing. Starting too late leaves little opportunity to save time; starting too early means the next block is conditioned on a prefix that still contains uncertain tokens. B3 uses token-prediction entropy—a measure of uncertainty—to decide when to open the next block. Rather than setting one fixed uncertainty threshold for every model and task, it estimates a suitable threshold from the model’s own acceptance behavior during generation. The authors describe the method as training-free and hyperparameter-free: it does not require additional training or per-task threshold tuning.
B3 also relies on self-editing. Because the next block begins with an unfinished context, some of its early token choices may be wrong. Once the preceding block is finalized, the model can revise tokens in the future block. This ability to edit is not present in every diffusion language model; it is essential to the proposed approach.
What the tests found
The authors evaluated B3 on three models: DiffusionGemma 26B, LLaDA 2.1 mini 16B, and LLaDA 2.1 flash 100B. The tests covered 10 English-language benchmarks, including mathematics, science questions, reasoning, instruction following, and code generation. The paper reports that average throughput, measured as output tokens per second, increased by 11.5% to 14.5% across the three models. A second measure, tokens produced per model forward pass, increased by 15.9% to 19.4%.
Average benchmark accuracy changed by between −0.40 and +0.76 percentage points, depending on the model. That supports the authors’ description of broadly similar average accuracy, not a claim that every task’s result stayed unchanged. Individual benchmark scores sometimes rose and sometimes fell. The paper also reports that B3 improved throughput on all 30 combinations of the three models and 10 benchmarks.
The authors examined why overlap helps. In their measurements, the final part of a block often produced fewer accepted tokens per denoising step than earlier parts. B3 uses those same passes to accept tokens in the next block too. They also measured how often tokens drafted in the future block were later changed: such edits were more common for those tokens than for tokens generated in the ordinary current-block process, but the paper reports that most future-block tokens were kept unchanged in the tested cases.
What remains uncertain
These results describe particular models, benchmarks, and inference implementations—not every diffusion model or deployment. The paper says B3 needs both low-acceptance steps near block endings to exploit and a self-editing mechanism to correct early guesses. Models without self-editing fall outside its scope. The method also assumes that token acceptance tends to progress in a partly left-to-right pattern, as it did in the evaluated models.
B3 is not a verification procedure that guarantees exactly the same output distribution as ordinary decoding. Average accuracy differences were small in these tests, but small average changes do not establish identical outputs or unchanged performance on every prompt. The authors further caution that their wall-clock speedups were measured on one inference setup per model and may differ in other serving conditions, such as large-batch generation. Some comparisons and ablations used only the smaller LLaDA model and a subset of benchmarks because of compute limits; the evaluation was limited to English text tasks.
This is an arXiv preprint, a research manuscript posted for public access. Its findings should be treated as preliminary rather than as independently confirmed results. The reported gains are promising evidence that overlapping adjacent blocks can improve throughput in the tested self-editing models, but broader evaluation is needed to establish how reliably the method transfers to other models and real-world workloads.
- diffusion language models
- text generation
- inference speed
- denoising
- self-editing