TRANSMISSION // 2611.14383v1
One Energy Lens for Many Kinds of Machine Learning
Source published
Bo Dai and Yilun Du’s tutorial proposes energy-based models as a common lens for understanding many machine-learning methods. Its framework separates three choices: how a model assigns energy, how it searches or samples possible answers, and how it learns from data. This is a conceptual synthesis, not a report of new benchmark results, and describing methods within one framework does not mean they are interchangeable.
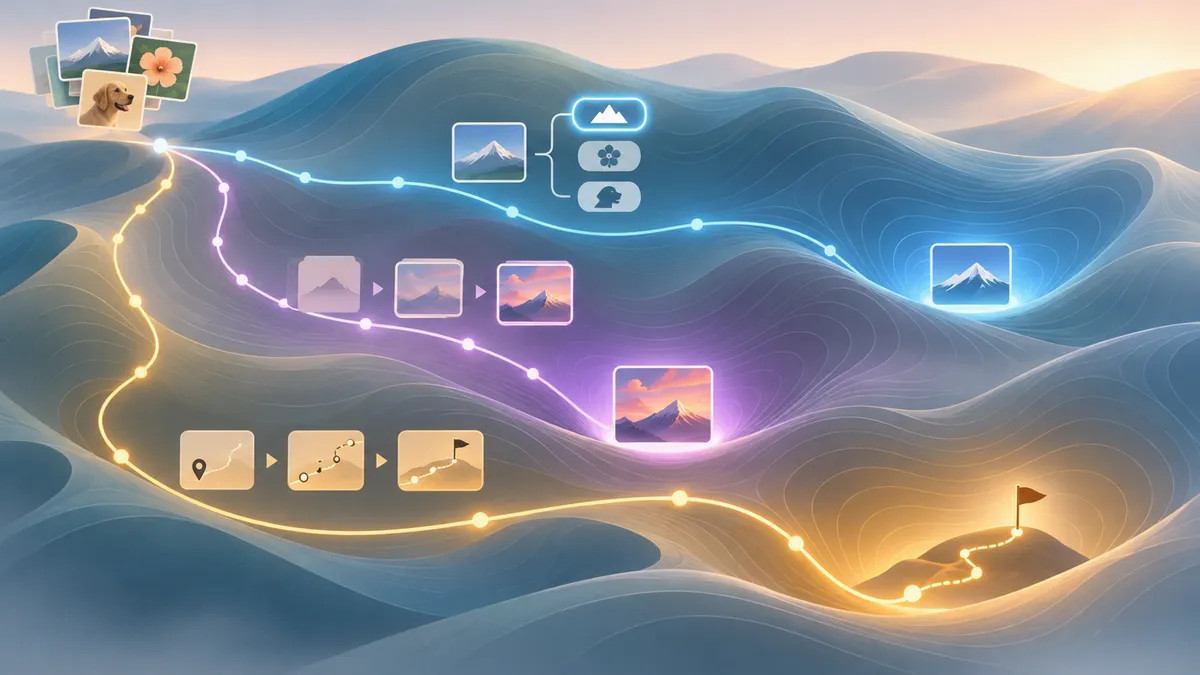
Could classifiers, image generators and planning systems be understood through a shared mathematical idea? A tutorial by Bo Dai and Yilun Du explores that question using energy-based models, or EBMs. Its central proposal is to compare methods by what they score, how they use those scores and how they learn them.
An energy-based model assigns a scalar value, called energy, to possible configurations. In a common formulation, the probability of a configuration is proportional to the exponential of minus its energy. The energy gives a way to express relative compatibility: configurations with lower energy receive greater weight in that distribution. How a system turns those values into predictions or samples depends on its inference procedure.
In “An Energy-Based Perspective on Machine Learning,” Bo Dai and Yilun Du argue that this framework can do more than describe one family of models. They use it to organize approaches that are often taught separately. Their central framework has three ingredients: the energy function, the inference procedure that searches or samples using it, and the learning method that fits it to data.
Three choices shape the model
The energy function represents which configurations fit a task or are preferred. Inference determines how the system uses that function: it may seek a low-energy answer or sample possible answers from the distribution. Learning adjusts the function using data. These are distinct choices, even when they interact. Two systems might be expressed with related energy functions but use different inference or training procedures.
The authors discuss learning methods including maximum likelihood, noise-contrastive estimation, pseudolikelihood, score matching and adversarial training. They describe these methods as sharing a contrastive structure. The abstract—the only paper evidence available for this account—does not provide the derivations or qualifications behind that claim. Here, it is best read as the tutorial’s proposed organizing idea, not as evidence that the methods are identical in practice.
Familiar methods, reframed
The tutorial applies its lens to systems not usually introduced as energy-based models. It includes discriminative models and generative approaches such as GANs, normalizing flows, diffusion models and autoregressive models. It also covers representation-learning methods, including contrastive learning, word2vec, BERT, denoising autoencoders and diffusion representations.
The proposed connections extend to reinforcement learning, including policies and world models, as well as inverse reinforcement learning and planning. The authors also discuss inference-time computation with verifiers. Across these cases, they say that methods often differ in how they handle the partition function—the quantity used to normalize an energy-defined probability distribution—and how they perform sampling or inference.
The framework offers a practical set of questions for comparing methods: What does the system score? How does it find or sample an answer? What learning signal changes the score? Dai and Du suggest that researchers can use this breakdown to understand existing methods and develop algorithms by replacing one component while keeping others fixed. They also propose composing energies as a way to combine learned models at inference time. The abstract presents these as possibilities, not as experimentally demonstrated improvements.
A framework, not a performance result
The source supplied for this account is the paper’s abstract, which describes the work as a tutorial. It reports no particular dataset, benchmark or measured improvement. The contribution described here is therefore conceptual organization, not evidence that one implementation outperforms another or that the methods grouped together behave equivalently in practical settings.
The breadth of the framework makes precision important. Describing many methods in energy-based terms may reveal shared structure, but it does not by itself remove differences in objectives, computation, sampling difficulty or behavior. Evaluating how fully the tutorial supports its connections requires reading the complete paper, rather than relying on the abstract alone.
This is an arXiv preprint, version 1; the supplied evidence does not establish peer-review status. The abstract supports the broad scope and the three-part framework, but it cannot substantiate the tutorial’s detailed technical arguments. The proposal is best treated as a map for exploring relationships among machine-learning methods—not as settled consensus or a new experimental result. Its usefulness depends on whether the full treatment makes the connections precise while preserving the distinctions among methods.
- energy-based models
- machine learning
- generative models
- inference
- representation learning
- reinforcement learning
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
LEF-JEPA targets object structure without preserving every visual detail
Source published
Shared keywords: energy based models
Quantum-derived inputs reshape a malware detector, with no clear final detection edge over a dimension-matched Gaussian model
Source published
Shared keywords: generative models
ZeroPoint gives a small decision model a way to choose nothing
Source published
Shared keywords: energy based models
What should an AI explore before it has a task?
Source published
Shared keywords: reinforcement learning
FlowAlign uses learned paths to align different kinds of data
Source published
Shared keywords: representation learning