TRANSMISSION // 2611.14285v1
A shared test bench for predicting how LLMs train
Source published
LM-SimBench combines a framework, profiling dataset and benchmark to compare simulators of distributed large-language-model training. Its experiments show how predictions can be checked against real runs—and where errors in memory or communication estimates may affect configuration choices.
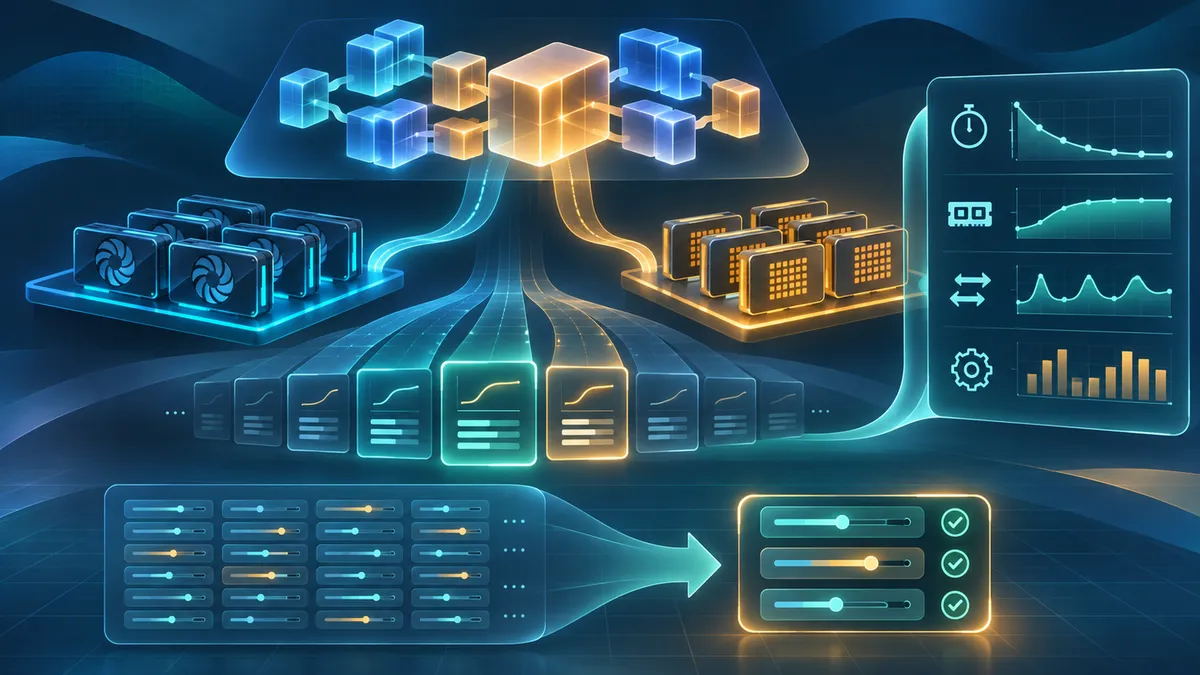
Choosing how to divide a large model’s training across many devices is a costly systems problem. A simulator could help researchers test options before running them on hardware, but comparisons are hard when tools are evaluated on different workloads and measurements. LM-SimBench proposes a common framework for those comparisons.
Training a large language model across many accelerators involves choices about how to split computation and data. These choices affect how long each training iteration takes, how much memory each device needs and whether devices spend time waiting for one another. Testing every possible setup with a real distributed training run can be expensive. Simulators offer a cheaper way to estimate performance—but their predictions are only useful if researchers can assess how well they work.
That is the problem addressed by LM-SimBench, a preprint presenting a framework, profiling dataset and benchmark for evaluating simulators of large-language-model training. The authors argue that existing simulators are difficult to compare fairly because they may model different parts of training and use different hardware, software and workloads for evaluation.
From model description to predicted runtime
The framework breaks simulation into stages: compiling a model for a chosen training strategy, assigning its parts to devices, representing the resulting execution, estimating computation and communication costs, and combining those estimates into predictions for a full training iteration. The stages matter because a simulator can make errors at several levels. It might estimate the time for a particular operation poorly, for example, or fail to capture how communication overlaps with computation.
LM-SimBench links predictions to measurements from the same training runs. Its primary dataset contains profiles for 23 model settings from 10 dense and mixture-of-experts model families, collected on an Ascend 910B3 NPU cluster. Across 348 feasible configurations, the dataset varies five forms of parallelism—data, tensor, pipeline, context and expert parallelism—as well as activation recomputation, a technique that can trade extra computation for lower memory use.
Measurements are organized into six linked views, from overall iteration time and peak memory to rank-level timing, operator latencies, communication events and matrix-kernel data. This makes it possible to compare a simulator’s final prediction with the underlying parts of the run, rather than judging it only by one runtime estimate.
Accuracy is not the whole story
The paper demonstrates the benchmark with two simulators, Calculon and vTrain, on Qwen1.5-1.8B at an 8K-token sequence length. In the six test configurations where both tools produced valid predictions, vTrain’s iteration-time predictions had a lower reported percentage error and more closely matched the measured ranking. Both tools identified the fastest measured configuration and the measured top three. Calculon, however, ran faster as a simulator in this test: its median time per configuration was 1.78 milliseconds, compared with 25.46 milliseconds for vTrain.
The authors also show why looking inside predictions can be useful. In one analysis, Calculon’s memory model retained 13 of 20 configurations that measurements showed were feasible. In another, vTrain’s estimate of non-overlapped communication time had a high error, which the authors connect to differences between its serialized communication estimates and the overlap observed in training profiles. These examples suggest that a simulator’s overall runtime score may not reveal every weakness relevant to choosing a configuration.
A separate experiment tested whether NPU measurements could help narrow configuration choices for NVIDIA V100 GPUs. The paired measurements covered two Qwen3 models and only a subset of candidate configurations. For both models, the three fastest configurations on the NPU included the GPU’s fastest option among the paired candidates. This is evidence that cross-platform measurements can help screen options in this particular setup—not that the same shortlist will work for other models or hardware.
What the results do—and do not—show
The resource is designed to support more consistent simulator evaluation and diagnosis, not to establish a universal winner. The simulator comparison uses a small shared test set, and the cross-platform experiment covers two models, two accelerator types and a limited candidate set. The GPU and NPU runs also differ in software stack and some execution settings, including precision and kernel options. Results therefore need to be interpreted within those experimental conditions.
The dataset is a collection of controlled training profiles, not a benchmark of model quality, safety or fairness, and it does not cover serving behavior. The authors themselves point to broader workload and accelerator coverage as a way to extend the resource. LM-SimBench’s contribution is chiefly methodological: it links system-level predictions to component-level measurements and configuration choices, offering a shared basis for asking where a simulator works, where it falls short and whether its recommendations are useful.
The paper is an arXiv preprint, and its claims should be treated as provisional rather than as independently established conclusions. The supplied source describes the experiments and reports public code and dataset resources; further assessment would benefit from replication across additional models, systems and simulator implementations.
- large language models
- distributed training
- performance simulation
- benchmarking
- parallel computing
- accelerators
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
DataHelix coordinates data preparation to keep AI training moving
Source published
Shared keywords: distributed training
Split-KV aims to make long-context drafter training faster
Source published
Shared keywords: distributed training
FP4Quant speeds up GPU communication, with a measurable accuracy trade-off
Source published
Shared keywords: distributed training, large language models
AMD researchers test ways to keep training data moving through GPUs
Source published
Shared keywords: distributed training
When Should an AI Agent Remember? Test the Lesson Before Keeping It
Source published
Shared keywords: large language models