TRANSMISSION // 2611.14211v1
Can routers prioritize AI-agent traffic without trusting every label?
Source published
A preprint proposes a marked, rate-limited router class with behavioral checks for traffic claiming to come from AI agents. In a constructed simulation burst, it cut average agent queuing delay by 98% versus static DiffServ, assuming an immediate classifier verdict—an upper bound—and increased human delay in that scenario. A five-seed sandbox test caught 20 bulk-shaped spoofers, but six deliberately added pattern-copying mimics passed. Emulated network delay also impaired one timing feature. These results are not evidence of reliable agent identification or production performance.
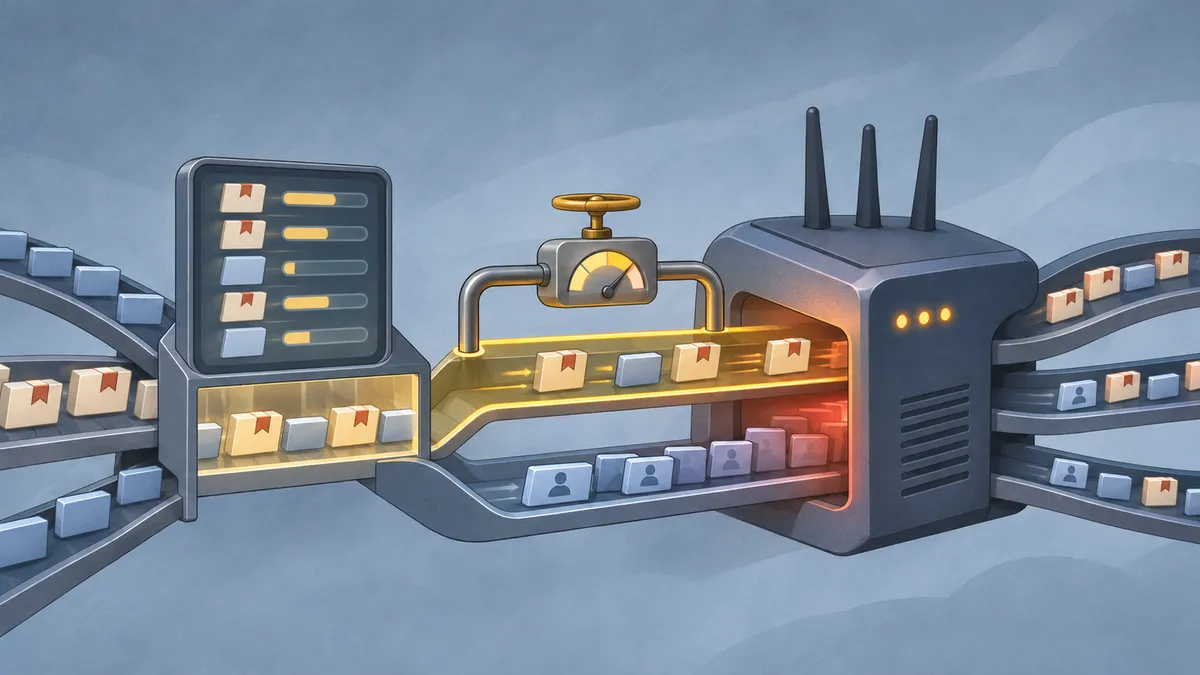
AI agents make linked requests to models and tools, so delays in a congested router queue can add up. Giving those requests priority raises a basic problem: a sender might claim the priority label without being an agent. A preprint by Naveen Babu Narayanan Nair and Sajay Kurup proposes a router policy that combines a marked traffic class, behavioral checks and a rate cap. Its tests explore both the possible benefits and the limits of those checks.
An AI agent may call a model, use a tool and then make another request. When a network link is congested, each exchange can wait in a router queue. The authors argue that standard router quality-of-service systems do not provide a class specifically for this kind of agent traffic. But a priority label by itself would be easy to misuse: other traffic could claim it too.
Nair and Kurup propose the Verifiable Agentic Traffic Class (VATC). It combines a packet marking that declares agent traffic, a router-side classifier that can demote flows whose observed behavior conflicts with the declaration, and a priority queue with a rate cap. The cap limits how much marked traffic can use the link, including while a classifier decision is pending or mistaken. The marking used in the tests was a stand-in; a real deployment would need a reserved codepoint pool. The design also proposes a trusted gateway to supply a tool-chain hop count, a feature that was not exercised in the experiments.
What the researchers tested
The comparisons included static Differentiated Services (DiffServ), which assigns traffic to classes, and Linux’s fq_codel, which combines per-flow queues with CoDel queue management and favors sparse flows. The simulator’s fair-queuing comparison was only the per-flow fairness component: it did not include packet drops, sender feedback or sparse-flow priority.
The evaluation used a custom simulator, a second simulator, and Linux traffic-control experiments with real TCP traffic. The second simulator reused the first simulator’s flow population and classifier verdicts, so it checked scheduler code rather than independently validating the traffic or classifier results. The authors also ran two agent harnesses through a congested virtual network to estimate the time spent waiting in router queues.
Much of the traffic was generated from assumed characteristics informed by published AI-inference statistics. A scenario in which many agent and human flows arrive together was a constructed, uncalibrated stress test—not a measured production event.
Benefits depend on the scenario
In the synthetic steady-load simulation, VATC and static DiffServ had near-zero queuing latency for human and legitimate agent traffic. VATC showed no advantage over DiffServ in that scenario.
In the constructed burst simulation, VATC reduced mean agent queuing delay by 98% relative to DiffServ, while mean delay for the concurrent human surge rose by about 12%. Those figures describe that particular scenario, not a general performance trade-off. The 98% result assumes an immediate classifier verdict; the authors describe it as an upper bound, and simulated verdict delays reduced the benefit. Their ablation found that most of the burst improvement came from putting agent traffic in a separate class, rather than from the agent-specific classifier.
In the real-harness experiment, a 20 Mbit/s virtual link carried synthetic background load while two harnesses made plain HTTP calls without streaming responses. Model latency was assumed, and verification was bypassed. Depending on the harness and assumed model latency of 0.5 to 5 seconds per call, router queueing accounted for 13% to 63% of task time. Static DiffServ and VATC removed most of the extra time in this setup, but the dedicated agent class added no measurable benefit over DiffServ. These are sandbox measurements, not production observations or estimates of savings attributable specifically to VATC.
Spoofing and classifier limits
In a five-seed Linux network-namespace test, a live four-feature classifier demoted all 20 bulk-shaped spoofed sessions and measured 0.30 ms mean latency for legitimate agent traffic. The verifier was trained and tested on traffic from the researchers’ generator and did not use the proposed hop-count feature. This result applies to those bulk-shaped flows, not to spoofers in general.
The researchers also added six mimic sessions that copied the agent message pattern. Across five seeds, the classifier demoted 0 of 30 such sessions. This does not show how common mimics are; it shows that the tested features did not reliably distinguish these examples. Without verification, legitimate agents had higher latency under VATC than under DiffServ in the tested flood. With the live verifier, the cap kept human latency at 0.059 ms versus 0.65 ms under DiffServ in that particular test. These measurements do not establish a universal bound for other networks or cap settings.
Emulated network delay exposed another limitation. The inter-arrival-time variation feature that separated agent and human flows on a local link lost that separation at higher emulated round-trip times. A verifier trained on local-link traffic also transferred poorly to delayed paths. Training on matching or pooled delays restored a usable operating point at 20 ms and helped only partly at 80 and 150 ms in the virtual-machine tests, which had no loss or jitter. This is evidence about one feature and test setup, not proof that every classifier fails on wide-area traffic.
The paper is a preprint submitted to IEEE for possible publication; the supplied evidence does not establish peer-review or publication status. Its synthetic traffic, constructed bursts, virtual-network tests and unexercised gateway channel leave important questions for real deployments. VATC is a proposal whose performance depends on traffic, classifier limits, verdict timing and how the rate cap is configured—not a demonstrated way to verify agent identity.
- AI agents
- network quality of service
- router queues
- DiffServ
- traffic scheduling
- preprint
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Following AI agents over time reveals patterns that benchmarks can miss
Source published
Shared keywords: ai agents
Can a social network make AI agents answerable to people?
Source published
Shared keywords: ai agents
AI agents test quantum-spin predictions and flag a drifting signal
Source published
Shared keywords: ai agents
When AI agents change, should their permissions change too?
Source published
Shared keywords: ai agents
When AI Agents Agree, Their Majority Can Still Be Wrong
Source published
Shared keywords: ai agents