TRANSMISSION // 2611.14168v1
Can neural networks have representational atoms?
Source published
A preprint proposes a framework for defining and evaluating fundamental representational units (FRUs) in neural networks. Its authors say threshold-activated sparse autoencoders can identify these units with high fidelity and stability under specified conditions. They also report that more stable FRUs show greater monosemanticity and that FRUs can be composed across layers to recover semantic organization related to human conceptual structure. Because the available evidence is only the abstract, the methods, experimental scope and generality of these claims remain difficult to assess.
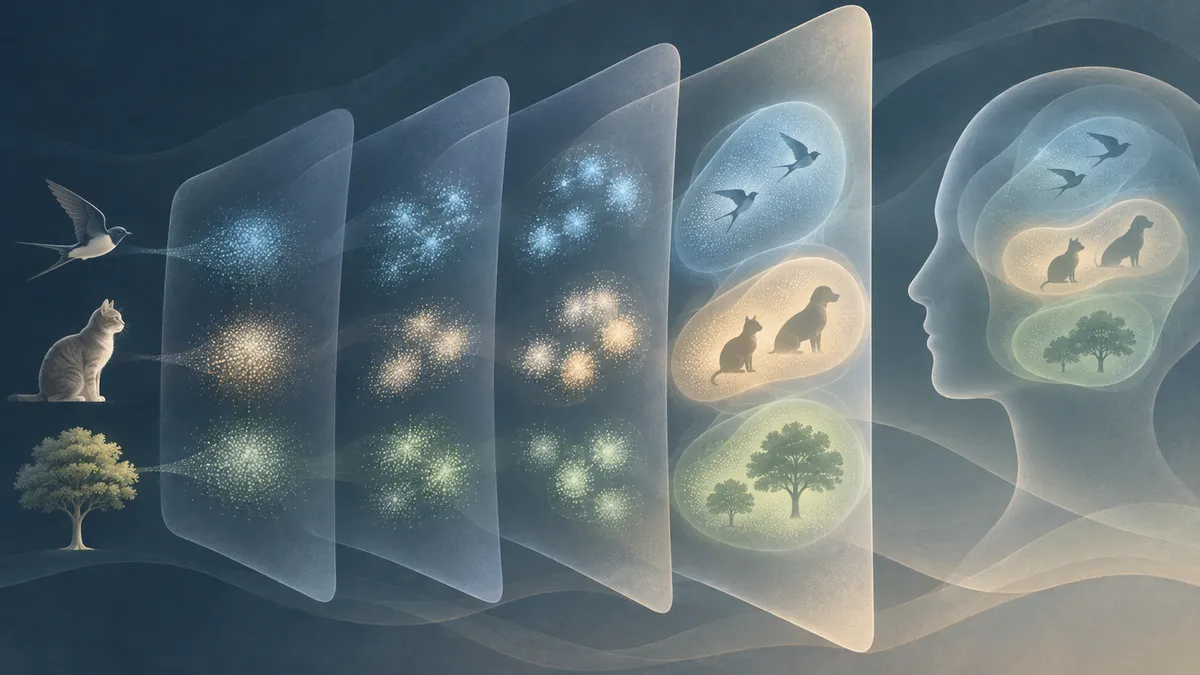
How can researchers define basic units in a neural network’s internal representations, and test whether those units are reliable? Chenhui Hu and colleagues propose “fundamental representational units,” or FRUs, and set out criteria for evaluating them. This account is based on the paper’s abstract, not its full methods and results.
Defining candidate units
Neural networks develop internal representations as they learn, but describing their organization—and relating it to human concepts—is a challenge. In Representational Atoms in Neural Networks, Chenhui Hu, Pengfei Cao, Kang Liu and Jun Zhao propose a framework for investigating that challenge. They formally define what they call fundamental representational units (FRUs) and introduce two criteria for evaluating them: fidelity and stability.
The abstract does not provide the formal definitions of either criterion. It therefore supports saying that fidelity and stability are central to the authors’ evaluation framework, but not specifying exactly how either is measured or what makes a unit pass those tests.
The proposed identification method
The authors say they prove that threshold-activated sparse autoencoders (TSAEs) can identify FRUs with high fidelity and stability under appropriate conditions. The abstract does not explain the architecture or operation of TSAEs, nor does it list the conditions required for the proof. The claim is conditional: it does not say the method will identify FRUs successfully in every network or setting.
The abstract also reports large-scale experiments that validate the result. It does not identify the models, data, experimental procedures, comparison methods or numerical outcomes. As a result, the abstract alone cannot show how the experiments relate to the proof’s conditions or how broadly the evidence applies.
What the authors report
The authors report that FRUs with higher stability exhibit greater monosemanticity. The abstract does not define that term or explain how the relationship was assessed, so its precise meaning and measurement cannot be established from the information available here. The reported relationship should not be read as evidence that stability causes monosemanticity.
They also say FRUs can be composed across layers to recover semantic organization corresponding to human conceptual structure. This suggests a proposed way to connect units identified within a network to a broader organization of meaning. But the abstract does not describe the composition procedure, the human conceptual structures used for comparison, or the degree of correspondence found.
Taken together, the work aims to provide a shared framework for defining, evaluating and identifying FRUs, and for studying how neural-network representations relate to human conceptual structure. The abstract presents this as a foundation for further characterization, rather than establishing that network representations are identical to human concepts.
What remains uncertain
This article is based on the abstract alone. Without the full paper, it is not possible to assess the formal definitions, assumptions behind the proof, experimental design, quantitative results, or possible limitations and failure cases. Nor can the available evidence establish whether the method and findings generalize across architectures, tasks or other settings.
The source is an arXiv preprint. A preprint is a publicly available research manuscript; its presence on arXiv does not by itself establish peer review. The abstract describes a theoretical result and large-scale experimental validation, but offers too little detail to independently evaluate either. The proposal is therefore best treated as a framework whose claims need assessment against the full paper and further evidence, not as proof of a universal set of conceptual building blocks in neural networks.
- neural networks
- interpretability
- sparse autoencoders
- internal representations
- machine learning
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
Inside a neutrino AI, useful physics can sit unused
Shared method: Both papers use sparse autoencoders to identify interpretable features in model representations. Hu et al. focus on whether threshold-activated SAEs identify units with fidelity and stability; Bonnet-Guerrini et al. use SAEs to build and causally test a validated atlas in an IceCube neutrino model. The shared SAE approach does not make their findings directly comparable: the models, tasks, and evaluation criteria differ.
Model review: · openai-codex/gpt-6-luna
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2611.14168v1 — Original paper
Excerpt reference:
static/papers/2611.14168v1.md:60-99
Basis: Paper text
Source SHA-256:29a97a251154652c5ee4598b2ea8c06e0ef898b5ab7b9dd4cb351ced390b14492608.26090v2 — Original paper
Excerpt reference:
static/papers/2608.26090v2.md:117-164
Basis: Paper text
Source SHA-256:6025ccb240a3ff5ded62675c5cc4b7922801c946a96f57a2198e1a58f3ff3356
A Financial Brain Scan for AI—and a Warning About Its Explanations
Shared method: Both papers use sparse autoencoders to expose and intervene on features in pretrained model representations. Hu et al. assess candidate units using fidelity and stability and study their semantic composition; Chen et al. apply SAE features to financial concepts and test steering in economic tasks. These are related uses of SAEs, not evidence that either paper validates the other’s claims or that their results generalize across model domains.
Model review: · openai-codex/gpt-6-luna
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2611.14168v1 — Original paper
Excerpt reference:
static/papers/2611.14168v1.md:60-99
Basis: Paper text
Source SHA-256:29a97a251154652c5ee4598b2ea8c06e0ef898b5ab7b9dd4cb351ced390b14492508.21285v4 — Original paper
Excerpt reference:
static/papers/2508.21285v4.md:58-134
Basis: Paper text
Source SHA-256:88daa2e8b2c19ff9242b97d1c1af3648c45c828539f52ef5356c9e9f495efc54
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Editing a Robot Model’s Hidden Goal Without Changing Its Instructions
Source published
Shared keywords: sparse autoencoders
Inside a neutrino AI, useful physics can sit unused
Source published
Shared keywords: sparse autoencoders
Glyph turns hidden medical AI features into testable disease-risk clues
Source published
Shared keywords: sparse autoencoders
SteerGR shifts game recommendations by editing a model’s internal features
Source published
Shared keywords: sparse autoencoders
Tracing the Internal Signals Behind Language Model Reasoning
Source published
Shared keywords: sparse autoencoders