TRANSMISSION // 2611.14019v1
Teaching AI agents to patch their skills with code
Source published
PASE separates an AI agent’s written guidance from reusable procedures encoded as programs, then tests proposed updates before keeping them. In spreadsheet and table benchmarks, the authors report better results than the compared skill-evolution methods, but the evidence is limited to particular models and tasks.
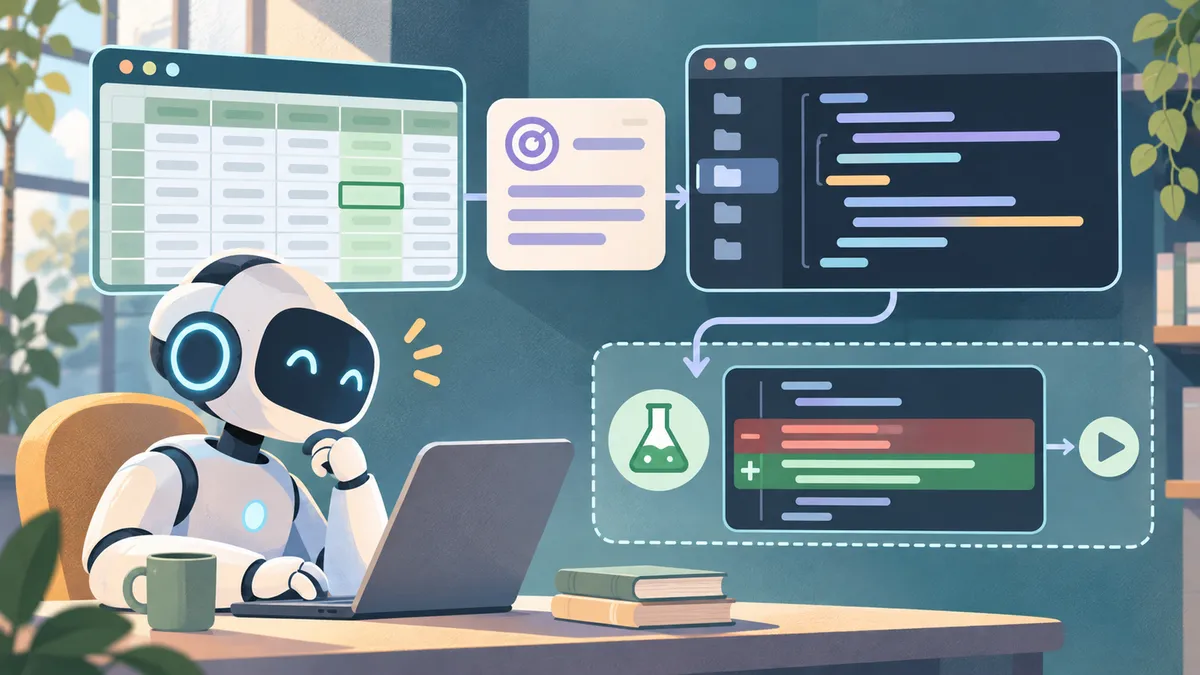
When an AI agent makes the same kind of mistake repeatedly, can it learn a reusable fix without changing the underlying language model? A preprint called PASE explores one answer: keep general guidance in text, move repeatable procedures into editable programs, and evaluate updates before accepting them.
The problem: lessons can be hard to maintain
AI agents can be given “skills”: reusable instructions and procedures that help them complete tasks such as editing a spreadsheet. Some systems also try to improve those skills by examining records of earlier attempts. The difficulty, the authors argue, is that many such systems store both general advice and step-by-step procedures in one natural-language document. When a procedure needs fixing, changing the text may also alter nearby guidance—or leave the intended action ambiguous.
The paper introduces PASE, short for Program-Aided Patchable Skill Evolution. Its central idea is to keep a skill’s high-level strategy in readable text while representing recurring procedures as executable programs. The two parts can be updated separately or together. In principle, that makes a specific repair easier to target without rewriting the whole skill.
How the system learns
PASE starts with task attempts and their execution traces: records of what the agent did and what the environment returned. The update process samples both successful and failed attempts. Successes may reveal useful routines; failures may help identify what went wrong.
A language-model-based proposer reviews selected traces and relevant existing skills, programs and earlier patch proposals. Rather than loading everything into its context at once, it can retrieve particular information as needed. It then proposes a patch—creating, repairing or deleting a skill, a program, or both. Repairs can make line-level changes to the relevant component.
The system does not automatically keep every proposed change. It evaluates the patched version on a held-out validation set and accepts it only if its validation performance improves. This gate is intended to reduce the chance that a change merely fits the examples used to develop it. The study also tests removing individual components, including program evolution and on-demand information access, to examine how they contribute.
The experiments focus on spreadsheet work. They use SpreadsheetBench, including a 400-task expert-verified subset for skill evolution, and Domain-Spreadsheet, which covers professional areas such as finance and human resources. The authors also test table-question-answering benchmarks, converting tables into spreadsheet tasks. They compare PASE with agents using no skills, a human-written spreadsheet skill, an LLM-generated skill, and two skill-evolution approaches, Trace2Skill and EvoSkill. The same backbone model and inference prompt are used for the compared methods. Three models are included, from the Qwen and Gemma families, and the evolution process is repeated across three runs.
What the authors report
Across the tested models and benchmarks, PASE generally scores higher than the comparison methods. For one model, Qwen3.6-27B, the reported overall average is 62.79 for PASE, compared with 58.27 for EvoSkill and 57.03 for Trace2Skill. These are the paper’s benchmark results, not a guarantee of improvement in other settings. The authors also report gains on the out-of-domain spreadsheet and table-question-answering evaluations, suggesting that the evolved skills helped beyond the examples used to develop them.
In an ablation study using Qwen3.6-27B, removing program evolution lowered the reported overall average from 69.28 to 64.54. Removing adaptive reading or skill updating also reduced the score. These comparisons support the authors’ view that the components work together in their tested setup; they do not establish that programs will help every agent or task.
The paper further reports that PASE’s performance fluctuated less across evolution rounds than a version without programs. Its analysis says programs were involved in 62.2% of proposed updates, either alone or alongside text changes. A case study illustrates the intended benefit: a program can perform an exact lookup in a spreadsheet, while the written skill says to trust the reference table rather than guess when a lookup fails.
What remains uncertain
The results concern spreadsheet manipulation and table tasks, not a broad range of real-world agent work. The researchers deliberately supplied active skills directly to the agent, so the experiments do not test how well a system retrieves the right skill from a large, growing library. Programs also need to be explicitly invoked; the paper notes that an agent might instead carry out the procedure another way. And because validation accepts only updates that improve the validation score, it may reject changes that have no immediate gain but could be useful later.
These findings come from a preprint, which may not have undergone peer review. The source reports benchmark comparisons, but those scores do not by themselves show how the approach performs in deployment, where tasks, software and failure costs can differ. The authors say they plan to release the data and code via GitHub; the paper text provided here does not establish that they are already available. Source: arXiv:2611.14019v1.
- AI agents
- large language models
- agent skills
- program-aided learning
- spreadsheet benchmarks
- preprint
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
EvoML checks machine-learning workflows in stages and saves successful fixes
Shared method: Both frameworks use execution experience to refine reusable, executable skill-related artifacts across tasks: PASE jointly patches skills and associated programs from agent trajectories, while EvoML’s Curator uses validation and retry traces to evolve its skill library after runs. EvoML additionally uses expert-grounded workflows and stage validation; the papers study different tasks, so this is a methodological connection, not a performance comparison.
Model review: · openai-codex/gpt-6-luna
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2611.14019v1 — Original paper
Excerpt reference:
static/papers/2611.14019v1.md:255-378
Basis: Paper text
Source SHA-256:455552bdd02c90fe15a1397363c2bf21a67746046f295d403c6734a0267e22d92611.04180v1 — Original paper
Excerpt reference:
static/papers/2611.04180v1.md:194-255
Basis: Paper text
Source SHA-256:eb982182203771fb7df2f917695151f03c8f4e421b48ec59300d723eee1bb3e42611.04180v1 — Original paper
Excerpt reference:
static/papers/2611.04180v1.md:321-379
Basis: Paper text
Source SHA-256:eb982182203771fb7df2f917695151f03c8f4e421b48ec59300d723eee1bb3e4
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Poisoned reference answers can plant persistent rules in AI agent skills
Source published
Shared keywords: ai agents
Keeping AI workflow instructions separate from implementation know-how
Source published
Shared keywords: ai agents
AI models know time’s rules but struggle to predict their own runtimes
Source published
Shared keywords: ai agents, large language models
When AI Agents Agree, Their Majority Can Still Be Wrong
Source published
Shared keywords: ai agents, large language models
When graphs help AI agents—and why better retrieval is not enough
Source published
Shared keywords: ai agents, large language models