TRANSMISSION // 2611.13946v1
TreeAgent gives AI memory a map of the data it reads
Source published
When AI agents read long, structured material, splitting it into equal-sized text chunks can separate related fields and hide where information belongs. TreeAgent tries a different approach: it uses the data’s hierarchy to build chunks, label their locations and reconnect selected earlier details. In tests across four data formats and four existing memory agents, it raised the average answer score by 3.61 percentage points. The result is promising, but limited to the paper’s designed retrieval and aggregation tasks; it does not establish how the method performs across all real-world documents or applications.
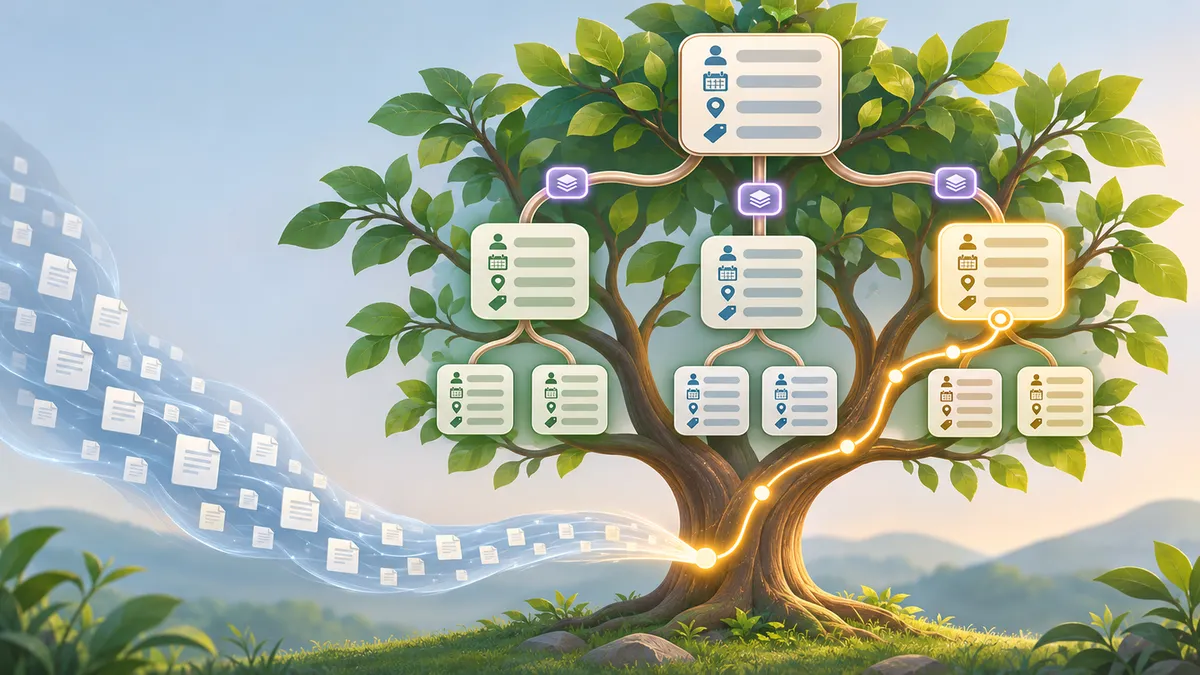
A long API response is not just a stream of words: it is a collection of nested records, each with fields that belong together. If an AI agent breaks that response into fixed-size chunks, a record’s pieces may land in different chunks, and the agent may lose track of their relationship. TreeAgent, a research system described in an arXiv preprint, asks whether respecting the data’s built-in structure can help agents remember and answer questions about it.
When a language-model agent has to process more text than fits in its context window, one option is to read the material in pieces and carry a compact memory from one piece to the next. That memory is bounded: it cannot preserve every detail indefinitely. For structured data such as JSON, HTML or YAML, ordinary fixed-length chunks create a further problem. They can split fields from the same record, strip away clues about where a chunk belongs, or leave useful details from earlier records unavailable when the agent later needs to compare them.
TreeAgent is designed to address those issues. Rather than treating the input as a flat string, it uses the data’s hierarchy to decide what to read together and what earlier information to revisit. The paper evaluates whether these structural cues improve existing memory agents on questions involving retrieval and simple aggregation.
Chunks that respect the tree
TreeAgent represents hierarchical input as a tree: parent nodes contain children, and siblings retain their original order. Where the token budget allows, it keeps a complete subtree—such as a record and its fields—within one segment. It can also group neighboring sibling subtrees to use the available space. Oversized parts are divided recursively; some indivisible elements may exceed the nominal budget.
Each segment receives a structural path, a compact description of its location in the larger input. A path can tell the agent, for example, that a segment comes from a particular record group rather than presenting it as an isolated passage.
The third component addresses memory loss across successive updates. TreeAgent saves the memory state after processing each segment and creates links between child and parent portions of the original hierarchy. When processing a parent’s final segment, the agent can retrieve selected spans from linked earlier memory states. The question guides this retrieval: TreeAgent ranks spans by lexical overlap and supplies a limited number of them alongside the current segment and its path. The existing memory agent still performs its usual update and answer procedures.
What the researchers tested
The authors integrated TreeAgent into four existing systems—MemAgent, InfMem, MemReread and ReMemR1—without additional training in the main comparison. Each system was tested with its usual fixed-length segmentation and with TreeAgent, while keeping model parameters and memory-update and answering procedures the same within that system.
The evaluation used four datasets drawn from application data in JSON, HTML, YAML and JavaScript, with input lengths from 8,000 to 1 million tokens. The JavaScript material consisted of statically extracted objects and arrays, not running programs. Eight task types tested questions such as retrieving fields from one or several records, counting records that meet a condition, identifying frequent values and finding numerical extremes. The reported results average answer scores across tasks and input lengths, and then across datasets and agents.
A consistent average gain, with uneven results
Across the four agents and four datasets, the mean answer score rose from 39.49% with fixed-length chunks to 43.10% with TreeAgent—a gain of 3.61 percentage points. All four agents improved when averaged across the datasets, although the size of the gain varied: the paper reports larger average gains for InfMem and MemReread than for MemAgent and ReMemR1. TreeAgent scored higher in 14 of the 16 agent-by-dataset comparisons.
The authors also report higher scores in 31 of 32 comparisons across agents and input lengths, including for all four agents at the longest tested length. In component tests, structural chunking improved the average score first; adding paths and then linked-memory retrieval brought further gains. The full system increased model calls by 3.7% to 7.6% in the reported measurements, while cumulative input-token use ranged from a 5.7% decrease to a 4.0% increase relative to the baseline.
These are results on the paper’s particular benchmark and setup, not a general measure of an agent’s ability to understand any long document. Performance varied by agent and task; for example, InfMem’s score decreased on one task, frequent-value identification. The results therefore support a benefit on average, not a claim that every component helps every system in every situation.
What remains uncertain
The evaluation depends on data with explicit structure that parsers can expose, and on tasks with defined reference answers. It does not test every kind of document, poorly structured text, or open-ended reasoning. Nor does it show that TreeAgent will improve all memory systems or deployment settings. The extra model calls also matter in practice, even if the reported token use stayed relatively close to the baseline.
The source is an arXiv preprint, a version of research posted for public access that should not be treated as proof of peer-reviewed consensus. The paper describes its datasets, controls and evaluation, but independent replication and broader testing would help establish how robust the gains are beyond this study. For now, TreeAgent offers a concrete design lesson: when information already has a hierarchy, an agent’s memory may work better if it is allowed to use that hierarchy rather than flattening everything into equal-sized pieces.
- AI agents
- language models
- memory systems
- structured data
- long-context processing
- retrieval
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
EvoMemState gives AI memories context—and rules for using it
Supporting evidence: Both papers report benefits from representing relationships that are lost when information is treated as isolated pieces: TreeAgent reports an average score gain over flat segmentation on structured-data retrieval and aggregation tasks, while Xiang et al. report improved retrieval completeness and memory-grounded response accuracy with relational states on personal-memory benchmarks. This is compatible evidence that explicit relationships can help in their respective evaluated settings, not a head-to-head comparison or evidence that the methods generalize across those settings.
Model review: · openai-codex/gpt-6-luna
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2611.13946v1 — Original paper
Excerpt reference:
static/papers/2611.13946v1.md:834-906
Basis: Paper text
Source SHA-256:d7ac038b1daea8013d5c2b39868c9bddbc842ac3c91f5ea7a514d440a20854e92611.03743v1 — Original paper
Excerpt reference:
static/papers/2611.03743v1.md:13-74
Basis: Paper text
Source SHA-256:c3845322f338c3bc89e36a787ac4142cbb451e6c2043de6f547ea2ff83594692
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Can an AI agent remember a correction at the right moment?
Source published
Shared keywords: ai agents, language models
Can AI agents work with less context? A study tests compact memory and selective reading
Source published
Shared keywords: ai agents, language models
MemSidecar puts AI memory retrieval on a separate track
Source published
Shared keywords: ai agents
AI Memory Needs More Than a Relevance Check, Preprint Argues
Source published
Shared keywords: language models
Could sleep-inspired maintenance help AI agents manage their memories?
Source published
Shared keywords: ai agents