TRANSMISSION // 2611.13831v1
Teaching an evolutionary solver to see objects, not just pixels
Source published
FairlySymbolic searches for ARC puzzle solutions by evolving three things together: how a grid is parsed, what symbolic program transforms it, and how the result is drawn. Its authors report meaningful results on ARC-AGI-1 but very limited success on ARC-AGI-2, highlighting both the promise and current limits of this approach.
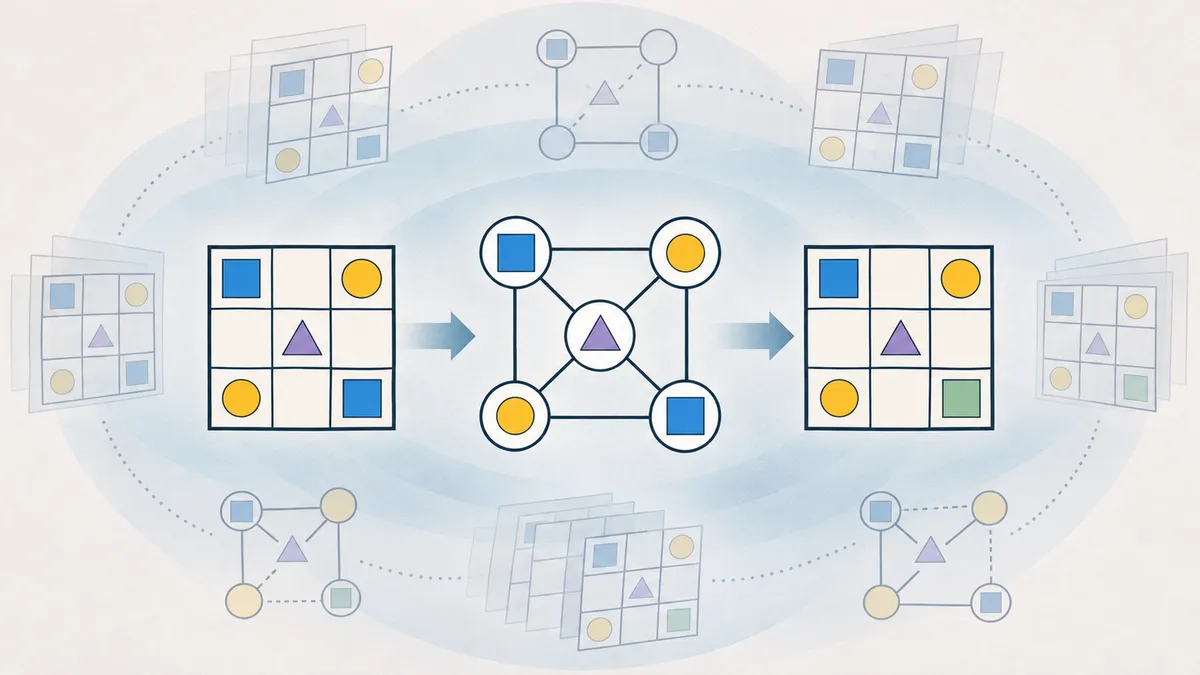
A colored grid can be more than a collection of pixels: it may contain objects, boundaries, patterns, or a visual legend. A solver must decide which of these structures matter before it can infer a rule. In a preprint, Luca Favole and colleagues introduce FairlySymbolic, an evolutionary system that searches for a useful way to represent each ARC puzzle alongside the program that solves it.
The Abstraction and Reasoning Corpus (ARC) presents a solver with a few examples of input grids and their outputs. The challenge is to infer the transformation behind those examples, then apply it to a new grid. A rule as simple as “move the red shape” depends on recognizing what counts as a shape in the first place. But another puzzle may require treating individual cells separately. Choosing the wrong representation can make a sensible rule difficult to express—or hide the relevant structure altogether.
FairlySymbolic tackles that choice by evolving a parser, a program, and an output projector together. The parser turns a grid into a graph of symbolic entities and relationships. It might identify objects, cavities, clusters, or spatial relations. The program selects and transforms those entities using operations such as moving, recoloring, copying, or filling. The projector converts the transformed scene back into a grid. In evolutionary search, candidate solutions are modified and selected according to how well they reproduce the examples.
This joint search matters because the representation and the rule are interdependent. A shape represented as one object can be moved in a single operation; represented as separate cells, it may require many. The system therefore does not commit to one fixed interpretation of every grid. It searches among parser and projector settings as it searches for a program. Its available symbolic concepts were inspired by “core knowledge” ideas in cognitive psychology, including objects, number, and space. That inspiration informs the system’s design; it does not mean the solver has human-like understanding.
The authors also try to give the search useful feedback when a candidate is not yet correct. Exact matches on the demonstration outputs ultimately determine whether a candidate fits. But imperfect candidates are ranked using both cell-level differences and object-level features, including object counts, matching, color, shape, and position. The idea is that a prediction with the right objects in nearly the right places may be more promising than one that merely happens to match a similar number of pixels. The paper’s ablation experiments support the value of this richer feedback: the tested versions using coarser fitness, random candidate generation, or no local refinement performed worse on ARC-AGI-1 training tasks than the full system.
The results vary sharply by benchmark. On ARC-AGI-1’s public evaluation set, the paper reports that FairlySymbolic solved 110 of 400 tasks with up to two predictions per task and a search budget of 3,840 seconds per task. On ARC-AGI-2’s public evaluation set, it solved 3 of 120 tasks under the reported setup. The authors also report 20 solved tasks among 233 ARC-AGI-2 training tasks that were new rather than inherited from ARC-AGI-1. These figures show that the method can solve some puzzles, but they do not support a claim that its approach is broadly sufficient for the harder benchmark.
One caution is that matching the examples is not the same as discovering the intended rule. Several different programs may fit a small set of demonstrations yet behave differently on a new case. The paper illustrates this with a program that matches the examples but makes unintended connections when the test grid contains an arrangement absent from training. The authors also describe a task involving a color legend that their parser and language do not directly represent. In such cases, more search alone may not help: the system may need better representations or operations.
The authors report near-complete performance on ConceptARC after expanding the solver’s capabilities in response to that benchmark. They explicitly note that this result is unsurprising because those extensions were designed to address ConceptARC’s identified gaps. It is therefore evidence of a useful development process, not an independent demonstration that the system has mastered a broad range of unseen reasoning problems.
This work is a preprint, not a settled verdict on evolutionary methods or ARC-solving systems. Comparisons across ARC results also require care: benchmarks, numbers of attempts, time budgets, and evaluation conditions differ. FairlySymbolic’s contribution is a clear research direction—let the solver search for a useful symbolic view of a task as well as a rule—but its reported ARC-AGI-2 performance and examples of ambiguity make the remaining limitations plain. The paper is available on arXiv.
- ARC
- evolutionary computation
- program synthesis
- symbolic AI
- abstraction and reasoning
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
F3-AGI tests a frugal route to abstract reasoning—with a calibration caveat
Shared method: Both papers use program synthesis to infer grid transformations from examples: FairlySymbolic jointly evolves a parser, symbolic program, and projector, while F3-AGI describes adaptive complexity-guided synthesis and residual patching. This is a shared broad method, not evidence of equivalent search procedures or comparable performance; their reported evaluations and task splits differ.
Model review: · openai-codex/gpt-6-luna
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2611.13831v1 — Original paper
Excerpt reference:
static/papers/2611.13831v1.md:101-142
Basis: Paper text
Source SHA-256:8f17db3607fa785205b37bbf885d566c794d5e6d9f48c45e1e53d92271f117c92611.13325v1 — Original paper
Excerpt reference:
static/papers/2611.13325v1.md:18-52
Basis: Paper text
Source SHA-256:d1f3d026e223e2ac00f942fe8b558772247b3104b734caa4502e715bd916e0a4
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
F3-AGI tests a frugal route to abstract reasoning—with a calibration caveat
Source published
Shared keywords: program synthesis
ALBI tests language-model rules with a logic engine
Source published
Shared keywords: program synthesis
Predicting Which Offspring Last Did Not Improve an Evolutionary Search
Source published
Shared keywords: evolutionary computation
Can the geometry of a program’s execution reveal the program itself?
Source published
Shared keywords: program synthesis
Building Theorems from Carefully Designed Contradictions
Source published
Shared keywords: symbolic ai