TRANSMISSION // 2611.13704v1
SeqFold compresses user histories into timestamped codes
Source published
A frozen sequence model can produce an enormous timeline of user-behavior states, even when downstream systems need only a summary from before each prediction. SeqFold turns those states into compact, timestamp-addressable codes. In proprietary-data experiments, the authors report a 3,400-fold reduction in storage per snapshot; the full representation scored 2.11% higher on query-level precision-recall AUC for the upstream action-prediction task. The results are promising, but come from one preprint’s specific datasets and tasks.
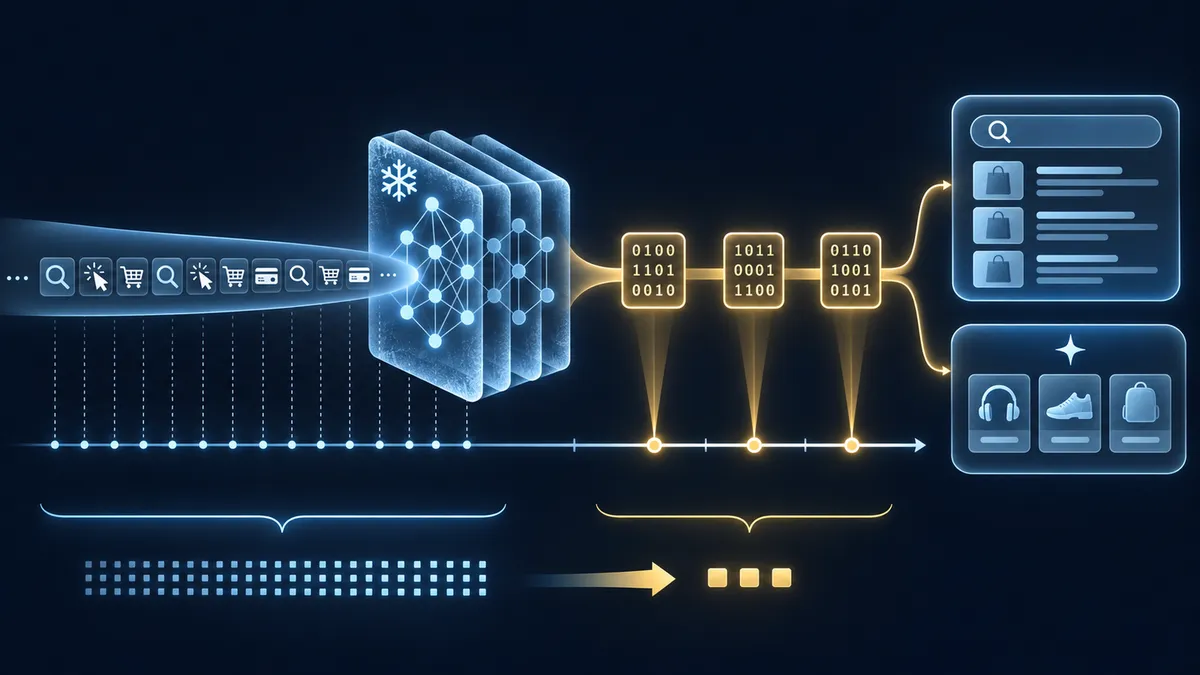
For a recommendation or search system, a person’s past actions can help predict what they may do next. But a model that encodes a long history can generate far more internal data than a downstream system needs. SeqFold asks whether those detailed states can be compressed into small summaries that remain aligned to the moment a prediction is made.
A sequence model may track a user’s searches, clicks, and purchases across thousands of actions. Its internal representations can be useful to other systems, but passing along every representation from every layer is costly. Just as importantly, a prediction about an event at a particular time should use only information available before that event—not later actions.
In “SeqFold: Timestamp-Addressable Compressed States for User Action Sequence Backbones,” researchers propose an interface for this problem. Rather than redesigning the original sequence model, SeqFold takes the states produced by a frozen model and exports a compact summary for requested timestamps. The paper frames this as a way to reuse a shared user-history model in downstream tasks such as search and query autocomplete, both in training-data backfill and online serving.
From a long timeline to a compact snapshot
SeqFold combines states from multiple layers into a fixed set of learned channels. Each channel can give different weight to actions and discount older actions at a learned rate. The resulting continuous summaries are converted into binary codes using Lookup-Free Quantization, a method for representing numerical vectors with compact discrete values. A downstream task can decode the shared codes into its own embedding space.
The timestamp requirement shapes the implementation. SeqFold updates its running summary after every action, but stores a code only when a downstream record requests one. This streaming approach avoids creating and retaining a large intermediate state for every possible point in the history. At a requested time, the exported state reflects actions strictly before that time. During some compressor-training runs, nearby targets instead reuse the latest regularly exported checkpoint, which the authors describe as introducing a bounded visibility delay.
What the experiments report
The evaluation uses proprietary datasets. The main setup has a four-layer backbone with a 256-dimensional hidden space, and user histories averaging about 1,700 actions, with a maximum of 2,000. For each state snapshot, the default SeqFold configuration uses 2,048 bytes of serialized codes. The full, uncompressed representation averages 6,963,200 bytes per snapshot. That is a reported 3,400-fold storage reduction.
The compressed representation did not match the full model’s measured predictive metric: the full representation scored 2.11% higher on query-level precision-recall AUC for the upstream action-prediction task. This comparison is a trade-off, not a finding that compression leaves performance unchanged.
The authors also compare variants that pool, sample, or truncate action histories, and a continuous fusion model without quantization. In their reported setup, these alternatives generally offer a less favorable balance of storage and predictive performance. The size of the trade-off varies: for example, the paper reports that removing quantization improves the metric by 0.72% relative to SeqFold, while increasing storage from 2,048 to 262,144 bytes.
A separate systems benchmark measures the state-generation operation, not the entire recommendation or search pipeline. With 10,000 actions, batch size 10, and all prefixes exported, the fused streaming implementation takes 51.77 milliseconds, compared with 1,014.48 milliseconds for the authors’ tensorized baseline. When only a sparse subset of timestamps is requested, the reported streaming latency and peak memory fall further. Those measurements support the implementation’s efficiency in the tested setup; they do not establish the same speedup for every production workload.
For downstream transfer, the paper reports positive relative changes for search and query autocomplete when SeqFold codes are added to task-specific baselines, across the tested decoder dimensions. The gains are modest and dataset-specific; the manuscript withholds absolute metric values because the underlying data are confidential.
What remains uncertain
The evidence is limited to proprietary datasets and the paper’s chosen models, tasks, and comparison protocol. Without public data or absolute performance values, independent readers have limited ability to reproduce the central results or judge how they would carry over to other products, populations, and serving conditions. The authors say that the codes may still encode sensitive behavioral information and caution that downstream systems can inherit biases from their underlying data.
The work is an arXiv preprint, not a guarantee of peer review or broad external validation. Its headline storage result concerns one timestamped snapshot; total storage for backfill still depends on how many timestamps are requested. SeqFold also does not make the original backbone faster, nor does compression itself address privacy, fairness, or governance. The contribution is narrower: a proposed way to package long-history model states for reuse, with a substantial storage saving and a measurable performance cost in the reported experiments.
- SeqFold
- recommender systems
- user behavior modeling
- sequence models
- representation compression
- quantization
- arXiv preprint
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
What a Moviegoer's Own Guess Adds to a Recommendation
Source published
Shared keywords: recommender systems
Why more platforms may not mean better AI recommendations
Source published
Shared keywords: recommender systems
Turning recommendation “what-ifs” into explanations people can read
Source published
Shared keywords: recommender systems
Taobao researchers give overlooked video recommendations another chance
Source published
Shared keywords: recommender systems
Combining reviews, photos and descriptions helps recommend less-popular products
Source published
Shared keywords: recommender systems