TRANSMISSION // 2611.13442v1
ForeSpark schedules both AI guesses and checks
Source published
ForeSpark is a proposed system for deciding how many tokens to draft and verify for each language-model request. Its abstract reports throughput gains in tested comparisons, but the available evidence is limited to the abstract, leaving the experimental details and wider applicability unclear.
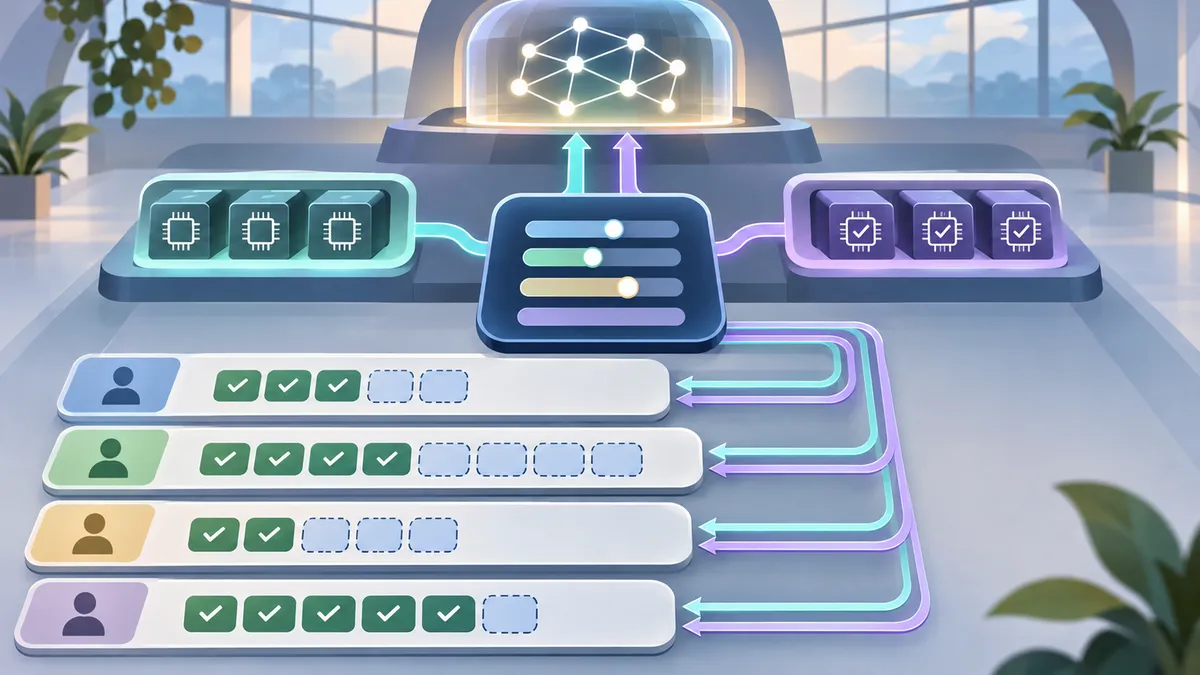
Large language models usually generate text one token at a time, which can make serving many requests costly. Speculative decoding tries to speed generation by drafting several possible tokens for the main model to check. ForeSpark addresses a scheduling question: how much should the system draft for each request, and how much should it verify?
The scheduling problem
A language model generates text sequentially: each new token depends on what came before. Speculative decoding tries to reduce this bottleneck by having a drafter propose several tokens in parallel. The larger target model then checks those proposals. If a guess fails, later guesses in that block may be unusable, although an appropriate verification procedure can preserve the target model’s output distribution.
The trade-off is not simply “draft more” or “verify more.” Drafting takes time, and verification uses resources too. At high serving loads, the ForeSpark authors report that drafting can account for up to 40% of a step’s time, with most of that drafting work going to tokens that are never verified. The abstract also describes a constraint specific to parallel drafters: they choose their block length before making a single pass, so they cannot readily adjust that length based on information from within the pass.
The researchers’ central question is whether a serving system can decide, request by request, both how many tokens to draft and how many to check, while keeping those decisions fast enough to make at every step.
A joint budget for guesses and checks
The proposed design is called work-conserving speculation, or WCS. ForeSpark is the team’s prototype implementation of that approach in vLLM, a system for serving language models.
The abstract describes three parts. First, a context-aware estimator uses features from the target model’s context to predict acceptance for different possible draft lengths. Second, a lightweight scheduler chooses draft and verification lengths jointly across the batch—the requests being processed together—using a global sort. Third, after drafting, a budget-distribution step directs verification toward the most promising tokens.
In plain terms, ForeSpark aims to avoid assigning the same drafting and checking effort to every request. It estimates which candidates are worth pursuing, then apportions work across requests. The abstract says the joint decision is designed to be computationally cheap at each step. It does not provide enough detail to assess the estimator’s accuracy, the scheduler’s precise trade-offs, or its overhead.
What the abstract reports
The authors report that ForeSpark improves throughput by up to 1.77 times compared with DSpark, which they describe as a state-of-the-art system, and by up to 2.49 times compared with autoregressive decoding. These comparisons are reported at a matched per-request generation rate. The abstract also says ForeSpark can sustain up to 1.51 times DSpark’s request rate while meeting latency service-level objectives—limits on how long users should wait.
The authors state that the method does not change the output distribution. That matters because a speed-up would be less useful if it came from changing the target model’s output distribution. This is a claim about the decoding method, not a guarantee that every generated answer is accurate or safe.
These are maximum reported gains, not a promise that every workload will see the same improvements. The abstract does not specify the full range of models, hardware, prompts, or load conditions behind the figures, or how results vary across those settings. Throughput and latency can depend on workload and system configuration.
What remains uncertain
This account is based on the paper’s abstract alone. The available evidence does not include enough information to describe its benchmarks, implementation costs, variation in results, or failure cases. Those details would be needed to judge how broadly the reported gains apply and whether the approach is practical beyond the tested setup.
The source is an arXiv preprint; the supplied material does not establish peer review or independent replication. The results should therefore be read as the authors’ reported findings, pending examination of the full paper and further evaluation. The core idea is to control both the amount drafted and the amount verified. How much that helps in real deployments depends on details the abstract cannot answer.
- speculative decoding
- large language models
- AI inference
- LLM serving
- ForeSpark
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
Hybrid Spark combines prediction and copying for AI code editing
Shared method: Both papers use adaptive verification to allocate a batch-wide verification budget toward promising draft tokens: ForeSpark jointly schedules per-request draft and verification lengths, while Hybrid Spark compares model-based and model-free draft chains under a shared token price. The overlap is budget allocation, not the same scheduler; the reported evaluations use different systems and workloads.
Model review: · openai-codex/gpt-6-luna
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2611.13442v1 — Original paper
Excerpt reference:
static/papers/2611.13442v1.md:194-264
Basis: Paper text
Source SHA-256:8c75b74b0abff761e1b212e9e683922db639cfac7bd65f46416e98ea239a07f22611.05611v1 — Original paper
Excerpt reference:
static/papers/2611.05611v1.md:13-43
Basis: Paper text
Source SHA-256:fccf971e362688c42de62e979cba3b96c45ca32301ad697a44faa750cbd67962
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Keeping the right conversation in memory could make AI chatbots faster
Source published
Shared keywords: large language models, llm serving
Hybrid Spark combines prediction and copying for AI code editing
Source published
Shared keywords: large language models, speculative decoding
AMD’s InferaSim predicts which LLM serving setups are worth testing
Source published
Shared keywords: llm serving
AI can spot a simulator’s flaw and still choose the wrong design
Source published
Shared keywords: large language models, llm serving
CPU-ARC turns language-model solutions into reusable programs
Source published
Shared keywords: large language models