TRANSMISSION // 2611.13413v1
The timing trick that lets LLM lookup tables move to disk
Source published
Large language models can rely on lookup tables that consume substantial server memory. A new SGLang system, SlackTier, exploits the time available before different model layers need their data: deeper-layer reads can often come from NVMe, while earlier-layer reads need faster access or caching. In tests, this sharply reduced host-memory use with small decode slowdowns. The results are specific to the tested models, hardware and workloads, and come from a preprint.
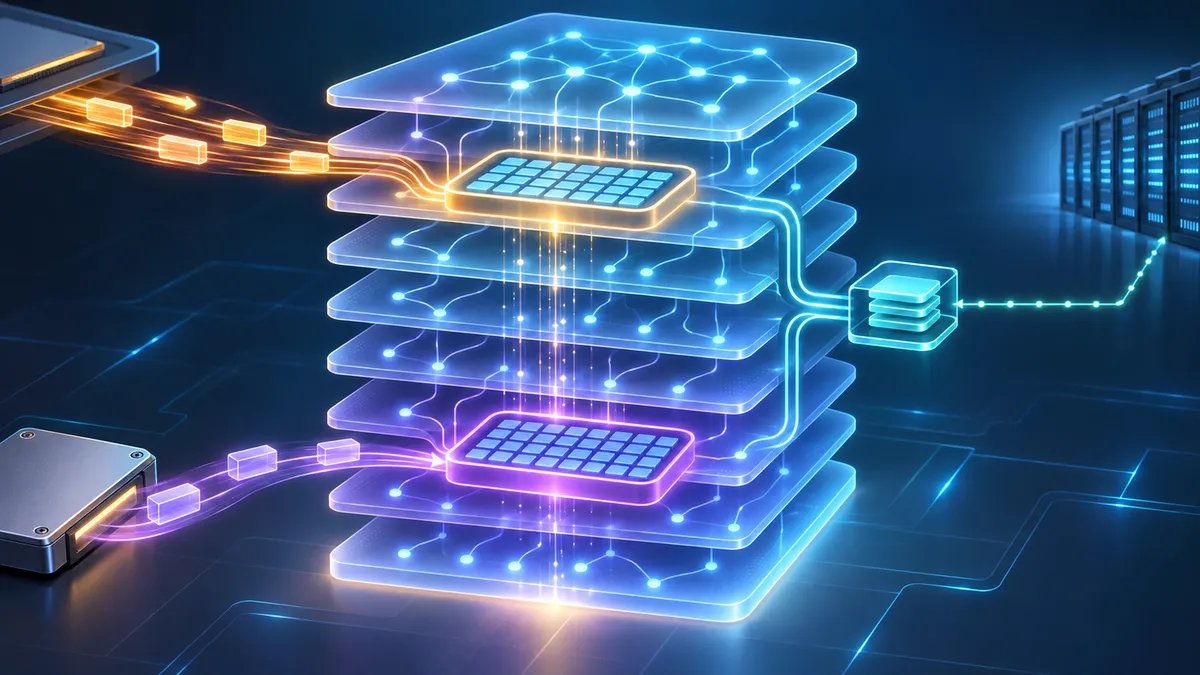
Moving a model’s data to cheaper storage sounds simple—until the model needs that data mid-calculation. This study asks whether the timing of each lookup can reveal which tables can safely leave host memory, and tests a system that schedules those reads around the model’s computation.
A memory problem with a timing solution
Some language models use large lookup tables alongside their neural-network weights. DeepSeek-V4.1’s two Engram tables contain information indexed by short sequences of input tokens. Together, the tables occupy about 203 GB. In the authors’ four-GPU serving setup, keeping them in host memory accounted for 190 GiB of a process using 223 GiB in total.
The challenge is not just where the tables fit. It is when their data must arrive. A lookup’s row indices can be calculated from the input tokens before the model’s forward pass begins. That lets a server start reading rows while earlier layers are computing. But different layers provide different amounts of time for those reads to finish.
The authors measured a striking gap in DeepSeek-V4.1: the first Engram layer has a prefetch window of roughly 0.3 milliseconds, while the later one has about 9.3 milliseconds. Think of these windows as delivery deadlines. A slow storage device may meet the later layer’s deadline but miss the earlier one, even when both tables are similarly large.
Scheduling reads, not just caching popular rows
The researchers built SlackTier, a system for the SGLang serving framework that can place lookup tables in host memory, local NVMe solid-state drives, or another machine’s memory accessed over RDMA (remote direct memory access). It starts lookups at the beginning of each decoding step, prioritizes the early layer’s reads, and divides a small GPU cache between the layers.
This design responds to two complications. First, requests within a conversation often reuse some lookup rows, making a cache useful. But rows that are popular across sessions are not necessarily the ones a particular session will need: the authors found that a dynamic least-recently-used cache captured more of the tested traffic than fixed lists of supposedly “hot” rows. Second, the two layers’ reads can compete for the same disk. A delay to the early layer can also give the later layer more time, so simply adding each layer’s delay separately can misstate the total slowdown.
To account for this, the paper presents a model that combines measured read times, each layer’s deadline and interference between reads. The authors tested the system on DeepSeek-V4.1 and a second model, Qwen3.8, using agent and chat request replays. They also checked that SlackTier returned the same lookup values as the original gather operation: their in-server checks reported no mismatches across the tested lookups, including runs with cache evictions.
What the tests found
For DeepSeek-V4.1, the later layer’s table could be read from NVMe without a cache and without measurable decode slowdown in the reported tests. The early layer was more sensitive. Splitting a small GPU row cache across both layers worked substantially better than putting it only on the later layer, because the early layer has less time to wait for missed rows.
With both tables on four NVMe drives, the authors report that mean time per output token rose by at most 1.4% on their agent and chat replays compared with unmodified SGLang. Host-memory use fell from 212 GiB in that comparison to 34 GiB. Reading both tables from another node’s memory over RDMA required no cache at higher tested session counts and had performance close to the host-memory baseline. These outcomes depend on the storage setup and the workload; they are not a promise that any disk or network link will behave the same way.
The reclaimed memory also mattered in one constrained agent-serving experiment. When the team used it for host-side key-value (KV) cache—the stored context used to continue conversations—median throughput increased by 36%, and median 90th-percentile time to first token fell from about 38 to 24 seconds. This is a result of that particular memory-budget experiment, not evidence that moving tables to disk alone makes a model faster.
What remains uncertain
The main lesson is a systems principle: choose storage according to when each layer needs its data, not only according to table size or average row popularity. But the evaluation has limits. End-to-end tests focused on two models and four H200 GPUs, with specific SGLang software, storage devices and replayed traffic. Some measurements on other hardware were probes of timing windows rather than full end-to-end evaluations. The authors also note that new models and deployments need their own measurements of lookup deadlines, read speeds, cache behavior and contention.
The paper is an arXiv preprint, not a peer-reviewed publication. Its figures describe experiments reported by the authors; independent replication would help establish how well the approach transfers to other serving systems and workloads. SlackTier targets sparse, token-indexed lookup tables whose addresses are known in advance. The authors explicitly distinguish these from dense model weights, which require much broader data transfers and cannot be assumed to benefit from the same approach.
- large language models
- LLM serving
- memory systems
- Engram
- prefetching
- NVMe
- SGLang
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
Keeping the right conversation in memory could make AI chatbots faster
Supporting evidence: The lookup-table study reports session-level row reuse and that static hot sets transfer poorly; the IAC study reports that conversation continuation and reuse delays vary by intent and turn, and uses recent reuse statistics for eviction. These findings support the bounded point that reuse patterns can depend on workload behavior. The papers cache different objects and evaluate different workloads, so their metrics are not directly comparable; the comparison is limited to their reported evaluations.
Model review: · openai-codex/gpt-6-luna
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2611.13413v1 — Original paper
Excerpt reference:
static/papers/2611.13413v1.md:81-189
Basis: Paper text
Source SHA-256:62018a7beddda850fd9f2daeef63599bdbb86b45d65b85f01aaf1285f6f3ca0f2611.09715v1 — Original paper
Excerpt reference:
static/papers/2611.09715v1.md:13-112
Basis: Paper text
Source SHA-256:af7e09ee32c00d11e7cc51e867e57f838136777b82f1a5595c33211efd7bc4f72611.09715v1 — Original paper
Excerpt reference:
static/papers/2611.09715v1.md:374-510
Basis: Paper text
Source SHA-256:af7e09ee32c00d11e7cc51e867e57f838136777b82f1a5595c33211efd7bc4f7
AdaOffload adapts CPU and GPU workloads to run large AI models
Supporting evidence: The lookup-table study reports that, on a KV-constrained agent workload, using memory freed by moving tables to host KV cache increased median throughput. AdaOffload describes a separate VRAM tradeoff in which offloading experts leaves more capacity for KV caches. Together these support the bounded point that reducing non-KV memory use can make more capacity available for KV state; the memory tiers, systems, workloads and outcomes differ, so the results do not establish comparable gains or a general performance effect.
Model review: · openai-codex/gpt-6-luna
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2611.13413v1 — Original paper
Excerpt reference:
static/papers/2611.13413v1.md:13-80
Basis: Paper text
Source SHA-256:62018a7beddda850fd9f2daeef63599bdbb86b45d65b85f01aaf1285f6f3ca0f2611.10219v1 — Original paper
Excerpt reference:
static/papers/2611.10219v1.md:378-493
Basis: Paper text
Source SHA-256:d013bf8d57838650f0d9bced2198e2d08e0136396bcd78db35c523f2d7dd9dd8
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
When 4-Bit Language Models Run Faster—and Where Evidence Is Thin
Source published
Shared keywords: large language models, llm serving
Keeping the right conversation in memory could make AI chatbots faster
Source published
Shared keywords: large language models, llm serving
ServerBench tests whether coding agents can build better LLM serving systems
Source published
Shared keywords: llm serving
AMD’s InferaSim predicts which LLM serving setups are worth testing
Source published
Shared keywords: llm serving
ForeSpark schedules both AI guesses and checks
Source published
Shared keywords: large language models, llm serving