TRANSMISSION // 2611.13361v1
Combining reviews, photos and descriptions helps recommend less-popular products
Source published
A preprint reports improved product rankings by combining shopping histories with reviews, images and descriptions. Gains were most consistent for products with few recorded interactions, but the tests excluded entirely unseen items and used sampled candidate lists.
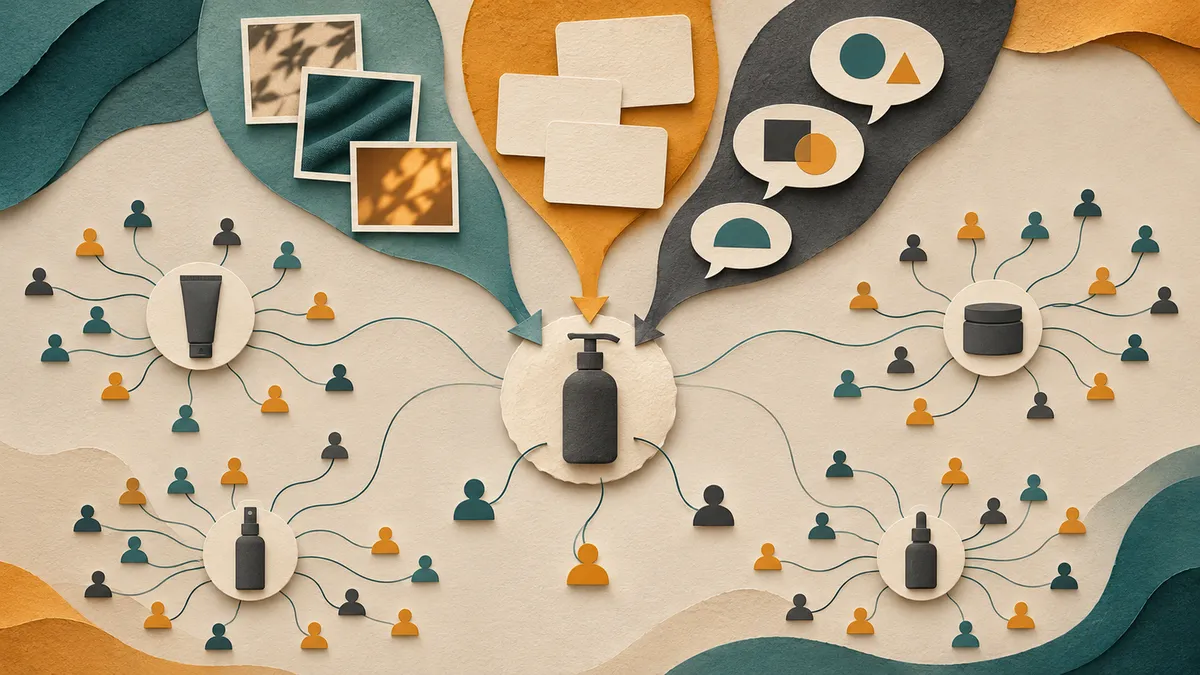
A product with few recorded shoppers gives a recommendation system little behavioral evidence to work with. Its description, photograph and existing reviews offer other clues. Researchers have developed a model that combines those sources, with promising—but bounded—results on two Amazon product categories.
Shopping recommendations often depend on patterns in past activity: people who interacted with similar products may want similar things next. That approach becomes less reliable for products with short interaction histories. A preprint by Emna Belguith, Fajrian Yunus and Talel Abdessalem tests whether combining product descriptions, photographs and customer reviews can help fill that gap.
Their system, called MPIUR, achieved the highest overall ranking scores among four evaluated models on Amazon Reviews 2023 data from the Musical Instruments and Baby categories. Its most consistent advantages appeared among products with fewer than 10 interactions. The findings concern offline prediction of recorded interactions, not a demonstrated improvement in shoppers’ satisfaction or purchases.
Turning reviews into connections
MPIUR processes reviews in two ways. It encodes each complete review into a numerical representation and uses a language model to extract structured combinations of product aspect, opinion and sentiment. These separate what a review discusses from what the reviewer says about it.
The system then builds two connected-network models, or graphs. One links users and products through their recorded interactions, with review information influencing how information passes between them. The other connects users and products to aspects and extracted review statements. An auxiliary training task asks this second structure to help identify the statement associated with a particular interaction.
Product photographs and descriptions follow another route. Pretrained image and text encoders convert them into numerical representations. Those encoders remain frozen during training, while learned projection layers adapt their outputs. An attention mechanism learns how much weight to assign the image and description for each product. These weights serve the recommendation objective; they are not independent assessments of information quality.
A central design choice concerns how strongly the system connects its content-based and interaction-based representations. Products with fewer training interactions receive a stronger alignment constraint, anchoring their representations more closely to image and description information. This popularity-dependent weighting applies to one specific training objective, not to every component of the model.
Better rankings, with uneven gains
The Musical Instruments dataset contained 17,318 users, 4,886 products and 58,469 interactions. Baby contained 25,474 users, 5,492 products and 70,205 interactions. The researchers divided each dataset into training, validation and test sets, retaining only users and products represented in training.
For each test interaction, a model ranked the observed product against 99 sampled products absent from that user’s interaction history. Recall@10 records whether the observed product reaches the first 10 places. The other measure, nDCG@10, also rewards placing it nearer the top.
MPIUR’s overall nDCG@10 reached 0.2344 for Musical Instruments and 0.2194 for Baby, ahead of the three comparison models. It also led overall Recall@10 on both datasets.
The sparse-product results need a closer reading. On Musical Instruments, MPIUR’s Recall@10 was 0.4153, almost identical to the review-based comparison model’s 0.4152. On Baby, the corresponding improvement was larger: 0.4161 versus 0.3498. For popular products, the picture was mixed, with an image-and-text baseline outperforming MPIUR on three of the four reported measures.
Component-removal experiments on Musical Instruments support the value of combining the inputs. Removing review features, together with the review-related graph and training objective, reduced sparse-product nDCG@10 from 0.2347 to 0.1869. Removing images and descriptions, along with their associated machinery, reduced it to 0.2176. These are changes to component packages, rather than clean measurements of each information source in isolation.
What the experiment leaves open
The evaluation does not establish performance for completely new products: every retained product already had a training interaction. Ranking against 99 sampled alternatives also differs from searching an entire catalog.
Another limitation affects what the model learns to predict. Only interactions accompanied by written reviews were retained, potentially favoring review-writing users. Every observed interaction counted as a positive training example regardless of rating, so a one-star review and a five-star review both supplied positive ranking targets.
Replacing the standard image encoder with language-model-generated image descriptions produced mixed results, improving one category with one model but not the other. More elaborate processing was therefore not uniformly better. The preprint supports combining complementary evidence for sparsely observed products, while leaving full-catalog performance and real shopping outcomes unestablished.
- recommender systems
- multimodal learning
- user reviews
- graph neural networks
- e-commerce
- sparse interaction histories
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
When more data hurts: a benchmark tests how AI combines images, text and changing networks
Shared method: MPIUR and TST-MF both use attention-based multimodal fusion conditioned on individual graph entities: MPIUR describes per-item attention over images and textual descriptions, while TST-MF describes target-guided cross-attention using spatial and historical context. This is a methodological connection, not a performance comparison: MPIUR addresses product ranking, whereas the MM-DyGraph preprint evaluates dynamic-graph link prediction, edge classification and node retrieval; the supplied excerpts do not establish equivalent attention mechanisms or transferable gains.
Model review: · openai-codex/gpt-6.1-sol
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2611.13361v1 — Original paper
Excerpt reference:
static/papers/2611.13361v1.md:124-185
Basis: Paper text
Source SHA-256:73f7305e481fc5fc926a68f3ca559c67bc078e98cacdefb28ac1cad1fc42468c2611.09240v1 — Original paper
Excerpt reference:
static/papers/2611.09240v1.md:67-112
Basis: Paper text
Source SHA-256:3c47e8a1a1496d1663a66649c60b0dad5d6226bb9d70c0abd615394d3b9b83572611.09240v1 — Original paper
Excerpt reference:
static/papers/2611.09240v1.md:733-781
Basis: Paper text
Source SHA-256:3c47e8a1a1496d1663a66649c60b0dad5d6226bb9d70c0abd615394d3b9b8357
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
When more data hurts: a benchmark tests how AI combines images, text and changing networks
Source published
Shared keywords: graph neural networks
Can language help a video detector spot unusual events?
Source published
Shared keywords: multimodal learning
When words, voice and faces disagree, an emotion AI changes its approach
Source published
Shared keywords: multimodal learning
A fitted DNA ‘plug’ lets frozen language models answer gene questions
Source published
Shared keywords: multimodal learning
What a Moviegoer's Own Guess Adds to a Recommendation
Source published
Shared keywords: recommender systems