TRANSMISSION // 2611.13348v1
ProTEUS puts protein evolution in a prediction-and-test loop
Source published
ProTEUS is a proposed AI-guided workflow for choosing protein mutations, predicting their effects and using laboratory measurements to guide the next round. Its abstract reports tests on two enzymes and improved activity in selected variants, but the evidence available here is only the preprint abstract—not enough to assess the full methods, comparisons or limitations.
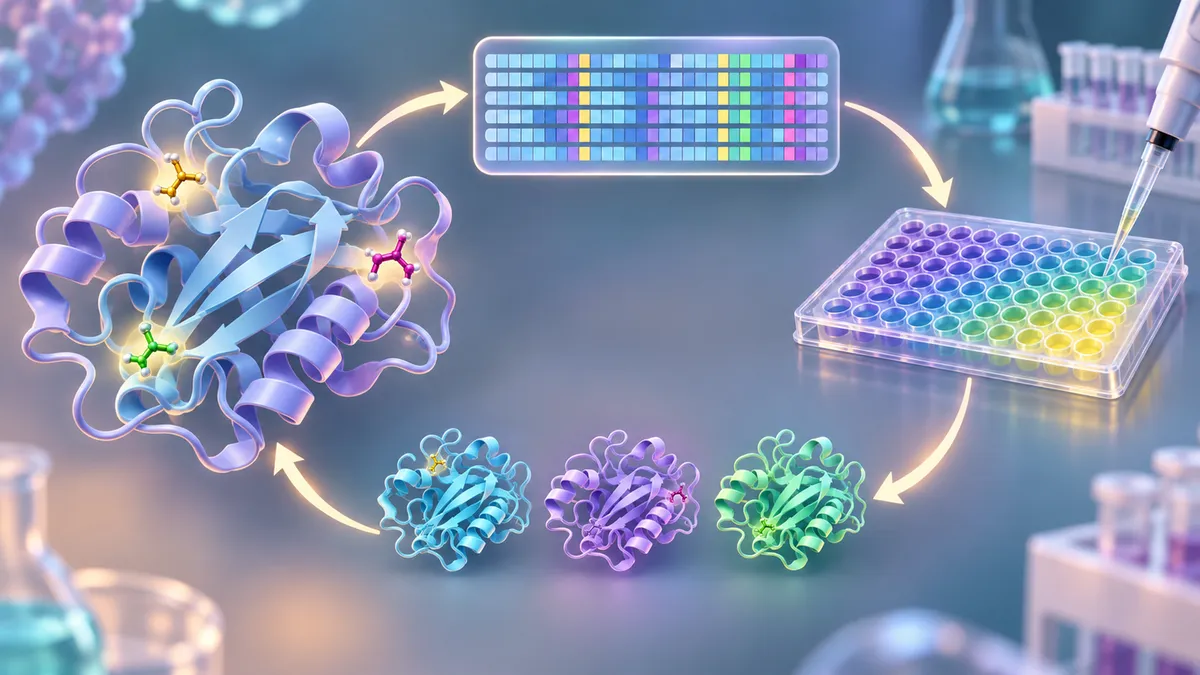
A protein’s function can hinge on small changes in its amino-acid sequence. That makes engineering a useful protein a search problem: there are many possible mutations, but only a limited number can be tested in the lab. ProTEUS aims to make that search more efficient by combining computational predictions with experimental feedback.
Turning mutations into a search strategy
Proteins are chains of amino acids that fold into structures and carry out tasks such as speeding up chemical reactions. Changing one or more amino acids can alter how well a protein performs. The challenge is that mutations do not have simple, independent effects: a change that helps in one sequence may have a different effect when combined with other changes.
The paper introduces ProTEUS as a “mutation-resolved world model” for protein evolution. In plain terms, it represents protein variants in a learned space and treats mutations as actions that can move a variant from one state to another. The system is intended to predict what those actions will do, then use experimental results to improve its guidance.
The motivation is practical. Laboratory screening can examine only a small portion of the enormous space of possible sequences. Better predictions could help researchers decide which variants are worth making and testing. But a prediction system is not a substitute for experiments: its value depends on whether its suggestions work when measured in the lab.
What the abstract says the system does
According to the abstract, ProTEUS was pretrained on deep mutational scanning assays—experiments that measure the effects of many mutations. Its MutationFormer architecture learns a joint representation using sequence, evolutionary and structural information, with attention designed to emphasize mutations.
The authors also describe a fast, physics-constrained, all-atom predictor for exploring mutant structures. They report that it runs more than ten times faster than AlphaFold 3 and say its geometric constraint enforcement guarantees physical validity. Those are claims made in the abstract; the evidence available for this article does not include the detailed evaluation needed to judge how the speed or validity claims were measured.
ProTEUS is designed to operate in a feedback loop. It predicts mutation outcomes, researchers test selected variants, and the experimental measurements are fed back into the system to refine its predictions and guide further evolution. This is the central idea behind “closed-loop” engineering: computation helps choose experiments, and experiments in turn inform computation.
Reported results—and what they establish
The abstract reports that ProTEUS outperformed established models on both zero-shot mutation prediction and supervised fine-tuning tasks. It also describes two closed-loop, multi-objective engineering campaigns, one involving aldehyde dehydrogenase and the other levansucrase. In those campaigns, the authors report obtaining variants with more than tenfold higher activity than the wild-type proteins.
These results suggest that the approach can be useful in the two enzyme-engineering campaigns described. They do not establish that the method will produce similar improvements for other proteins, functions or laboratory settings. Nor does the abstract provide the number of variants tested, the experimental conditions, the precise objectives in each campaign or the details of the comparison models. Without those details, readers cannot independently assess the scale or robustness of the reported gains.
There is also an important distinction between prediction benchmarks and successful engineering. Strong performance on mutation-prediction tasks is relevant, but it does not by itself show that a system can reliably find useful variants in every practical setting. Experimental feedback is a valuable part of the proposal precisely because predictions need to be checked against real measurements.
A promising proposal, with evidence still to inspect
The available source is an arXiv preprint abstract. A preprint is a research manuscript shared before, or outside, the formal journal peer-review process; its claims should be treated as provisional. The full paper was not available in the supplied evidence, so details about datasets, experimental design, statistical analysis, baselines and limitations could not be verified here. Search excerpts supplied alongside the abstract concern other papers and do not provide independent confirmation of ProTEUS’s results.
The most grounded takeaway is therefore narrow: the authors describe a system that links mutation-effect prediction, structural modeling and laboratory feedback, and report promising outcomes in two enzyme campaigns. Whether the approach generalizes—and how its performance compares under fully documented, reproducible conditions—requires examination of the complete study and further testing.
- protein engineering
- directed evolution
- mutation prediction
- enzyme design
- machine learning
- preprint
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
An Enzyme-Design System That Revises Its Own Research Workflow
Shared method: Both studies use experimental measurements in iterative, model-guided protein engineering: ProTEUS updates fitness predictions between variant-selection rounds, while EnzymeRSI describes a dry-to-wet loop returning quality-controlled measurements as feedback. Their algorithms, targets and campaigns differ, so this is a shared workflow feature, not evidence that one system’s performance validates the other.
Model review: · openai-codex/gpt-6-luna
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2611.13348v1 — Original paper
Excerpt reference:
static/papers/2611.13348v1.md:380-427
Basis: Paper text
Source SHA-256:51c86a0d15d0b94ca587d12d26be15b3043a202806f19ee00cfd49c3cc0134772611.06321v1 — Original paper
Excerpt reference:
static/papers/2611.06321v1.md:183-256
Basis: Paper text
Source SHA-256:4afc79c31126eb3dcc87c35cb12fcfc134b5f28d000580def44298f41adc34f1
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
An Enzyme-Design System That Revises Its Own Research Workflow
Source published
Shared keywords: directed evolution
Protein swaps reveal why a photosynthetic bacterium needs TrxA
Shared keywords: protein engineering
One Energy Lens for Many Kinds of Machine Learning
Source published
Shared keywords: machine learning
Machine learning connects atomic physics to simulations of stellar winds
Source published
Shared keywords: machine learning
PHISHREV+ uses explicit rules to reconsider phishing alerts
Source published
Shared keywords: machine learning