TRANSMISSION // 2611.13236v1
An AI control layer cuts repetition, but rejects its own weight edits
Source published
The Neural Control Plane tests temporary changes to a language model’s weights before admitting them as reusable rules. In a small experiment, one edit substantially reduced repetition, but none corrected an answer. The verifier rejected all three candidates, leaving the model’s active policy unchanged.
An AI answer can become less repetitive without becoming more accurate. A new preprint by Ekrem Aksoy makes that distinction central to an experimental control system: proposed model changes must pass explicit checks, not merely improve a convenient measurement.
The Neural Control Plane, or NCP, is a system for proposing, testing and managing temporary interventions in a language model’s weights—the numerical parameters that shape its calculations. Aksoy’s preprint, submitted to arXiv on November 9, 2026, describes an executable framework rather than a demonstrated breakthrough in self-improving AI. Its small model experiment produced three candidates, admitted none and preserved the original behavior for final evaluation.
Separate the model from the rules
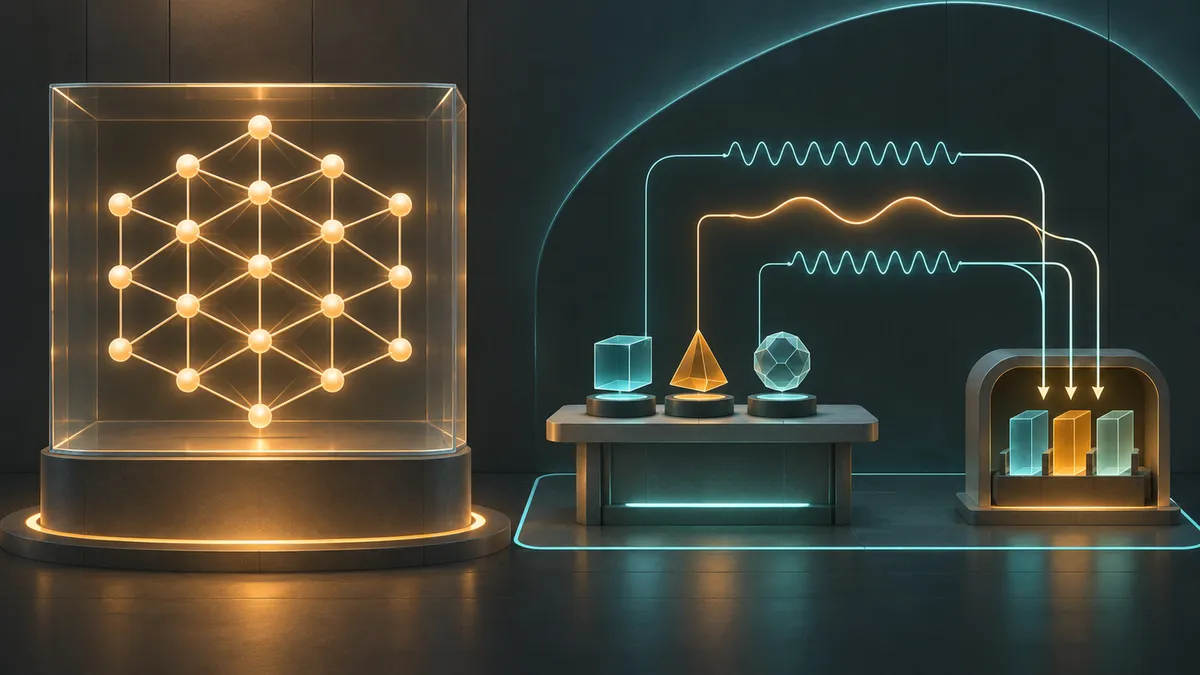
NCP borrows a design idea from software-defined networking: separate the machinery doing the work from the controller deciding how that machinery should operate. Here, the language model generates responses, while a separate controller maintains a table of intervention rules. Each rule specifies an internal activation pattern to look for, an action to apply, a priority and conditions governing its lifetime.
The parameter changes are temporary. A companion execution system called W-ISA applies an intervention for a request and restores the request-entry weights afterward. What persists is the rule definition and its evaluation record, not a permanently modified model. This distinction matters: NCP is optimizing a policy for selecting edits, rather than continually retraining the underlying network.
Rules also carry evidence tied to their exact definition and the current version of the active table. If that policy changes, old evaluation evidence cannot simply authorize a later promotion. Matching rules are considered in priority order, so the verifier must assess how a candidate behaves within the policy that would actually use it.
How the candidates were built
The recorded experiment used SmolLM-135M-Instruct, a language model with approximately 135 million parameters, and nine handwritten questions divided into three development, three validation and three final-test examples. Generation used greedy decoding with a 128-token budget.
All three development answers failed exact-answer scoring. The system therefore averaged captured internal activations from those failures to obtain a candidate direction for intervention. That direction was a development-derived signal, not an established cause of incorrect reasoning.
A deterministic Python procedure then generated three candidates targeting the tenth transformer block. One removed the profiled direction from an MLP weight transformation. Another zeroed the output contribution of one attention head. The third combined those actions. This was template-based proposal generation, not an AI independently inventing new learning algorithms. Each candidate’s activation trigger matched all three validation prompts.
Less repetition was not enough
The verifier compared the existing policy with the proposed policy on the validation questions. Under the configured rules, admission required at least one previously incorrect answer to become correct, no previously correct answer to become incorrect, actual selection of the candidate and no increase in repetition.
A separate check forced each intervention to run across a bounded WikiText-2 language-modeling slice, regardless of its trigger. This measured changes in perplexity, a score reflecting how well the model predicts the observed text; lower values are better. The slice contained 4,095 prediction targets, and the gate allowed a perplexity increase of at most 0.5%.
The projection candidate reduced the validation token-repetition fraction from 0.4133 to 0.2191, roughly a 47% relative reduction. Its forced-action perplexity decreased by about 0.0574%. Head scaling also reduced repetition and stayed within the perplexity budget. Combining the two interventions increased repetition, showing that their individual effects did not translate into a better combined result.
None of the candidates made a previously incorrect validation answer correct. All three were archived rather than activated. Parameter-digest checks recorded restoration of the original weights after every trial. With the active table still empty, final-test execution matched the baseline: both scored zero correct answers out of three.
A reproducible decision, not demonstrated self-improvement
Fresh-process repetition reproduced the reported candidate measurements, and loading the saved table preserved the decisions and final outputs. A subsequent cycle recognized the same candidate identifiers rather than treating them as new proposals. These results support the implementation’s repeatability and persistence, not general effectiveness across models or tasks.
The evidence remains narrow: one small model, three validation questions and short corpus slices. Reduced repeated token sequences cannot establish better reasoning, and a small perplexity change cannot establish broad reliability. The paper also treats rules and verification evidence as trusted local data, not as an adversarial security boundary.
NCP’s concrete result is therefore a controlled rejection workflow. It separates proposing a change from earning permission to use it—and, in this experiment, refuses to confuse a less repetitive answer with a more correct one.
- Neural Control Plane
- language models
- weight-space interventions
- inference-time adaptation
- verification
- recursive self-improvement
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
W-ISA gives temporary language-model weight edits an undo mechanism
Shared method: NCP explicitly uses W-ISA's request-scoped weight-intervention runtime and parameter restoration, while W-ISA describes the same execution contract and identifies NCP as its companion policy-selection controller. This is direct reuse of an execution method, not independent corroboration of improvement: NCP adds candidate synthesis and admission, and the manuscripts report separate experiments.
Model review: · openai-codex/gpt-6.1-sol
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2611.13236v1 — Original paper
Excerpt reference:
static/papers/2611.13236v1.md:99-161
Basis: Paper text
Source SHA-256:16c9c75c27b5d354f4180db24a8e69b3ed96fe135ff1c6c2c8183d8a84966d362611.13232v1 — Original paper
Excerpt reference:
static/papers/2611.13232v1.md:40-80
Basis: Paper text
Source SHA-256:b10100a0e23ad496d6f55f657db519163e0d4f3a602d383ee0b08dcc8dae5a622611.13232v1 — Original paper
Excerpt reference:
static/papers/2611.13232v1.md:624-736
Basis: Paper text
Source SHA-256:b10100a0e23ad496d6f55f657db519163e0d4f3a602d383ee0b08dcc8dae5a62
Language models write small neural policies—and model checking tests their promises
Shared method: NCP and Gross both evaluate proposed neural-weight changes against explicit requirements before selecting a policy. NCP uses deterministic intervention templates and empirical task and corpus checks; Gross uses LLM-written and repaired small policy networks with Storm model checking of PCTL properties in modeled environments. The shared method is verifier-guided weight-policy selection, not a shared verification guarantee: NCP's local language-model checks differ from Gross's probability computation for memoryless deterministic policies in PRISM MDPs.
Model review: · openai-codex/gpt-6.1-sol
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2611.13236v1 — Original paper
Excerpt reference:
static/papers/2611.13236v1.md:13-44
Basis: Paper text
Source SHA-256:16c9c75c27b5d354f4180db24a8e69b3ed96fe135ff1c6c2c8183d8a84966d362611.13236v1 — Original paper
Excerpt reference:
static/papers/2611.13236v1.md:99-161
Basis: Paper text
Source SHA-256:16c9c75c27b5d354f4180db24a8e69b3ed96fe135ff1c6c2c8183d8a84966d362611.11604v1 — Original paper
Excerpt reference:
static/papers/2611.11604v1.md:63-116
Basis: Paper text
Source SHA-256:2fcb845c3e0f48cd7cbc96a54f197a88424959d53f39fd05c474bf02e97210b82611.11604v1 — Original paper
Excerpt reference:
static/papers/2611.11604v1.md:460-514
Basis: Paper text
Source SHA-256:2fcb845c3e0f48cd7cbc96a54f197a88424959d53f39fd05c474bf02e97210b8
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Can coding agents make language models smaller without breaking them?
Source published
Shared keywords: recursive self improvement
InfraRSI uses measured feedback to find faster AI training setups
Source published
Shared keywords: recursive self improvement
W-ISA gives temporary language-model weight edits an undo mechanism
Source published
Shared keywords: language models, weight space interventions
Can AI help improve a training run too expensive to repeat?
Source published
Shared keywords: recursive self improvement
Teaching AI agents to train other language models
Source published
Shared keywords: recursive self improvement