TRANSMISSION // 2611.13199v1
A confidence check for AI managing computer processors
Source published
Machine-learning models can help manage processor resources, but their predictions may become unreliable when workloads differ from training data. LEX estimates a separate error margin for each incoming input by comparing its learned representation with clusters of training examples. In tests on Intel Alder Lake using benchmark applications, the authors report that these tailored bounds contained about 94% of predictions and were about 17% tighter than global-error baselines. The result is promising but comes from a particular forecasting task and hardware setup, and the paper is an authors’ preprint rather than a peer-reviewed publication.
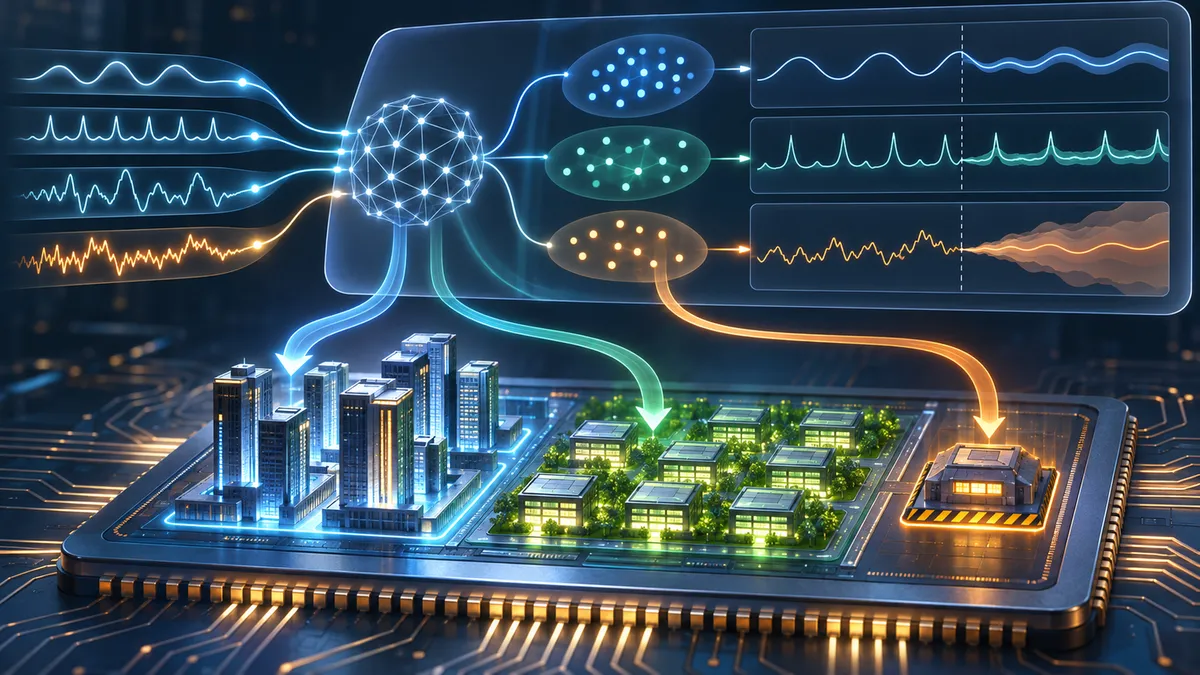
A processor-management system may use machine learning to forecast how quickly a program will run, then use that forecast to guide resource decisions. But what should the system do when a new workload looks unlike the examples the model learned from? A prediction can still appear precise even when it is wrong. The proposed method, called Lightweight Runtime EXplainability (LEX), aims to attach an input-specific estimate of prediction error—so that a system can distinguish familiar, relatively reliable situations from riskier ones.
When a processor’s AI prediction needs a warning label
Modern processors juggle workloads across different cores and operating settings. Machine-learning models can help with those decisions by forecasting a measure such as instructions per second (IPS). The catch is that a model trained on one collection of programs may encounter different programs, execution phases or hardware conditions after deployment. This is called out-of-distribution (OOD) input: data that differs from what the model saw during training. In such cases, a model may fail without signaling that its answer is suspect.
The paper asks whether a system can estimate the likely error for each incoming input, rather than applying one error margin to every prediction. A single, cautious margin may cover many cases but be unnecessarily wide for familiar inputs; a narrow margin may be misleading for unfamiliar ones. LEX is designed to provide a more tailored estimate, which a resource-management system could use to decide whether to trust a forecast or fall back to a conservative policy.
From processor readings to clusters
The authors study an LSTM model that forecasts IPS from processor performance-monitoring counters. These counters record events such as instructions, branches and cache activity. In their initial experiments, they ran benchmark applications on an Intel Alder Lake processor, collecting measurements across performance and efficiency cores and several voltage/frequency settings. They compared random train/test splits with a leave-one-application-out approach, in which an application is excluded from training and then used for testing.
For LEX, the authors use a learned representation—an embedding—that compresses the input readings into a form intended to capture patterns across multiple counters. A Gaussian Mixture Model (GMM) groups similar embeddings into clusters. The system then looks up the model’s historical prediction error for the relevant cluster and uses it as an error bound for the new input. In the described runtime design, a resource manager can use that bound to decide whether to accept the prediction or invoke a fallback.
This is a post-hoc method: it adds a confidence-estimation layer around an existing predictor rather than changing the predictor’s predictions through retraining. The paper also presents the cluster-based estimate as an explanation of sorts: it connects a confidence signal to the input’s location among learned patterns. It is not, however, a human-readable account of which processor counter caused a particular prediction.
What the tests report
The authors’ initial experiments illustrate why they consider global error thresholds inadequate. Under random splits, the model could achieve low average error while some individual windows had much larger errors. Holding out entire applications made the challenge more pronounced, with errors reaching roughly 26% MAPE in the reported example. MAPE, or mean absolute percentage error, expresses prediction error as a percentage of the actual value. The authors also report that no single processor counter reliably separated high-error windows from better-predicted ones, motivating their use of joint, learned representations.
They then evaluated LEX on a wider set of benchmark applications and hardware conditions, including tests on SPEC CPU2006 after training on PARSEC and SPLASH-2. Across the reported experiments, LEX achieved an average containment rate of about 94%: roughly that share of predictions fell within the estimated error bounds. The authors say these bounds were about 17% tighter than those from global baselines while maintaining performance comparable to the most conservative baseline. In one reported setting, average containment was 96%; results varied by test condition, and some applications remained difficult to predict. The paper describes LEX’s runtime overhead as negligible, but the supplied evidence does not provide a general cost comparison across other platforms or workloads.
A promising result with boundaries
Containment is useful only in relation to how the bounds are constructed and tested. LEX estimates cluster errors from training data, so its estimates depend on whether the learned clusters meaningfully group inputs with similar prediction behavior. A new input that is poorly represented—or a shift unlike those in the evaluation—could still defeat the estimate. The results do not establish that LEX will provide the same coverage in every deployment, nor that using it improves real-world processor performance or safety. Those outcomes depend on how a resource manager acts on the warning signal.
The evaluation focuses on one IPS-forecasting model and a specific Intel processor setup, using benchmark suites rather than a broad range of production deployments. The paper’s headline results therefore support a proof of concept, not a universal guarantee for machine-learning resource management. The preprint itself notes that it is the authors’ version; it has not thereby been established as peer reviewed. Further evaluation across models, hardware, workloads and operational settings would help show how reliably the method transfers.
For now, LEX offers a practical idea: do not treat every model prediction as equally trustworthy. Estimate how the model has performed on similar inputs, and use that estimate to guide when to rely on the forecast. The central open question is how well “similar” continues to predict “similarly reliable” once the system leaves the tested conditions.
- machine learning
- processor resource management
- out-of-distribution detection
- confidence estimation
- explainable AI
- computer architecture
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
PHISHREV+ uses explicit rules to reconsider phishing alerts
Source published
Shared keywords: explainable ai, machine learning
Can AI Models Help Check Each Other’s Explanations of Legacy Code?
Source published
Shared keywords: confidence estimation
AI claims-analysis preprint tests policy citations and privacy safeguards on synthetic data
Source published
Shared keywords: explainable ai
When a Time-Series AI Is Surprised, It Finds Its Boundaries
Source published
Shared keywords: out of distribution detection
PLUS adds a class-specific signal to help AI spot unfamiliar images
Source published
Shared keywords: out of distribution detection