TRANSMISSION // 2611.13198v1
Which data modality matters—and for which example?
Source published
A new attribution method asks how one part of one multimodal training example affects a model trained on many examples. Across two benchmarks, the authors report that their structured kernel surrogate better predicts the outcomes of different data selections than the tested alternatives, and can help choose useful examples. The results are promising, but depend on a limited set of benchmarks and an approximation that avoids retraining for every selection.
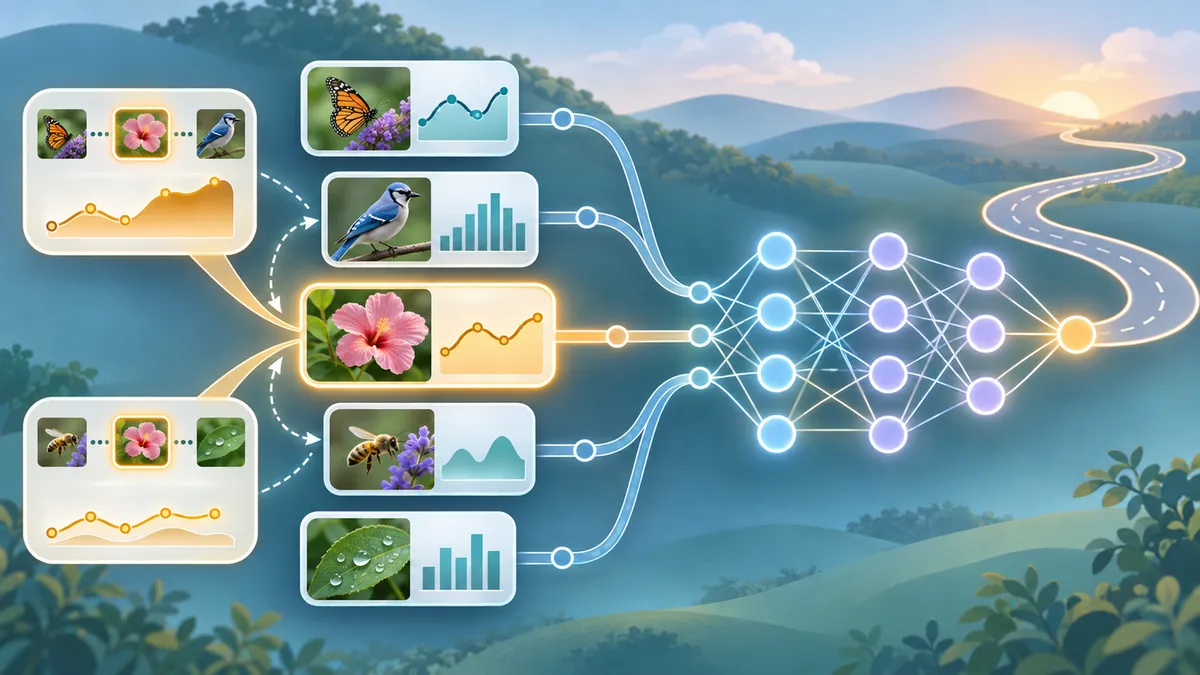
A caption may add little to an obvious image, yet provide a crucial clue for another. And a useful image may become more or less helpful depending on what else the model sees. Researchers propose a way to estimate these cross-example, cross-modality effects—information that could guide decisions about which data to keep.
Multimodal systems learn from combinations of information: for example, a road image alongside traffic measurements, or a video alongside spoken words. But the value of a modality is not necessarily fixed. A text description might repeat what an image already shows in one example and supply essential context in another. Its contribution can also depend on the other examples used to train the model.
This is the problem addressed by Ziniu Zhang and colleagues in a paper titled “Structured Kernel Surrogate Models for Multimodal Attribution.” Instead of asking only whether a training example matters, the researchers ask how retaining or removing one modality within one example changes the model’s test loss, given the rest of the selected training data. The paper describes this as cross-sample modality attribution.
Modeling choices and their consequences
The method, called SKS, represents a training-data selection as a grid: rows correspond to modalities and columns to examples, with each entry indicating whether that modality is retained for that example. It then learns a surrogate—a stand-in model—that predicts the test loss associated with different selection patterns.
SKS uses kernel ridge regression, a method for learning patterns from similarities. Its structured kernel combines two kinds of similarity: whether the same examples are present, and which modalities are present within examples that both selections share. This separation is intended to capture interactions at both levels, rather than treating every keep-or-remove decision as an unrelated switch.
To estimate an individual modality’s influence, SKS compares the surrogate’s predicted loss when that modality is included with the predicted loss when it is removed, holding other choices fixed. A positive attribution means retaining the modality is predicted to lower test loss. The score is therefore conditional: change the surrounding selection, and the estimated contribution may change too.
Evaluating many possible selections by fully retraining a model would be expensive. The authors instead use a first-order approximation around a model checkpoint trained with all samples and modalities. They report that this approximation had less than 1.2% relative mean-squared error across six states in the traffic benchmark, and under 1.1% in a separate approximation test involving vision-language models from 2 billion to 30 billion parameters. These are approximation checks, not evidence that the method’s attribution rankings are equally accurate in every setting.
What the evaluations found
The study tests SKS on two benchmarks. MMTraCE concerns traffic-accident prediction across six US states, with road-network, weather, traffic, satellite-image and accident-record information. MultiBench includes six tasks involving combinations of text, audio, vision and tabular data.
For attribution quality, the researchers compare how well each method predicts the ranking of test losses across selection patterns. They report that SKS improves this measure, called the linear data modeling score, by 50.1% on MMTraCE and 65.6% on MultiBench relative to the strongest baseline. These are relative improvements in a ranking metric, not percentage-point gains in accuracy.
The authors also test whether the scores can guide data selection. With a fixed budget retaining the top 20% of a selected modality, SKS produced average accuracy improvements of 1.52% on MMTraCE and 2.33% on MultiBench over the strongest baseline. In the traffic examples, selecting satellite images by their scores favored road segments over vegetation-dominated background tiles. The paper also reports lower estimated Hessian traces for selected-data models, a measure the authors use to characterize a flatter loss surface. That result is suggestive, not by itself proof of better real-world generalization.
What remains uncertain
These findings come from specific benchmarks, model choices and evaluation procedures. The authors say their empirical study focuses on standard multimodal fusion models and identify scaling to large vision-language models as future work. The paper’s approximation can reduce the need for repeated full retraining, but its accuracy may depend on how well a local, first-order description represents the effects of changing the training data. The experiments also use three independent runs for reported benchmark averages, so broader replication would help establish how stable the results are.
Attribution scores should not be read as universal judgments that an image, caption or measurement is inherently useful or harmful. They describe estimated effects under a particular model, dataset, selection and test-loss setup. The work offers a tool for studying those conditional effects and for exploring data selection—not a general guarantee that chosen examples will improve performance in other applications.
The source is an arXiv preprint, although the extracted paper text identifies it as appearing in the proceedings of NeurIPS 2026. This article is based on the supplied paper text and abstract; retrieval excerpts did not provide independent verification. As with any preprint-based account, reported results should be distinguished from independent confirmation.
- multimodal learning
- data attribution
- kernel methods
- data selection
- machine learning
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
GIST selects which responses and tokens to use in language-model training
Source published
Shared keywords: data selection
Combining reviews, photos and descriptions helps recommend less-popular products
Source published
Shared keywords: multimodal learning
Choosing Less-Repetitive Examples for AI Fine-Tuning
Source published
Shared keywords: data selection
Can language help a video detector spot unusual events?
Source published
Shared keywords: multimodal learning
When words, voice and faces disagree, an emotion AI changes its approach
Source published
Shared keywords: multimodal learning