TRANSMISSION // 2611.13161v1
Teaching rescue robots to share a plan, not just follow orders
Source published
A preprint combines language models, layered decision-making and shared memory to coordinate simulated aerial and ground rescue robots. Reported gains are substantial, but missing implementation details and simplified testing limit what they establish about real disaster response.
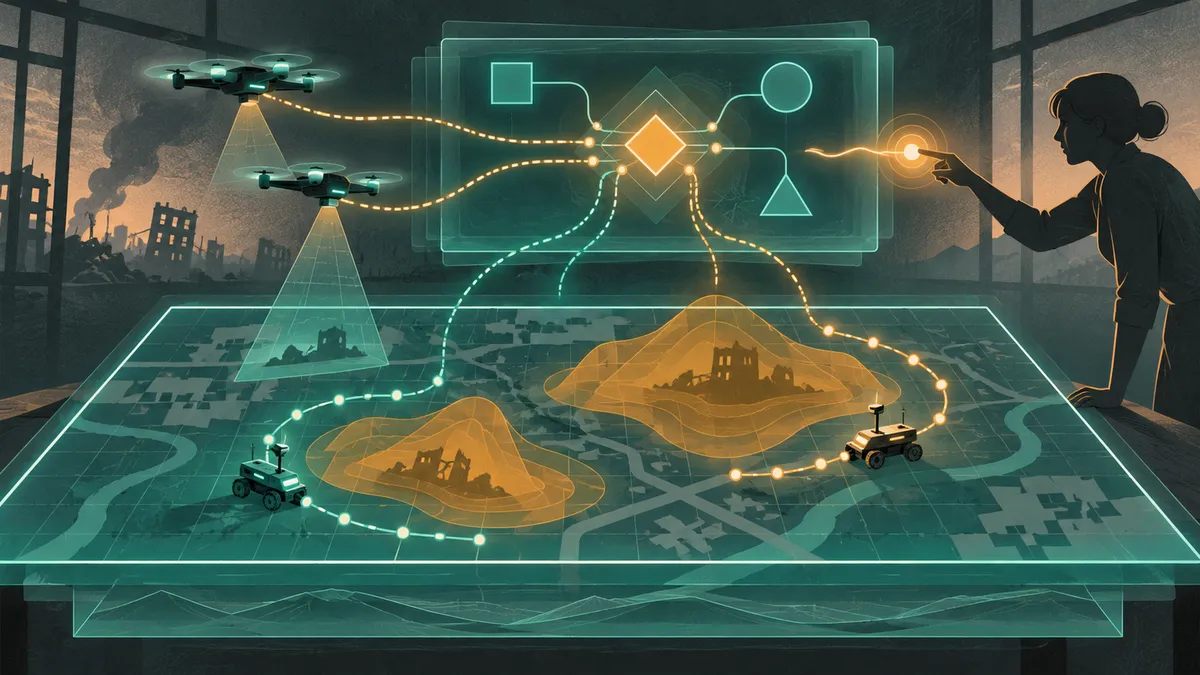
“Avoid the chemical spill; search near the collapsed factory” sounds like a straightforward instruction. For a robot team, it requires several decisions: locating those places, changing search priorities, dividing responsibilities and keeping everyone informed. A study by Sepideh Ravanbakhsh and Hamidreza Moradi proposes connecting a language model to a shared planning system so that human guidance can influence an entire team. Its results come from a two-dimensional simulation, not robots working at a disaster site.
The central idea is to separate understanding a mission from executing its individual movements. A language model first converts an operator’s instruction into structured information about goals, hazards and priorities. A high-level controller uses that information to choose activities such as reconnaissance or victim search. Lower-level controllers then select the actions needed to carry them out.
This is hierarchical reinforcement learning: instead of learning every mission as one long sequence of movements, the system divides it into smaller decisions. Reinforcement learning adjusts behavior using rewards from the simulated environment. Language supplies additional guidance about which activities matter and which areas should be avoided.
The third component is a shared workspace. Each robot contributes observations and retrieves mission updates, including hazards, priorities and information gathered by teammates. Think of it as a common incident board rather than four separate notebooks. The proposal’s “cognitive” terminology describes this information-sharing architecture; it does not establish human-like understanding.
Testing involved two simulated drones and two ground vehicles. The drones had broad but noisy overhead observations, while the ground vehicles received more detailed local information. Their environment contained blocked paths, collapsed structures, hazards and victims. Operators could introduce instructions during a mission. Each configuration was trained for 2,000 episodes across 20 independent runs.
The clearest numerical comparison concerns search coverage. The full system reportedly visited 92.5% of grid cells, compared with 78.2% for hierarchical learning without language and 63.4% for flat reinforcement learning without a hierarchy. It also revisited cells less often. Across five representative scenarios, reported victim-rescue rates were 88–92%, versus 65–70% for the hierarchical baseline and 55–62% for flat learning. These are outcomes defined within the simulation, not evidence of people physically rescued.
Language guidance also appeared to improve the match between selected subgoals and operator intent. The paper reports an increase from roughly 60% to nearly 90%. Hazard avoidance rose from about 55% to above 70%. Its headline improvements of 46% and 31% describe relative increases, not percentage-point gains.
Responsiveness needs similar qualification. Although the abstract describes adaptation as immediate, the detailed results say the system adjusted successfully in roughly 70–72% of tested interventions, typically within one or two decision steps. That is neither universal compliance nor a measured response time in seconds.
Removing components weakened reported performance. Without language grounding, normalized performance fell to around 62%; without the shared workspace, it fell to about 55%. These experiments support the importance of both components within this setup, although the paper does not clearly explain the normalized score well enough to translate those numbers into a specific operational loss.
Several reporting gaps make the broader claims difficult to assess. The methods do not identify the language model, provide its prompts or fully specify the reward function and environment. Although four baseline approaches are listed, the main numerical comparisons concentrate on flat learning and non-language hierarchical learning. The headline 2.3-fold learning-speed improvement also lacks a clearly specified convergence threshold.
Some interpretations go beyond what the setup cleanly demonstrates. The authors describe scouting and ground-rescue roles as emerging without manual assignment, yet the experimental configuration already gives aerial and ground robots different responsibilities and sensing capabilities. That makes it difficult to separate learned specialization from differences built into the team. Likewise, the reported 37% coordination improvement is variously described as reduced path overlap, reduced coordination entropy and increased coherence; those should not automatically be treated as interchangeable measurements.
The authors acknowledge the largest practical boundary: a structured 2D environment leaves out uneven three-dimensional terrain, unstable surfaces, battery constraints, actuator wear and some sensor failures. Shared memory still needs communication, and a language model can misunderstand an ambiguous instruction. The preprint therefore offers a proposed way to connect human guidance with team planning, backed by reported simulation gains. It does not yet establish that the resulting robot team would be safe or reliable in a real rescue.
- search and rescue
- multi-agent robotics
- hierarchical reinforcement learning
- large language models
- human–robot interaction
- robot coordination
- simulation
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
Training a web agent's planner and actor together improves benchmark results
Shared method: LG-HRL and JHiMA-WebRL both use hierarchical reinforcement learning to separate high-level subgoal planning from lower-level execution: LG-HRL incorporates language-derived semantic structure into strategic and operational control, while JHiMA-WebRL conditions a GUI actor on a learned task decomposition. LG-HRL reports controlled 2D rescue simulations; the JHiMA-WebRL preprint evaluates web tasks with an open-loop decomposer that cannot revise plans during execution. This is a shared architectural method, not evidence of comparable performance gains or real-world rescue effectiveness.
Model review: · openai-codex/gpt-6.1-sol
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2611.13161v1 — Original paper
Excerpt reference:
static/papers/2611.13161v1.md:942-991
Basis: Paper text
Source SHA-256:5a3c2e65199a957bd43b66ee0d63b24f67f373a8ef289e7a3a9042ffd1ed23182611.13161v1 — Original paper
Excerpt reference:
static/papers/2611.13161v1.md:1140-1183
Basis: Paper text
Source SHA-256:5a3c2e65199a957bd43b66ee0d63b24f67f373a8ef289e7a3a9042ffd1ed23182611.05263v1 — Original paper
Excerpt reference:
static/papers/2611.05263v1.md:75-115
Basis: Paper text
Source SHA-256:80e481056803d5dca96125894561cb2f9e85c2fb7aeca8cddf18962e5091213d2611.05263v1 — Original paper
Excerpt reference:
static/papers/2611.05263v1.md:866-928
Basis: Paper text
Source SHA-256:80e481056803d5dca96125894561cb2f9e85c2fb7aeca8cddf18962e5091213d
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
A feedback-based planner improves target assignments for simulated robot fleets
Source published
Shared keywords: robot coordination
Teaching AI to judge the safety of a whole maneuver
Source published
Shared keywords: hierarchical reinforcement learning
Training a web agent's planner and actor together improves benchmark results
Source published
Shared keywords: hierarchical reinforcement learning
SAFTAC trains language models to design and repair analog circuits in simulation
Source published
Shared keywords: large language models
Simpler AI personas predicted ad clicks better in one campaign
Source published
Shared keywords: large language models