TRANSMISSION // 2611.12953v1
When do more complex AI agents earn their extra cost?
Source published
A preprint comparing AI agent designs on simulated business procedures finds that added coordination consistently increases resource use, while success gains depend on the workflow and implementation. Internal reporting inconsistencies and unresolved scoring concerns limit confidence in precise comparisons.
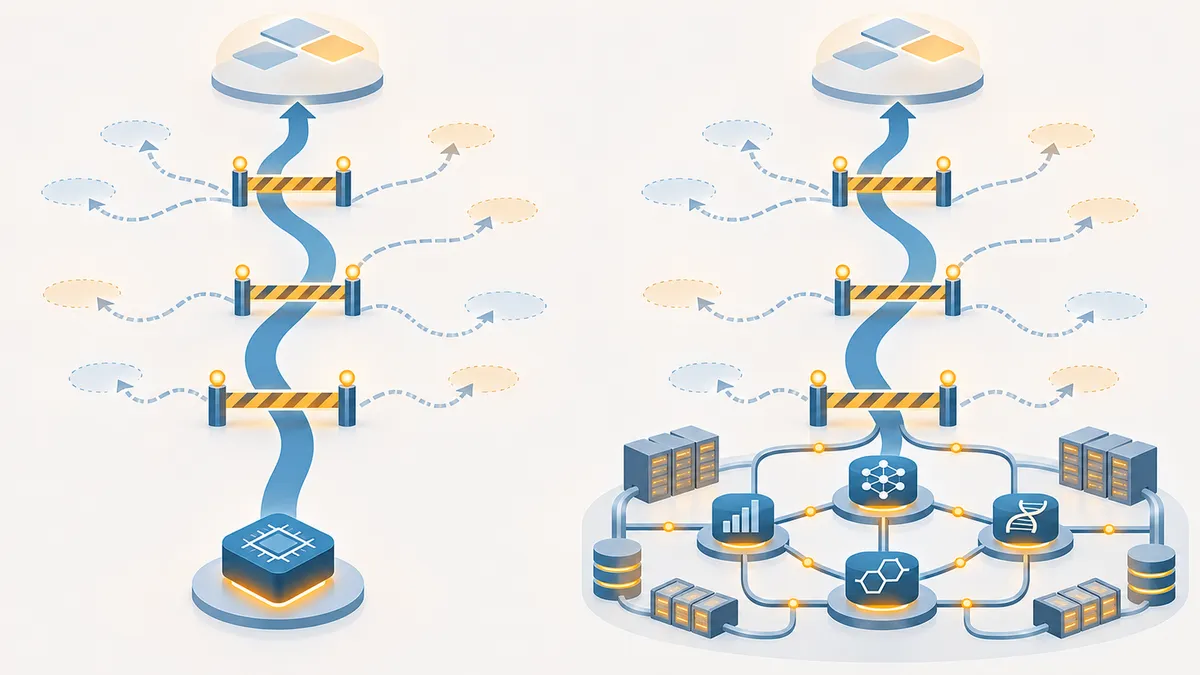
An AI system can tackle a business procedure alone, consult reusable instructions, or divide the work among specialists. A controlled benchmark comparison asks whether the extra machinery improves results enough to justify its cost.
Comparing designs on the same work
Checking business documentation or processing an intake form can require many linked decisions. An AI agent must interpret a procedure, choose software tools, carry information between steps and return an answer in the required format. Dividing that work among several agents might help—but it also adds coordination.
In Agent Architecture Cost–Success Trade-offs: A Controlled Evaluation across Enterprise-Style SOPs, Subhrangshu Nandi and colleagues compare four design families. The supplied manuscript is labeled arXiv version 1, dated 7 November 2026; it does not establish peer-review status.
The main methods and results describe 13 standard operating procedures, or SOPs, with 2,124 tasks per configuration. All configurations use the same Claude Opus 4.8 model and benchmark tools. The tools are simulations with fixed responses, helping separate architectural differences from unpredictable external services.
Eight configurations cover a single agent with all tools; a single agent using reusable procedural “skills”; a central coordinator assigning work to other agents; and a specialist swarm that passes control between agents. Variants change skill quality, worker access to information, or shared workflow guidance.
What counted as success?
The researchers compared final answers with benchmark reference outputs using a parser that allows some formatting variation. For answers containing several required fields, every field had to match. They also recorded tokens—the units of text processed by the model—elapsed time and model calls.
Their headline success rates give each SOP equal weight. This matters because strong performance on one heavily sampled procedure should not automatically outweigh weak performance elsewhere.
The single-agent baseline averaged 67.4% success. High-quality skills reached 73.1%, while degraded skills reached 59.8%. The first central-orchestration implementation achieved 58.2%; its redesigned successor reached 75.6%. Swarm variants ranged from 65.4% to 70.5%.
These averages are not a reliable universal league table. Performance varied substantially between procedures, and no configuration beat the baseline significantly in a sign test comparing SOP-level wins and losses. A separate random-effects analysis, which combines the size and uncertainty of procedure-level effects, did find an advantage for the redesigned orchestrator: an odds ratio of 1.72, with p = 0.007. These tests ask different questions; the result does not mean that multiple agents generally outperform one.
A redesign changed the outcome
The first orchestrator gave each worker only part of the procedure and a subset of tools. Workers lacking necessary information could return placeholder decisions rather than resolve the gap.
The redesign gave workers the complete procedure and tool set, prohibited placeholders, allowed the final synthesizing agent to resolve gaps, added one opportunity to send work back, and validated decision values. Patient-intake success rose from 13.6% to 98.5%.
That reversal supports a practical lesson: implementation details can outweigh the broad choice between single-agent and multi-agent systems. However, several changes were introduced together, so the experiment cannot identify which change produced how much benefit.
Skills showed a related vulnerability. The researchers used a five-part rubric covering discoverability, instructions, input/output contracts, disambiguation and governance metadata. Structural checks and a language-model judge assessed the definitions. Those scores verified that the skill collections differed; they did not establish that rubric scores predict task success.
One degraded skill omitted a required output-field name. The agent often selected the correct action but stored it under the wrong key. That is a genuine interface failure: downstream software expecting the specified field cannot reliably use the answer.
More machinery used more resources
In the main cost table, every non-baseline configuration used 1.4–4.7 times as many tokens and took 2.6–5.8 times as long as the baseline. The redesigned orchestrator achieved the highest average success but used 4.7 times the tokens and 3.1 times the elapsed time.
More guidance was not always better. A detailed, ordered swarm blueprint produced almost the same success as a simpler description of shared goals and stages, while using 42% more tokens and taking 39% longer.
These are resource measurements, not a calculated financial break-even point. Whether an improvement justifies extra cost depends on the application. A separate two-procedure experiment also found that restricting a skill’s available tools helped one workflow but hurt another; that evidence remains exploratory.
Why the conclusion remains provisional
The manuscript contains unresolved inconsistencies. Its main analysis reports 13 SOPs, but the conclusion and limitations refer to 12 and give different headline figures. The numbers above follow the main results tables. Despite describing a pinned comparison, the limitations acknowledge runs spanning multiple code revisions.
Scoring is another concern. The authors corrected parsing and denominator errors, but say an output-contract correction remains unverified for orchestration, leaving its multi-field results provisional.
Finally, this is one synthetic benchmark, one model family and one run per task, without an estimate of variation across repeated runs. Apparent benefits on more complex workflows were not statistically significant. The defensible takeaway is therefore narrow: start with a simple design, evaluate the actual procedure, and require evidence before paying for additional coordination—not assume that a larger agent system is better or ready for unsupervised high-stakes decisions.
- AI agents
- multi-agent systems
- standard operating procedures
- SOP-Bench
- tool use
- evaluation
- resource costs
- preprint
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Can executable workflows keep AI agents from skipping steps?
Source published
Shared keywords: ai agents, sop bench
Keeping AI workflow instructions separate from implementation know-how
Source published
Shared keywords: ai agents, standard operating procedures
MA-Mesh Gives AI Agent Teams a Way to Review and Replace Failing Peers
Source published
Shared keywords: multi agent systems
Can an AI agent remember a correction at the right moment?
Source published
Shared keywords: ai agents, tool use
Deception-Prompted AI Agents Had the Largest Effects in New Influence Tests
Source published
Shared keywords: multi agent systems