TRANSMISSION // 2611.12950v1
Tracing language-model origins through changes in their answers
Source published
SetPrint compares how two language models respond to identical prompt edits to look for evidence of shared origins. In one benchmark, it outperformed the evaluated training-free black-box alternatives, but detection remained incomplete at a low false-positive rate.
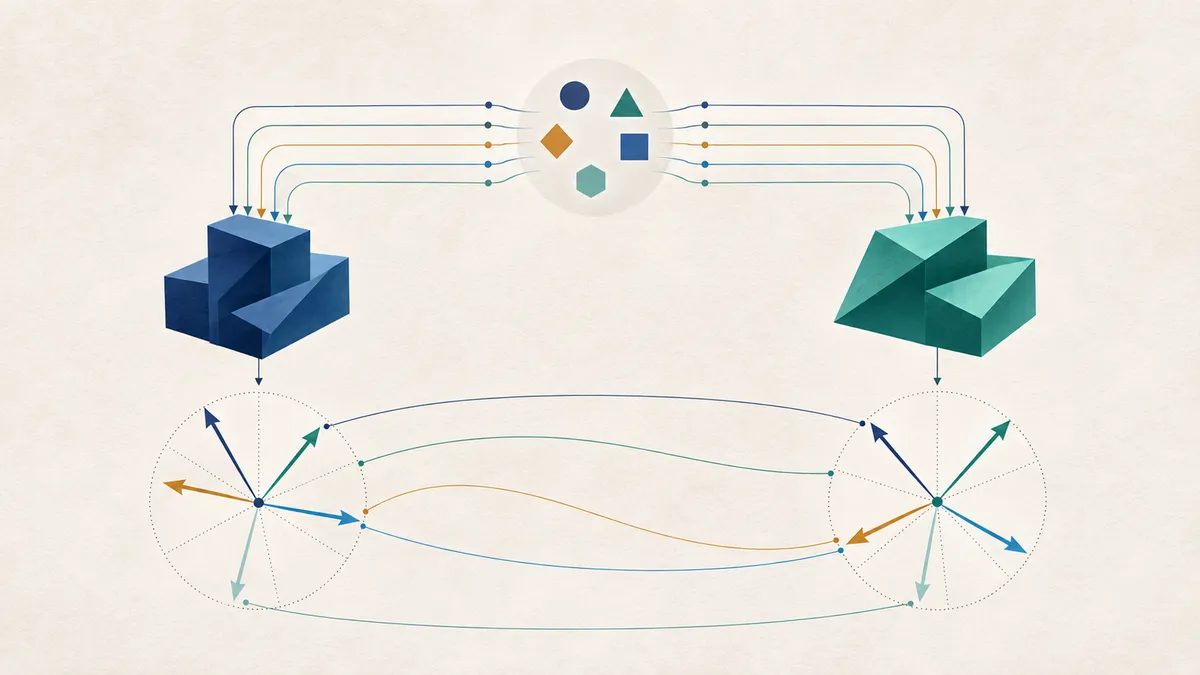
Two language models can give similar answers without sharing a direct lineage. A new preprint investigates a different clue: whether their answers change in corresponding ways when the same prompts are altered.
Looking beyond similar answers
Language models are often adapted and redistributed. Fine-tuning changes their behavior through additional training, while quantization changes how their numerical parameters are represented. These modifications complicate efforts to determine whether a deployed model came from a particular source.
Researchers at Seoul National University propose SetPrint, a method for investigating that relationship using generated answers alone. This is a black-box approach: it does not require inspecting either model’s parameters or hidden internal representations.
The supplied paper is version 1 of an arXiv preprint, dated November 7, 2026. Its results should be treated as preprint findings; the supplied text does not establish peer-reviewed publication.
A fingerprint made from response changes
Simply comparing answers is not enough. Independently developed models can produce similar text. SetPrint instead examines how answers change when prompts receive the same small edits.
The researchers begin with an original prompt and several altered versions. Both the source model and the target model answer every version multiple times. A fixed text encoder converts each answer into a numerical vector, called an embedding. Averaging those vectors helps reduce variation caused by random response sampling.
For each altered prompt, SetPrint subtracts the original prompt’s average answer vector from the altered prompt’s average answer vector. This produces a response-change vector. It then normalizes that vector so that particularly large changes do not dominate the comparison.
The distinctive step is to consider each change in the context of all the others. Within each model’s collection, SetPrint subtracts the collection’s mean change from every individual change. This removes the component common to the collection, leaving differences associated with particular perturbations.
Finally, it compares the centered changes produced by the same prompt edit across the two models, using an inner product, and averages these comparisons.
Another way to understand the score is that it measures how much similarity between correctly matched changes exceeds similarity between arbitrary pairs of changes. Higher scores are interpreted as stronger evidence of derivation, with a threshold needed for a yes-or-no decision.
“Training-free” means SetPrint does not train a fingerprinting classifier. It still relies on an existing text encoder.
What the benchmark showed
The evaluation used LeaFBench, containing 13 source models and 149 target model instances. Targets included fine-tuned and quantized variants, models with changed decoding settings, and models unrelated to the source under comparison.
For each comparison, the researchers used four HumanEval prompts, truncated to their first 20 words. Each received four perturbations, made by randomly swapping adjacent characters in five words. Sampling ten answers for each original and altered prompt required 200 responses per model, producing 16 response-change vectors.
Across five runs, SetPrint achieved an AUROC of 0.776 ± 0.008. AUROC measures how well scores distinguish derived from unrelated targets across decision thresholds; 0.5 indicates chance-level ranking and 1 indicates perfect separation. It is not an accuracy percentage.
At an empirical false-positive rate no greater than 1%, SetPrint’s reported true-positive rate was 40.3% ± 0.2 percentage points. Thus, even at its improved performance, many derived targets were not detected under this low-false-positive criterion. Its standardized partial AUROC over false-positive rates from 0% to 5% was 0.704 ± 0.004.
SetPrint led the evaluated training-free black-box methods on all three measures. It did not lead every method in the table: the supervised black-box LLMDNA-plus-SVM method and the white-box REEF method had higher AUROC scores, while requiring different supervision or access.
Why matching and centering matter
The researchers tested the importance of matching individual prompt edits by shuffling the target response changes. Shuffling only within each original prompt reduced AUROC to 0.746. Shuffling across the entire collection reduced it to 0.494, near chance.
Centering also helped. Comparing matched changes without subtracting their collection means achieved AUROC 0.755, versus SetPrint’s 0.776. A separate experiment altered nonmatching comparisons while preserving matching ones; performance declined as more were replaced. Together, these analyses support contributions from both correspondence and collection-level context.
What remains uncertain
The reported uncertainty values are sample standard deviations across five runs, not confidence intervals. Several baseline results were taken from earlier work, while others were rerun by the authors.
The evidence comes from one benchmark and a specific prompt-and-perturbation recipe. It does not establish performance across arbitrary deployments or deliberate attempts to evade detection. The reported metrics also do not select a deployment threshold. SetPrint provides a behavioral signal of model provenance, not a guaranteed determination of ancestry.
- SetPrint
- large language models
- model provenance
- black-box fingerprinting
- response changes
- LeaFBench
- preprint
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Finding surprising shopping patterns without abandoning statistics
Source published
Shared keywords: large language models
Similar examples give AI coding models a modest boost in a selected test
Source published
Shared keywords: large language models
AI radiology summaries can miss small words with important meanings
Source published
Shared keywords: large language models
Can a language model build a neural network from physical laws?
Source published
Shared keywords: large language models
A spreadsheet map can help AI ask for less data
Source published
Shared keywords: large language models