TRANSMISSION // 2611.12941v1
AI safety may depend more on access than intelligence, preprint argues
Source published
A theoretical framework and simplified simulations suggest that restricting AI systems’ permissions and access to sensitive knowledge could constrain harmful capabilities. But the results depend on assumptions about experimental delays and authorization barriers, not tests of deployed AI.
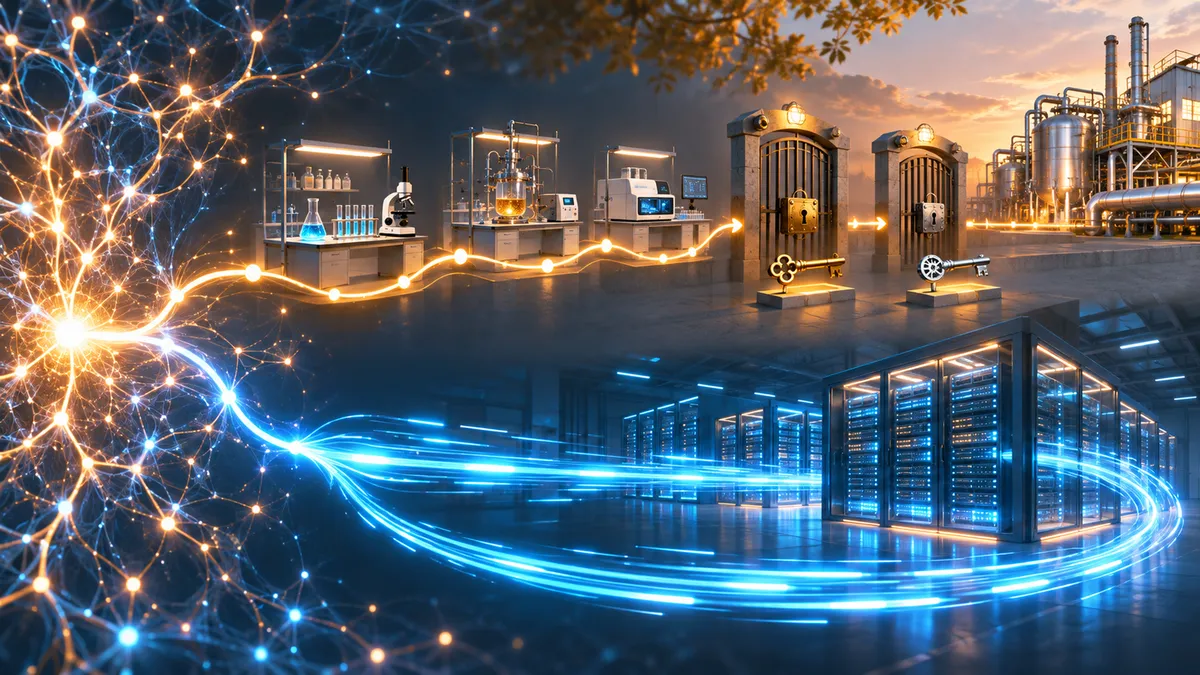
A powerful AI might identify a promising experiment quickly without being able to make that experiment finish sooner. That distinction anchors a preprint by Hendrik Luuk, who argues that AI governance should prioritize what autonomous systems can access and do—not focus on intelligence alone.
The paper examines a specific concern: whether an AI that rapidly becomes more intelligent could also rapidly acquire capabilities sufficient for catastrophic harm. Luuk’s answer is conditional. Where progress requires new physical experiments or independently authorized actions, better reasoning may not remove the bottlenecks. Where knowledge and powerful tools are already accessible, especially in digital environments, escalation could be much faster.
Separating reasoning, knowledge and authority
Luuk proposes a “competence circuit” with three routes to real-world impact: reasoning combined with knowledge and control; established procedures combined with control; and control alone. An agent need not invent anything if it already has instructions and permission to execute them. Likewise, direct authority over a consequential system can matter even without sophisticated understanding.
This is a conceptual accounting framework, not a calibrated equation for predicting harm. Its purpose is to distinguish being able to work something out from knowing enough to act and possessing the tools or authority to do so.
The paper also breaks rapid catastrophic escalation into stages: reaching high intelligence, obtaining sufficient knowledge, acquiring decisive control, and misusing the resulting capability. Slowing one stage could interrupt that particular route. The framework does not establish that every possible catastrophe follows this chain.
How the simulations worked
To explore these ideas, Luuk used artificial search problems called NK fitness landscapes. Each simulated environment contained 100 binary dimensions whose interactions determined a performance score. Prerequisite relationships meant that some candidate improvements became accessible only after earlier discoveries.
Agents selected and tested candidates, keeping changes that improved performance. Unproductive candidates added search noise. A parameter called beta controlled selection: higher-beta agents more often chose the best immediately available improvement, while lower-beta agents more often selected randomly. These labels represent behavior inside the model, not measured intelligence levels of actual AI systems.
Six scenarios varied starting knowledge, noise, testing time and authorization delays. Five agent settings and 100 repetitions per scenario produced 3,000 runs. The main outcome was time to the last performance improvement, rather than a real-world measure of dangerous capability.
Faster search is not necessarily fast progress
In the reported simulations, the agent labeled “superintelligent” reached its final performance between 1.8 and 8.9 times faster than the “regular” baseline. The smallest advantage appeared when the search contained no added noise: there was less wasted exploration to eliminate.
Authorization delays reduced the advantage. In the digital scenario, adding ten strategically placed chokepoints increased the higher-performing agent’s mean completion time from 10.5 to 51.5 model time units. Its advantage over the regular baseline fell from 8.6-fold to 2.8-fold. Mandatory waits consumed a larger proportion of the efficient agent’s otherwise short timeline; the result does not mean it became slower than the baseline.
The paper also derives a mathematical ceiling on speedup for selecting the next productive candidate from a fixed pool with equal testing costs. That ceiling is the ratio of the agents’ beta values. The simulated completion-time ratios stayed below the corresponding ceilings, but this is not a universal bound on real AI progress: the derivation concerns a narrower search process, while candidate pools evolve during the simulations.
What the model cannot establish
The strongest assumption is that intelligence cannot change the duration of a test. Longer testing times therefore impose delays by construction. Real systems might develop faster assays, informative proxies or experiments that answer several questions simultaneously. The simulations do not model those possibilities, nor do they capture the full roles of transfer learning, abstraction or strategic planning.
The digital and physical scenarios also differ in landscape complexity as well as testing time, preventing a clean attribution of their timing difference to latency alone. Authorization barriers impose unavoidable costs in the model; the experiments do not demonstrate that actual institutions could prevent circumvention or manipulation.
Luuk consequently calls for testing these ideas on real autonomous AI systems. Proposed safeguards include least-privilege access, compartmentalized information and independent approval for consequential actions. The preprint offers a rationale for those measures, not evidence that they are sufficient. Its central caution cuts both ways: intelligence alone does not confer unlimited power, but substantial power may already be dangerous without exceptional intelligence.
- AI governance
- autonomous AI agents
- access control
- AI safety
- experimental bottlenecks
- simulation
- preprint
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
When AI agents change, should their permissions change too?
Source published
Shared keywords: access control
Conflux puts permission checks outside the language model
Source published
Shared keywords: access control
Responsible AI depends on whose knowledge shapes the design
Source published
Shared keywords: ai governance
Surveyed AI users report larger transparency gaps than builders
Source published
Shared keywords: ai governance
When AI gets the answer right, what should people understand?
Source published
Shared keywords: ai governance