TRANSMISSION // 2611.12938v1
Graph diagrams can help AI answer questions—but clutter limits the gains
Source published
A preprint testing six vision–language models reports modest improvements when knowledge-graph diagrams accompany textual facts. Benefits were concentrated in smaller graphs, while layout choices could help or hurt performance.
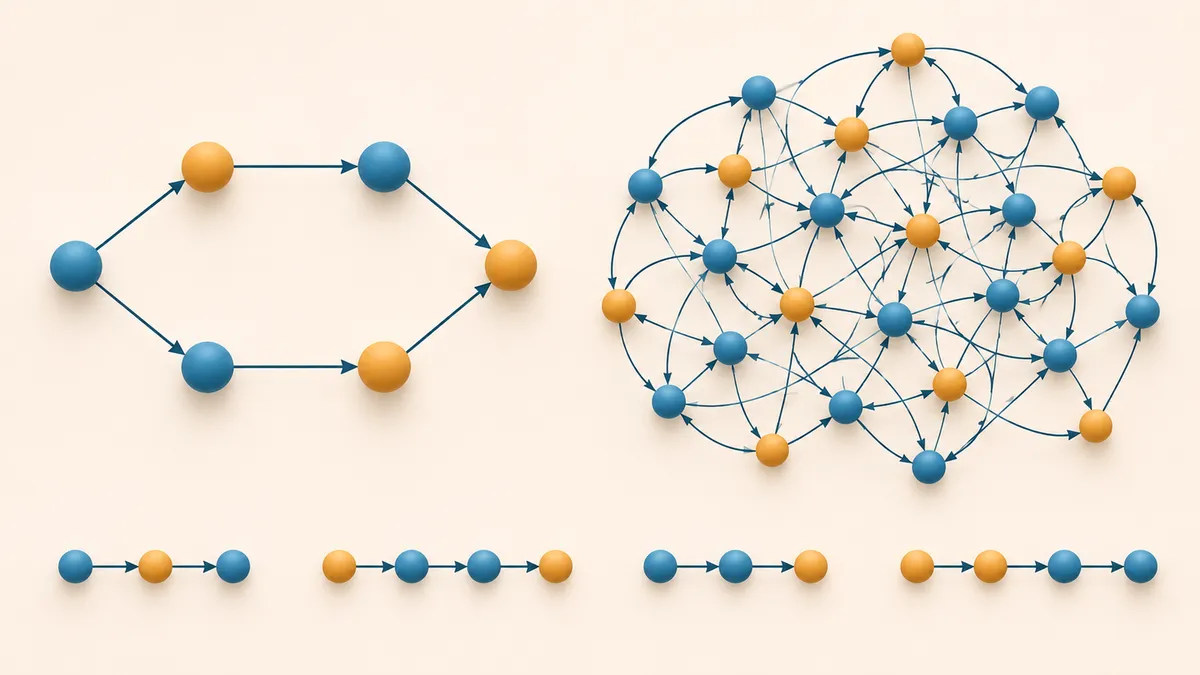
Giving an AI system a diagram does not necessarily help it answer a question. In a study of knowledge-graph question answering, researchers found that pictures added useful support mainly when the underlying information was relatively simple and clearly arranged. Dense diagrams offered little average benefit, and replacing text with an image made performance substantially worse in one tested model.
Testing pictures without changing the facts
Knowledge graphs represent information as entities connected by relationships: a person played for a team, for example, or a country uses a language. Question-answering systems can retrieve these connections and give them to a language model as evidence.
Luiz do Valle Miranda, Andreas L. Opdahl and Grzegorz J. Nalepa investigated whether showing that evidence as a diagram improves answers beyond supplying it as text. Their preprint examines prompting at answer-generation time, rather than training models to interpret graphs.
The researchers assembled 1,500 questions, split equally between the WebQSP and Complex WebQuestions benchmarks. They used previously released evidence paths from the Reasoning on Graphs pipeline, converting them into distinct subject–relationship–object facts, known as triples.
Six vision–language models from the Qwen, Mistral and Gemini families answered questions under two main conditions: text alone, or the same text accompanied by a graph image. The images used Graphviz’s hierarchical layout, with connections flowing from left to right. Keeping the retrieved evidence fixed helped isolate the effect of adding its visual representation. No model fine-tuning was involved, and explicit reasoning modes were disabled.
A modest average improvement, concentrated in small graphs
The authors report an average increase of 1.85 percentage points in F1, from a text-only baseline of 75.14%. F1 balances precision—how many returned answers are correct—with recall—how many valid answers the system finds. Scores were calculated separately for each question before averaging, rather than pooling all answers together.
The reported 95% confidence interval for the F1 improvement was 1.30–2.42 points. Precision rose by 2.89 points, while recall increased by just 0.63 points. That pattern suggests diagrams helped more with excluding incorrect candidates than with finding additional correct ones.
The largest gains appeared in questions whose retrieved evidence contained seven or fewer triples: F1 improved by 4.65 points. For graphs containing eight to 25 triples, the reported improvement was 0.47 points; above 25 triples, it was 0.28 points. Recall declined slightly in both larger-graph groups.
These categories should not be read as clean measures of reasoning difficulty. Counting triples combines several factors: how much evidence is present, how complicated its relationships are, and how crowded the resulting image becomes.
Layout mattered, and text remained important
Additional experiments used only Qwen3.5-35B-A3B to compare visual formats. Relative to that model’s text-only baseline, a hierarchical graph image improved F1 by 2.40 points. A non-hierarchical Graphviz rendering produced a smaller 0.87-point gain, while a NetworkX force-directed layout reduced F1 by 0.40 points.
The strongest result among these variants came from splitting the evidence into separate path diagrams, which improved F1 by 3.03 points. This suggests that breaking up a crowded picture may help, although the experiment did not separate the effects of image size, density and path organization.
Providing the graph image without the textual facts reduced F1 by 9.42 points. In this setting, diagrams were useful supplements, not effective replacements for text.
Selected examples illustrate both directions of change: a diagram helped the model reject a frequently mentioned but incorrect baseball team, whereas another graph diverted it from a correct answer toward an irrelevant person. Such examples suggest possible explanations, but do not establish how the model internally processed the images.
What the findings leave unresolved
The study covers two benchmarks, one retrieval pipeline and six models; its layout comparisons cover just one model. The researchers found no statistically strong evidence that relative model size changed the benefit, but that is not proof that scale never matters. Some regression baselines and model-level figures also differ across the paper’s tables, figure and prose, warranting clarification before relying on fine-grained comparisons.
The authors propose adding diagrams selectively: retain text, favor readable layouts, and avoid presenting dense evidence as one large graph. That adaptive policy remains a recommendation rather than a demonstrated system. Image-processing costs and latency were not measured, so the experiments do not establish whether the modest average accuracy gain justifies the additional expense.
- knowledge graphs
- question answering
- vision-language models
- visual prompting
- graph visualization
- preprint
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
ArcRAG Tests Whether AI Can Search Differently Built Knowledge Graphs
Source published
Shared keywords: knowledge graphs
GraphRail checks the evidence behind search agents’ reasoning
Source published
Shared keywords: knowledge graphs
How well can AI see the details biologists need?
Source published
Shared keywords: vision language models
Giving AI Agents an Explicit Reason to Look
Source published
Shared keywords: vision language models
Protecting the relationships an AI search system can reveal
Source published
Shared keywords: knowledge graphs