TRANSMISSION // 2611.12928v1
A Video Link That Sends the Important Parts First
Source published
Ti-SemCom is a proposed system for reducing the data sent in wireless video. It uses detected objects and motion to assign video regions priority levels, sends higher-priority tokens first, and reuses recent reconstructed content for regions not updated. In tests on CAVIAR indoor public-environment video, the authors report 88.3% less transmitted data than full-token transmission at 5% of the reference bandwidth, while maintaining 30 frames per second in the simulated conditions. A separate prototype achieved 8.4 frames per second. These results come from limited reported setups and an arXiv preprint; they do not establish performance across other videos or networks.
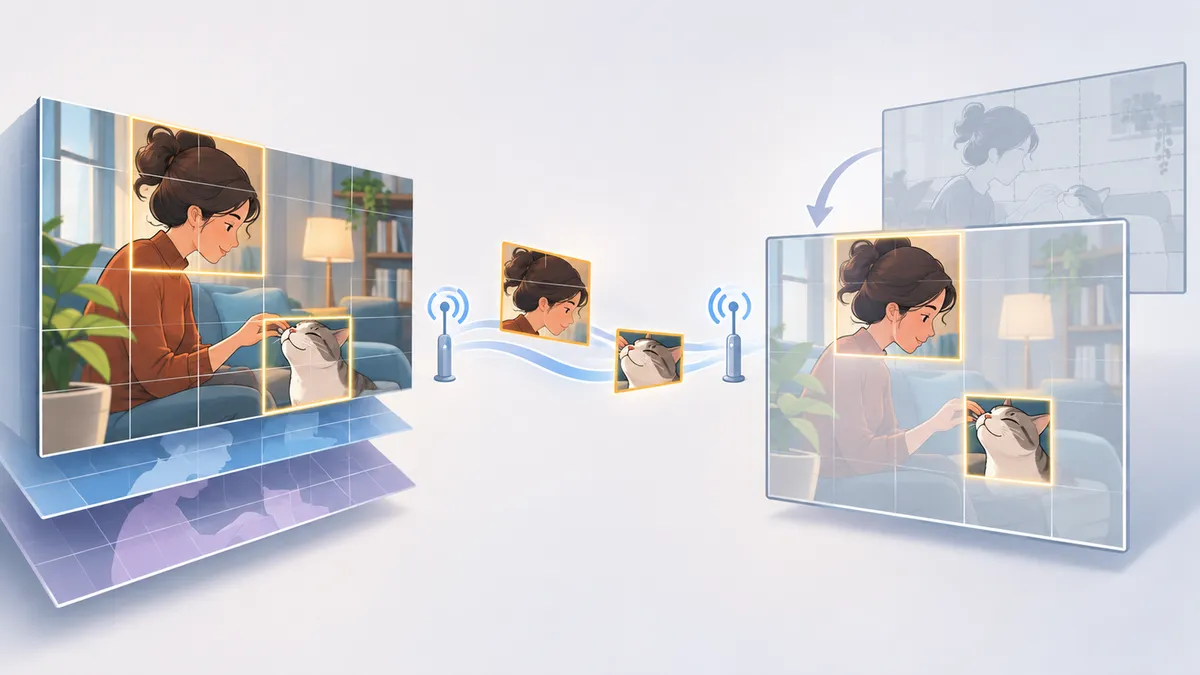
When a wireless link cannot carry every video update, how should it spend its limited capacity? A preprint proposes sending information about some regions more often than others, using detected objects and motion to set priorities. Tests on one video dataset report substantial data savings, but the results do not establish how the method would perform across other settings.
The bandwidth problem
Video streams carry a large amount of information, and each new frame can require another update. When bandwidth is limited or a wireless channel is noisy, sending everything may make delivery and reconstruction difficult. The paper asks whether a sender can use its capacity more selectively, while allowing the receiver to reuse recently reconstructed content where no new information arrives.
The proposed method, Ti-SemCom (token-importance-aware semantic communication), represents each frame as semantic tokens: compact pieces of information associated with image regions. It places regions into three priority levels. Detected motion and objects designated as critical for the application receive the highest priority; other detected objects come next; areas outside the object and motion masks receive the lowest priority.
How the system works
At the sender, object detection and motion estimation produce masks that identify regions. An importance map is aligned with the encoder’s token grid, and tokens inherit the priority of their corresponding regions. The system adjusts which groups it transmits according to the bandwidth available for a frame, keeping higher-priority groups before lower-priority ones. It selects whole priority levels rather than ranking every token individually.
At the receiver, transmitted tokens are decoded to reconstruct the current frame. Regions without a current update are filled with content from the most recently reconstructed reference frame. This reuse is intended to reduce repeated transmission of lower-priority content.
The authors evaluate Ti-SemCom on CAVIAR, which they describe as video recorded in indoor public environments. They compare it with a semantic-communication system that sends all tokens and with H.265 video coding combined with channel coding. The experiments use an additive white Gaussian noise channel, QPSK modulation, several signal-to-noise ratios, and different bandwidth levels. Reconstruction is assessed with PSNR, a pixel-based measure, and SSIM, which measures structural similarity. The study also tracks effective frame rate and data reduction.
What the tests found
In the reported simulations, Ti-SemCom maintains a target effective rate of 30 frames per second across the tested bandwidth conditions. At 5% of the reference bandwidth, the authors report an 88.3% reduction in transmitted data relative to sending all semantic tokens. They report similar PSNR and SSIM across the tested bandwidth ratios at each tested signal-to-noise ratio, and better reconstruction metrics than the two comparison methods at 20% and 5% bandwidth.
The results do not imply that every image region is reconstructed equally well. In a separate test that retained all tokens, increasing the training-loss weight for the highest-priority regions improved their PSNR but reduced full-frame PSNR. This indicates a trade-off in that experiment between reconstruction quality in high-priority regions and quality across the whole frame.
The paper also reports a prototype with an NVIDIA Jetson Orin NX transmitter and a PC receiver. At a link rate of 288 kilobits per second, the prototype achieved 8.4 frames per second. This is a result from the reported hardware setup, not the 30-frame-per-second simulation result.
What remains uncertain
The evaluation focuses on one dataset and a simulated noise channel, with a separate prototype demonstration on specified hardware. It does not establish how the method performs on other video types, camera conditions, wireless channels, or applications. Its priority assignments depend on the object and motion masks and on which objects are specified as critical. As a potential risk—not a result tested in the paper—mask errors or application priorities that fail to reflect a user’s needs could affect which details receive updates. Reusing old content could also potentially leave a changed region outdated when that region is not transmitted.
The 88.3% figure is relative to full-token transmission in the stated evaluation; it is not a general saving against video systems. Although H.265+LDPC is included as a comparison, the headline percentage is not reported as a reduction against that baseline. The source is an arXiv preprint, so the findings are the authors’ reported results, not independently established performance. The paper identifies task-driven adaptive importance modeling as future work, leaving open how priorities should change for different applications.
- wireless video
- semantic communication
- bandwidth adaptation
- video transmission
- preprint
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
STAR Gives Task-Relevant Image Pixels Stronger Protection
Supporting evidence: Both preprints report reduced communication resources from prioritizing visually important content in their own evaluations. Ti-SemCom reports 88.3% less transmitted data than full-token transmission at 5% of reference bandwidth on CAVIAR, with similar reconstruction quality across tested bandwidth ratios at each tested SNR. STAR reports 59.5% and 91.5% fewer resource elements than robust whole-image BPSK transmission with rate-1/3 convolutional coding on factory and vehicle-monitoring data, respectively, at matched semantic reliability. This supports only the bounded proposition that prioritization reduced resource use in these separate tested settings; their tasks, resource measures, baselines, and datasets differ, so the savings are not directly comparable.
Model review: · openai-codex/gpt-6-luna
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2611.12928v1 — Original paper
Excerpt reference:
static/papers/2611.12928v1.md:73-139
Basis: Paper text
Source SHA-256:2dbb043b1596bd74d846f4740eeda3ace0ab7dadddc11b069dbfb35928999abd2611.13238v1 — Original paper
Excerpt reference:
static/papers/2611.13238v1.md:13-63
Basis: Paper text
Source SHA-256:7e43882bbe11422deae5c53790f4da055cbff99cfd4506b07b92a8dd4c83c6712611.13238v1 — Original paper
Excerpt reference:
static/papers/2611.13238v1.md:131-194
Basis: Paper text
Source SHA-256:7e43882bbe11422deae5c53790f4da055cbff99cfd4506b07b92a8dd4c83c671
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.