TRANSMISSION // 2611.10806v1
WARP-JEPA speeds up AI planning by learning which routes to try
Source published
A preprint reports that learned candidate planners made simulated visual-control episodes up to 18.8 times faster while improving success on several benchmarks. The underlying world models stayed fixed, but the method required additional planner training and retained some gradient-based planning near episode endings.
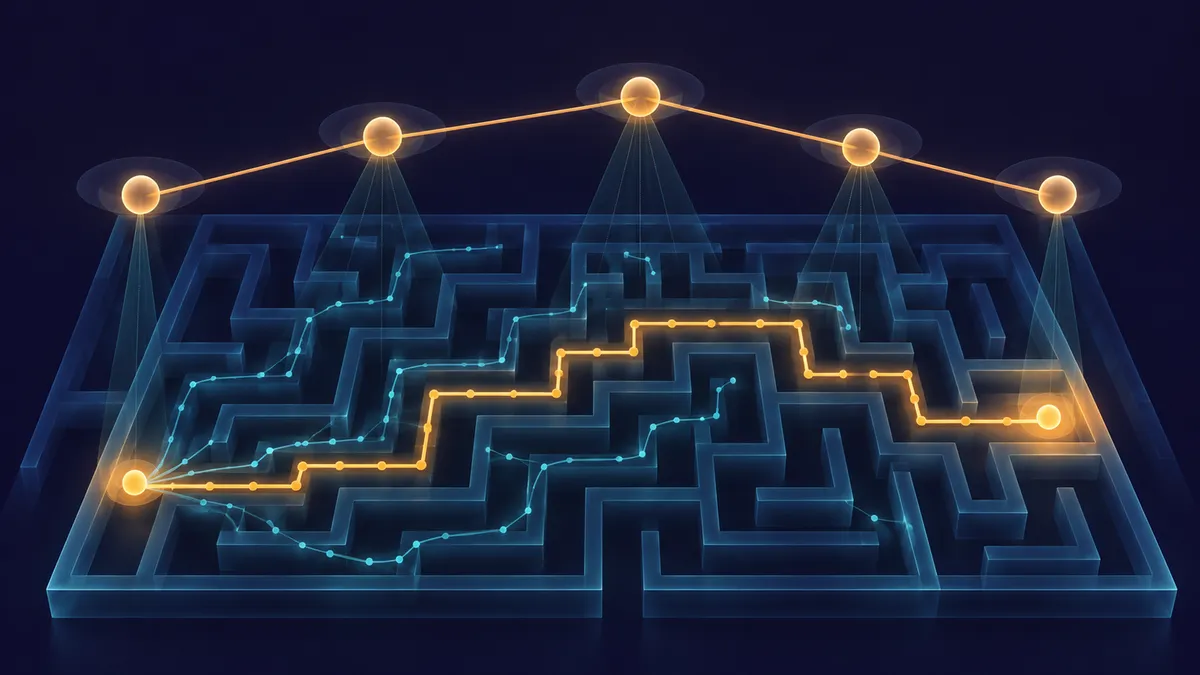
Can an AI controller make better decisions by spending less time optimizing them? WARP-JEPA replaces much of a hierarchical planner’s repeated trial-and-adjust computation with learned proposals, then uses the existing world model to choose among them.
An AI system can predict the consequences of an action without being good at choosing one. That distinction is central to WARP-JEPA, a planning method described by Junjie Li and colleagues at Shanghai Jiao Tong University in a November 7 preprint. Their experiments suggest that changing how a controller searches for actions can improve both speed and success without changing its predictive model.
The study concerns hierarchical joint-embedding predictive architectures, or H-JEPAs. These systems turn images into compact numerical representations and predict how those representations change under actions. Their hierarchy divides planning across timescales: upper levels choose longer-range actions and intermediate targets, while lower levels translate those choices into shorter movements.
The original planner repeatedly adjusts candidate action sequences using gradient descent. It asks how each adjustment changes the model’s predicted distance from the goal, then updates the sequence. Nested across several levels, that process becomes expensive. In the authors’ timing runs, planning occupied 96.6–97.7% of episode runtime on the longer-horizon benchmarks.
Learn proposals, then check them
WARP-JEPA moves much of that work into a separate training stage. Small neural networks learn to propose multiple action sequences from the current situation and goal. During execution, the frozen world model evaluates the candidates, and the planner selects the one with the lowest predicted cost.
Training combines two objectives. One encourages proposals that the world model predicts will reach the target. The other rewards agreement with recorded training actions, a technique called behavior cloning. This second objective is intended to discourage actions that look promising only because they exploit inaccuracies in the predictor.
Multiple candidates matter because different routes can reach the same goal. Averaging a leftward route and a rightward route need not produce a useful middle route. The default system generates 32 candidates at the top level and 16 at each subordinate level, preserving alternatives for model-based selection.
The architecture also differs across levels. At the top, a one-layer Transformer generates actions sequentially, consulting the world model after each imagined action. Its next proposal therefore depends on the predicted intermediate state, not just the starting point and destination. Lower levels use feed-forward networks to generate short action sequences in parallel. The top-level predictions already produced during generation are reused for candidate scoring.
Faster episodes, with uneven gains
The researchers evaluated 30 frozen world models: three training seeds across ten combinations of benchmark and hierarchy depth. The four simulated benchmarks were Push-T, FourRoom, Visual AntMaze and OGBench Cube. Success evaluations used 250 tasks per seed for Push-T and 50 elsewhere.
Across the longer-horizon settings, the learned planners reduced episode runtime by factors of 9.6–18.8 compared with the gradient-descent baseline. On two-level Push-T, the default mixed architecture reduced runtime from about 25.3 seconds to 1.34 seconds, while mean success increased from 40.8% to 64.7%.
On two-level Visual AntMaze, success rose from 45.3% to 78.7%, a gain of about 33.3 percentage points. Cube showed smaller speedups, around threefold. There, the all-feed-forward variant achieved 80.7% success against the baseline’s 48.0%, exceeding the default architecture’s 74.0%. No single architecture was best everywhere.
The timing evidence is narrower than the success evaluation: episode runtimes were measured on one NVIDIA H200 GPU, using one model seed and ten tasks per setting. These are benchmark-specific measurements, not established speedups for physical robots or other hardware.
A better model score is not necessarily better control
A separate Push-T experiment illustrates the problem with trusting the predictor’s score too literally. Gradient descent achieved a much lower predicted terminal cost than a learned planner, yet recorded 42% success against the learned planner’s 48%. That success difference was not statistically significant in the 150-task comparison. The result nevertheless shows why a lower internal cost cannot simply be read as better task performance.
Important limits remain. The method does not eliminate gradient descent entirely: end-of-episode fallback solves still use ten optimization iterations, and those solves are included in the reported timings. Each frozen model also needs additional proposer training, with reported default training times ranging from 0.2 to 3.6 hours per proposer on an H200.
Nor can a new planner repair every predictive weakness. With four-level Push-T models, average success remained at or below 1.2% for every planner. The authors attribute this failure to temporal abstraction that is too coarse for the task’s contact dynamics.
The work is a preprint, not established peer-reviewed evidence. Its central finding is bounded but useful: in these simulated tasks, learned proposals often made a fixed world model more effective to plan with, without making that model itself more accurate.
- WARP-JEPA
- hierarchical world models
- visual control
- amortized planning
- behavior cloning
- candidate selection
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.