TRANSMISSION // 2611.10768v1
BlenderFORGE trains AI models to make measurable 3D edits
Source published
BlenderFORGE, available on arXiv and reported as accepted at NeurIPS 2026, helps open-weight AI models edit Blender scenes through Python code. Performance improves substantially on controlled tasks, but precise editing and broader generalization remain difficult.
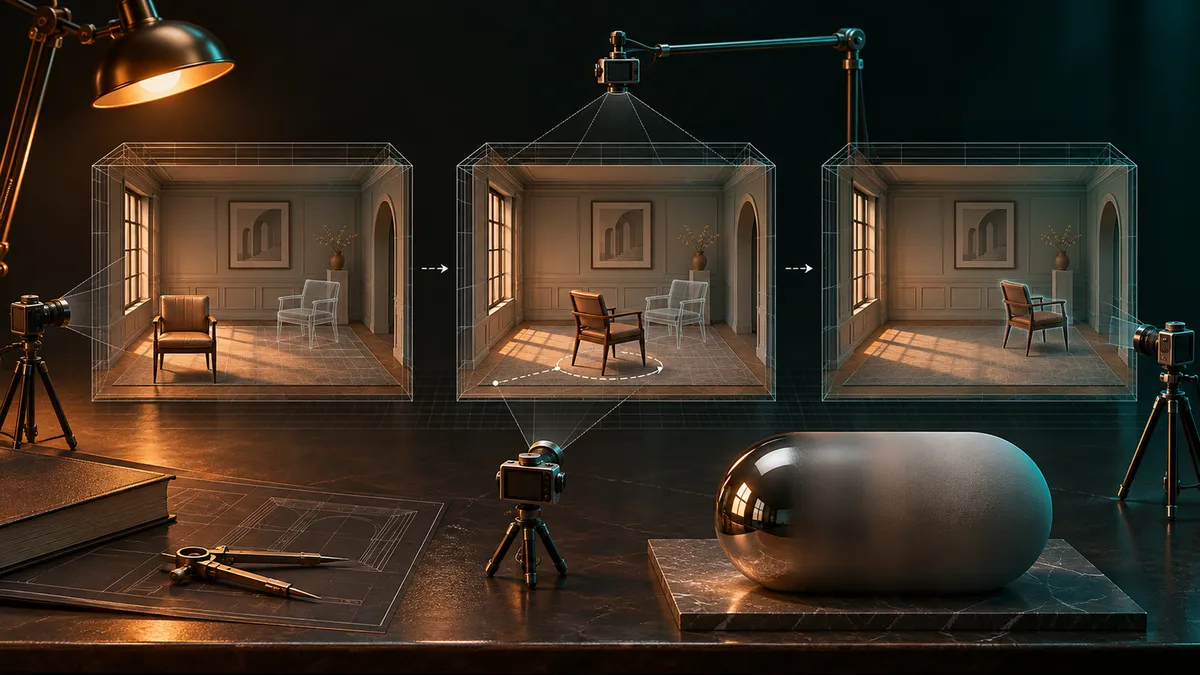
Seeing that a chair needs moving is different from writing the code that puts it in the right place. BlenderFORGE tackles that gap by letting AI models practice edits inside Blender, inspect the results and learn from measurable progress.
How do you teach an AI to change a three-dimensional scene rather than merely describe it? In the BlenderFORGE paper, researchers from the Hong Kong University of Science and Technology and SenseTime Research combine generated editing exercises, a controlled Blender environment and two stages of model training. The work is available on arXiv, whose record reports acceptance at the peer-reviewed NeurIPS 2026 conference.
Their aim is not to generate a finished world from a sentence. It is to improve an agent’s ability to modify an existing scene through Blender’s Python interface, known as bpy. The findings come from computational experiments, not a study of professional users.
Turning scenes into exercises
The framework covers four editing families: moving and rotating objects, adjusting predefined shape deformations, changing lighting, and modifying materials. Shape deformations use Blender’s “shape keys”—numerical controls that blend between predefined versions of an object’s geometry. Material controls include properties such as color, roughness and metallic appearance.
To generate exercises, the researchers take existing assets and change selected attributes, producing a starting scene and a target scene. The agent receives information about the starting scene alongside matching camera views of the start and target. It must infer and execute the necessary changes.
The pipeline rejects unsuitable examples, including placement cases with invalid collisions or changes that are insufficiently visible. Material examples undergo additional checks for rendering stability. The training split contains 3,000 placement tasks and 2,000 tasks in each other family; each family has 200 test tasks.
This setup makes the problem measurable, but also deliberately constrained. The agent generally sees pictures of the desired result, rather than having to interpret an open-ended request without a visual target.
Practice with executable feedback
Each editing episode runs in a separate Blender process. The agent can execute Python code and request preview images, then use the feedback to revise its work. Structured scene exports let the framework inspect numerical properties as well as rendered appearance. Fixed rendering settings help keep comparisons reproducible.
Training begins with supervised fine-tuning: the model learns from editing trajectories produced by GPT-5.2 acting as a teacher. Additional question-answering, function-calling and coding examples are intended to preserve broader abilities.
The second stage uses reinforcement learning. Agents try edits inside the environment and receive rewards based on progress toward the target. Depending on the task, progress is measured through geometry, scene parameters or image differences. A small auxiliary reward encourages executable editing actions, but the main reward comes from task progress.
The researchers train two open-weight models, Qwen3-VL-8B and Qwen3.5-9B, each jointly across all four editing families. Open weights do not mean the entire training process avoids proprietary models: the initial demonstrations come from a proprietary teacher.
Large gains, not reliable completion
The trained Qwen3.5-9B model improves substantially over its starting version. On placement tasks, its success rate at the paper’s 0.5 threshold rises from 3% to 40%.
That threshold needs careful interpretation. It means the remaining geometric discrepancy is no more than half the initial discrepancy—not that the scene is perfectly matched. At the stricter 0.1 threshold, the trained model reaches 15.5%, compared with about 27.1% for the zero-shot GPT-5.2 baseline, which receives no task-specific training.
For shape-key editing, the 9B model’s success rate at the 0.5 threshold rises from 6% to 27.5%. However, its median normalized shape-key discrepancy remains unchanged at 1.00. Improvements are therefore not uniform across measures.
Experiments separating the training components also reveal a qualification. For the 8B model’s placement tasks, the full pipeline reaches 36% success at the 0.5 threshold. Yet adding reinforcement learning to trajectory training without the general-purpose training stage reduces success from 24% to 21%. Reinforcement learning is not automatically beneficial in every configuration.
How far does the learning travel?
On the separate BlenderGym benchmark, the trained 9B model improves on all reported measures across placement, shape-key and lighting tasks. Material editing is excluded because of a Blender-version API incompatibility.
A smaller camera-reframing experiment tests a task family absent from training, using written instructions without target images. Both trained models improve over their bases, but only 35% of their attempts are valid, and pointing errors remain large.
Other limitations matter. Some shape-key base meshes are shared between training and test splits, weakening evidence for transfer to entirely unfamiliar objects. The main model comparisons lack confidence intervals or significance tests. Image-similarity measures are also proxies, not guarantees of correct edits.
BlenderFORGE therefore supports a focused conclusion: training with executable, measurable feedback can improve controlled Blender editing. It does not establish dependable general-purpose 3D assistance, unrestricted language-driven editing or transfer to other graphics software.
- BlenderFORGE
- 3D graphics editing
- multimodal language models
- Blender
- reinforcement learning
- open-weight models
- tool-using agents
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
When an AI’s training score rises but its answers get worse
Source published
Shared keywords: reinforcement learning
AI can read an image yet struggle to reason about it
Source published
Shared keywords: reinforcement learning
AI judges can check evidence and still follow a false expert cue
Source published
Shared keywords: tool using agents
Can switching off AI safety components make a model harder to jailbreak?
Source published
Shared keywords: open weight models
Coordinated AI agents improve vulnerability exploitation in controlled benchmarks
Source published
Shared keywords: open weight models