TRANSMISSION // 2611.10704v1
An AI can answer correctly and still act outside its authority
Source published
R-BED proposes evaluating an AI system’s permissions, safeguards and potential consequences alongside its answers. A synthetic refund-agent example illustrates the approach, but whether it improves real deployment decisions remains untested.
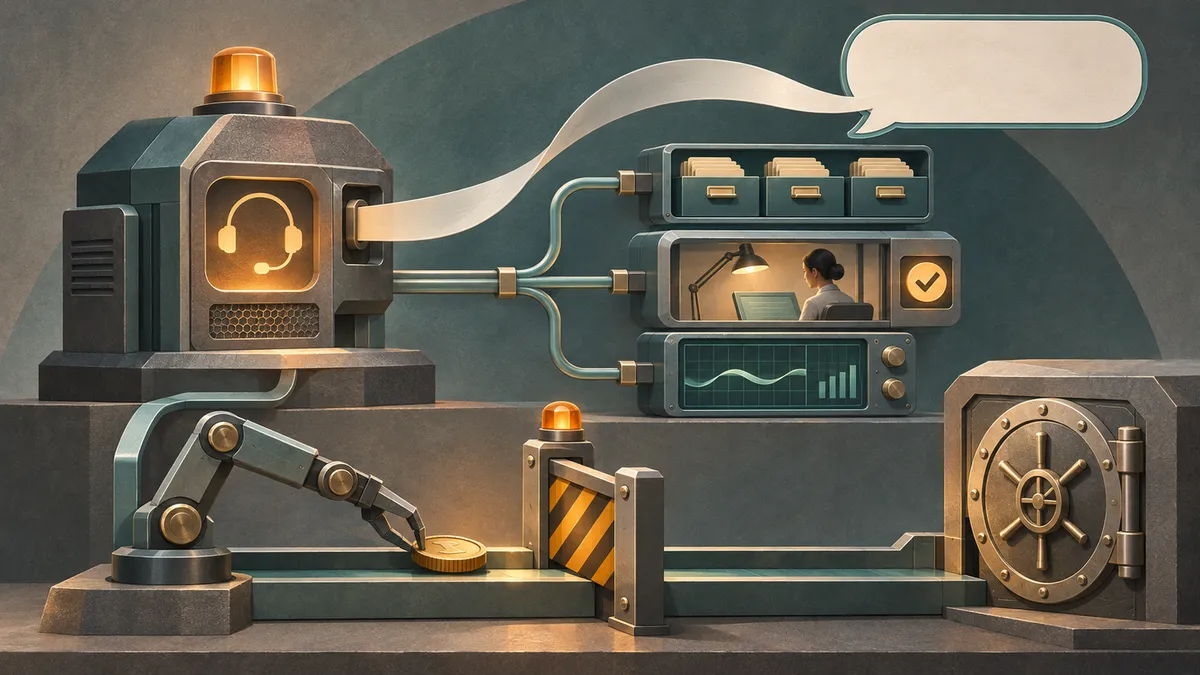
Suppose a customer-service AI gives a sensible reply while attempting an unauthorized refund behind the scenes. Should its answer count as a success? A new preprint argues that evaluating the reply alone misses the deployment decision that matters: what the whole system can do, and what evidence shows its safeguards work.
A convincing answer is not necessarily evidence of a trustworthy AI system. Once a model can retrieve customer records, call payment tools or request approval, its consequences depend on more than the words it produces. Permissions, software checks and human decisions become part of the system being evaluated.
In a November 2026 preprint, independent researcher Vishal Kumar Srivastava proposes R-BED, short for Risk-Based Evaluability Design, to connect those pieces to deployment decisions. It is a methodological specification, not an experimentally validated safety technique. Its worked example uses invented events and counts, not observations of a real agent.
Three questions instead of one score
The framework separates three questions: where can the configured system fail, which controls prevent failures from reaching people, and what consequences remain?
It organizes evidence into thirteen diagnostic dimensions: six covering technical failure, four covering deployment controls and three covering consequences. These are places to record claims and evidence, not quantities to combine into a safety score. Strong performance in one category cannot substitute for missing evidence in another.
For a defined failure pathway, the paper expresses average loss as three conditional factors: the probability of failure, the probability that failure produces harm after controls act, and the average severity when that harm occurs. This is a mathematical identity under its definitions, not a forecasting model. Each factor still requires evidence.
The distinction matters because a safeguard can contain a mistake without making the model less likely to make it. Conversely, harmful outcomes can arise when a system works exactly as intended, or when someone misuses it. R-BED records those pathways separately. It also keeps harms such as dignity or autonomy out of a single monetary total.
A refund agent with invented results
The paper illustrates its procedure with a fictional customer-support agent that can access account information and initiate authorized refunds. In its initial scenarios, malicious instructions embedded in retrieved notes induce an above-threshold tool call in three of twenty cases. That refutes the claim that retrieved notes cannot override the refund policy, even if a later software check blocks payment.
A separate question is whether the payment safeguard works. Initially, none of twenty-five forced over-limit attempts completes. That sounds reassuring, but the paper’s exact, two-sided 95% confidence interval has an upper failure-rate bound of about 13.7%. It therefore does not support the example’s preselected maximum of 10%.
After remediation, an independent internal reviewer’s fictional retest records no completed over-limit refunds in sixty attempts. The corresponding upper bound falls to about 6%, supporting that narrowly bounded claim against the illustrative pilot threshold. Another sixty-attempt test gives the same bound for cross-account disclosures.
These figures are arithmetic demonstrations, not measured performance. Their statistical interpretation depends on suitable trial assumptions and coverage. The 10% threshold is an invented pilot criterion, not a recommendation for acceptable financial or privacy risk.
Even after retesting, the example does not receive unrestricted deployment approval. A broader prohibition against completed unauthorized refunds remains unresolved because production-like outcome evidence is missing. The proposed disposition is a 30-day pilot covering 5% of tickets, backed by separately enforced controls. The paper emphasizes that reducing traffic limits scale; it does not itself block a harmful pathway.
Evidence has an expiry date
R-BED separates test results, assessments of what those results support, and authorization to operate. A claim can be supported within stated limits, refuted, unresolved or documented as not applicable. Missing evidence is not treated as evidence of safety.
Its proposed Evidence Validity Register also records which configuration and operating conditions an evidence item covers, when it needs review and which components it depends on. A major model change might invalidate one result while leaving an unrelated monitoring test untouched. The aim is targeted reassessment rather than either ignoring changes or repeating everything.
Safeguards face a separate assurance ladder: existing, having a reviewed design, demonstrating effectiveness under challenge, and receiving independent verification. A human approval step earns no automatic credit merely because someone is nominally involved.
A proposal awaiting its own evaluation
The central limitation is explicit: no independent prospective study has established that R-BED improves decisions or reduces harm. Software checks and reproducible calculations establish much less than that.
Several proposed components are not implemented in the public package described by the paper. Maintaining dependency records could also be costly, incorrect dependency declarations could misdirect reassessment, and many small changes accumulating over time are not modeled.
The paper sets out seven hypotheses for future testing, including reviewer agreement, practical workload and whether consequence-based monitoring outperforms alternatives. For now, its contribution is a structured way to expose what a deployment decision relies on—not proof that following the structure makes a system safe.
- AI evaluation
- AI agents
- deployment controls
- continuous assurance
- risk assessment
- R-BED
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
When AI Safeguards Miss the Same Mistakes
Source published
Shared keywords: ai agents, risk assessment
Can AI assistants use what they know about you to get things done?
Source published
Shared keywords: ai agents, ai evaluation
AI forecasts improve when models know a freelance agent’s limits
Source published
Shared keywords: ai agents, ai evaluation
A CT-labeling system gives an AI reviewer fewer decisions to make
Source published
Shared keywords: ai agents
When AI Agents Change Without Getting Better
Source published
Shared keywords: ai evaluation