TRANSMISSION // 2611.10679v1
Document-parsing leaderboards shift when the scoring rules change
Source published
RankShift compares 16 document-parsing systems and finds that reference formatting and text-matching procedures can substantially reorder their rankings. The preprint argues for reporting ranking robustness alongside headline scores.
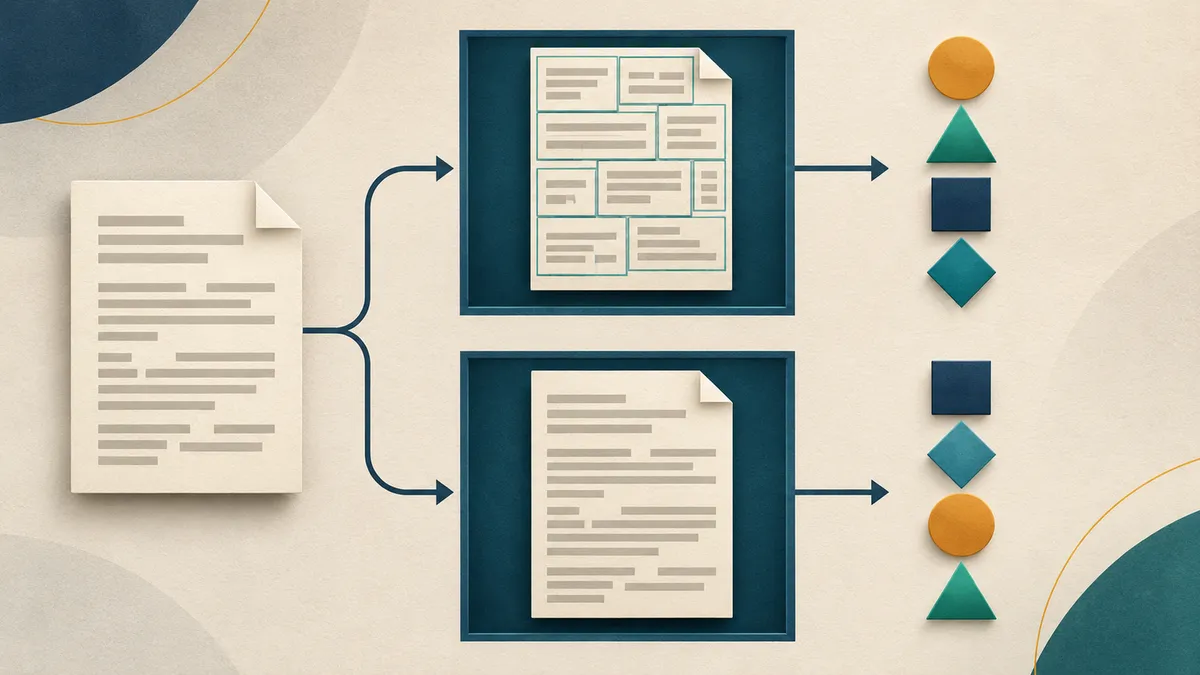
Turning a document image into usable text is only half the challenge. Evaluating that text requires decisions about paragraph boundaries, reference formats and scoring rules—and those decisions can change which system appears best.
A leaderboard offers an appealingly simple answer to a complicated question: which document-parsing system performs best? RankShift, an arXiv preprint by Halimat Afolabi and Daeyoung Lee posted on November 7, 2026, shows how conditional that answer can be. In their experiments, changing how predictions were matched to reference annotations substantially rearranged the standings, without changing the predictions themselves.
The study does not establish that one evaluation procedure is correct and another is wrong. Instead, it examines how much the ordering depends on choices that a headline score can hide.
Same output, different comparisons
Document parsing converts page images into machine-readable content. Evaluating it is difficult because two outputs can contain the same information while dividing paragraphs, arranging blocks or expressing formatting differently.
The researchers tested 16 systems, including specialist document models, a processing pipeline and general-purpose vision-language models. Their main dataset was OmniDocBench v1.5, containing 1,355 bilingual pages across nine document types and five layout types. They also used physically scanned reconstructions of the same pages from Real5-OmniDocBench.
For matching, they crossed three procedures with two reference formats, producing six evaluation conditions. The references were either structured JSON annotations or a Markdown rendering of those annotations. Two procedures matched individual text segments: one allowed adaptive merging and splitting, while the simpler alternative used one-to-one assignment. The third concatenated each page into a single string, avoiding block-level matching.
The main rankings measured text similarity, not the benchmark’s usual composite of text, table and formula scores. That distinction matters: these results are not a complete assessment of every aspect of document parsing.
Reference boundaries can reshape the leaderboard
The researchers measured agreement using Kendall’s tau, a statistic describing how similarly two rankings order the models. A value of one means identical ordering; values near zero indicate little agreement. They also counted reversed model pairs and changes in the top-five set.
Across the four comparisons that switched reference format while retaining segment-level matching on both sides, mean tau was approximately 0.33. The reported average share of reversed model pairs was 31.7%.
The most unstable comparison changed both reference format and segment-matching procedure. It reversed 35.8% of model pairs and replaced three members of the top-five set. Switching only the reference format still mattered: tau was 0.40 with adaptive matching and 0.30 with one-to-one matching.
Whole-page comparison was more stable. When both formats were scored as concatenated strings, tau reached approximately 0.77.
The proposed explanation concerns reference boundaries. Markdown rendering can merge, omit or rewrite annotated blocks, while the JSON-based text evaluation excludes certain categories. Segment matching can therefore pair otherwise correct predicted text with an unsuitable reference block. Concatenation removes that particular pairing step, although it also removes block-level evaluation detail.
Document selection matters too
Rankings also changed across document categories. Mean tau between page-type subsets was approximately 0.48; between layout subsets it was 0.49. For example, dots.ocr ranked first overall under the study’s baseline text evaluation but tenth on academic-literature pages.
Moving from digital pages to scanned versions preserved rankings more closely, with tau of 0.80. That is evidence about relative ordering, not proof that scanning leaves absolute parsing quality unchanged. Some individual movements remained substantial: dots.ocr fell from first to sixth.
The three scoring metrics—normalized edit distance, BLEU and METEOR—produced comparatively consistent rankings, averaging tau of approximately 0.78. These metrics reward different forms of textual similarity. Even here, the winner changed: dots.ocr led under edit distance, while Youtu-Parsing led under BLEU and METEOR.
A robustness check, not a new referee
The findings remain preprint results, with important limits. The controlled alignment study centers on one benchmark, and the physical-capture comparison covers scanning rather than Real5’s other degradation conditions. Some subsets are small, and several reported rank-correlation confidence intervals are broad.
The authors also propose using patterns of disagreement between scoring procedures to flag possible excess content, formatting overhead or mismatched blocks. Those explanations draw on score patterns, text statistics and targeted manual inspection. They have not been validated on a held-out, failure-labelled sample, so they are diagnostic candidates rather than established error detectors.
The practical recommendation is to make evaluation choices visible. Reporting configurations, document-specific results and ranking stability would reveal whether a model’s apparent advantage survives reasonable changes in how it is judged.
- document parsing
- OCR
- AI evaluation
- benchmark robustness
- ranking instability
- OmniDocBench
- RankShift
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
When AI Rebuilds a Document, Looking Right Is Not the Same as Being Right
Source published
Shared keywords: document parsing
Estimating AI Reliability With Fewer Repeated Trials
Source published
Shared keywords: ai evaluation
Expert Feedback Raises Average Ratings for AI Finance Briefs
Source published
Shared keywords: ai evaluation
Could the shape of word connections help evaluate AI reasoning?
Source published
Shared keywords: ai evaluation
Can AI assistants use what they know about you to get things done?
Source published
Shared keywords: ai evaluation