TRANSMISSION // 2611.10657v1
MMGraph-Agent: helping AI search documents and the web without overflowing its working context
Source published
A preprint introduces an AI question-answering system that organizes text and images into searchable groups, keeps compact summaries of retrieved evidence, and uses one trained model for document and web searches. It reports stronger benchmark scores than the tested alternatives, but the evaluation is small and its headline metric measures answer-word overlap, not factual reliability.
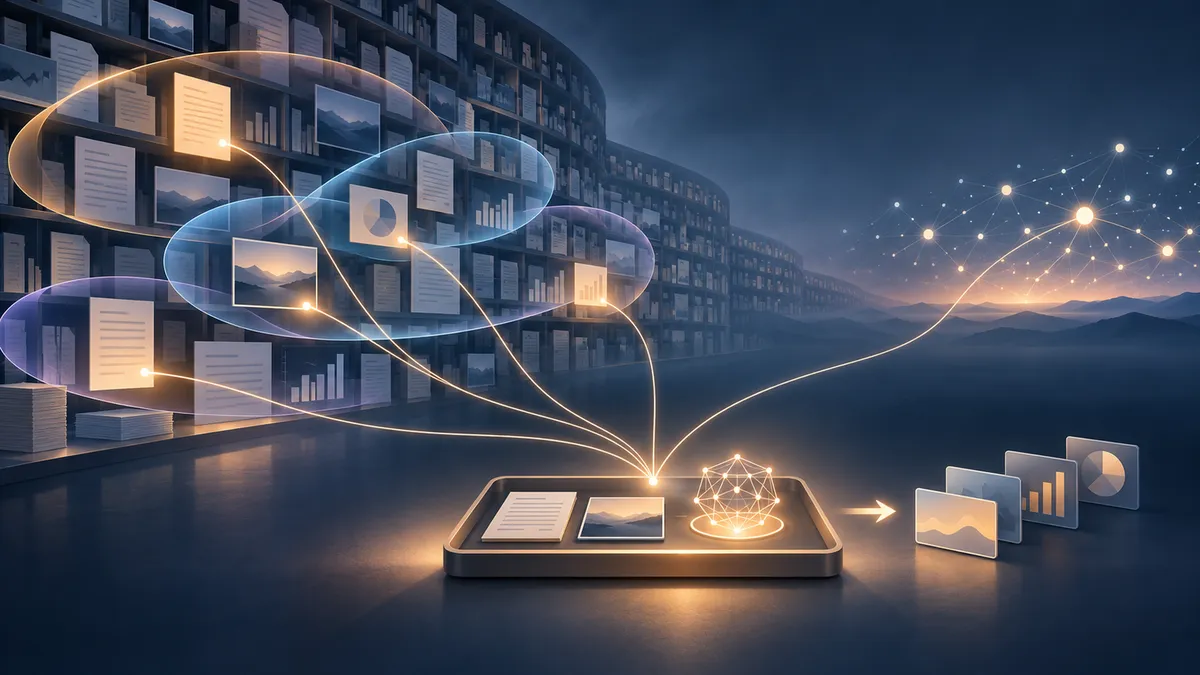
An AI assistant answering questions about a report may need a paragraph, a chart and information from the web. Retrieving everything can overwhelm the space available to the model. MMGraph-Agent tackles this problem by combining a locally built knowledge index with a temporary evidence store and a model trained to choose searches.
How the system organizes evidence
Retrieval-augmented generation, or RAG, lets an AI consult external material before answering rather than relying only on information encoded during training. Multimodal RAG extends this approach to images, tables and diagrams as well as text.
MMGraph-Agent first processes documents locally. The spaCy language-processing software identifies named entities in sentences. Entities appearing in the same sentence become a group called a hyperedge, which retains the sentence as supporting material. Unlike a conventional graph connection linking two items, a hyperedge can connect several at once.
A frozen CLIP model converts entities, sentences and images into numerical representations that support similarity searches. Images are indexed separately alongside the text-derived groups; tables and diagrams enter as flattened text or rendered images. This is not a system that independently verifies every relationship it stores: the text groups are based on sentence co-occurrence.
The authors call construction “zero API cost” because it avoids paid language-model extraction services. That does not mean zero computing, storage or electricity cost. They report a build taking a few CPU hours for a corpus containing about 92,000 text chunks and 74,000 images.
A searchable notebook, not an unlimited prompt
The memory design resembles a large archive paired with a working notebook. The archive retains the indexed corpus. A temporary store collects evidence retrieved during one question-answering session, including web results when enabled.
Each retrieval round searches the backend and selects relevant material from the accumulated evidence. Before evidence enters the model’s conversation, it is truncated and summarized into an approximately 300-word digest. A 5,000-token stopping threshold limits continued accumulation. Tokens are the pieces of text processed by the model.
The cache therefore does not give the model unlimited reading capacity. It keeps more material outside the prompt while admitting compact summaries. The described controller still consults the backend each round, so evidence reuse should not be read as eliminating fresh searches.
The answering model is Qwen2.5-VL-3B. Reinforcement learning trains it to issue text searches, request image searches or answer. Training used 600 examples over 75 update steps on eight A100 GPUs, with web search disabled. The same trained checkpoint was then evaluated with web retrieval enabled, without further parameter updates.
What the experiments found
The evaluation covered 23 datasets spanning document-only retrieval, web-only retrieval and combined retrieval. However, it used a fixed pool of 640 questions, with 16–32 questions sampled per dataset—not the complete benchmarks.
The main table reports the highest mean score for MMGraph-Agent on every dataset. On the financial benchmark FinMME, its token-level F1 was 61.56, compared with 16.63 for the next-best listed baseline. On the long-document benchmark MMLongBench-Doc, the corresponding scores were 20.64 and 11.08. These are F1 scores on a 0–100 scale, not percentages of questions answered correctly.
F1 measures overlap between words in the generated answer and a reference answer. The paper’s medical example makes the distinction concrete: an incorrect diagnosis still receives partial credit because it shares words with the correct diagnosis. Benchmark gains therefore do not establish clinical reliability or faithful reasoning.
In separately collected episodes lasting three to five retrieval rounds, the authors report 67% fewer context tokens and a 3.4-point F1 improvement for the default memory configuration relative to no cache. The default trained policy generally settled on one retrieval per question, so these longer episodes were a separate stress test.
What remains uncertain
Three repeated evaluations used the same question pool with sampled generation. Their standard deviations describe variation between those runs, not uncertainty across new datasets or independently trained models.
Some comparison systems lack access to both document and web retrieval. Also, removing memory simultaneously removes summarization, truncation and the context cap. Those comparisons assess bundled designs rather than isolating caching alone. Entity coverage relative to a language-model extractor was not directly measured.
Web evidence can be wrong or biased, and the raw retrieved pages are not included in the announced release, limiting exact replay. Only one backbone size was tested.
This briefing concerns the supplied arXiv version-one preprint, posted November 7, 2026. Its conference-style formatting does not establish peer-review status. The reported results support further investigation of the architecture, not a guarantee of dependable real-world answers.
- retrieval-augmented generation
- multimodal AI
- knowledge hypergraphs
- AI agents
- evidence memory
- reinforcement learning
- preprint
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Better Context Helps a Smaller AI Answer Questions About Scientific Figures
Source published
Shared keywords: multimodal ai, retrieval augmented generation
Teaching an AI search agent when to look for images
Source published
Shared keywords: multimodal ai, reinforcement learning
AI can read an image yet struggle to reason about it
Source published
Shared keywords: multimodal ai, reinforcement learning
PatternBloom gives search agents a memory of how to connect facts
Source published
Shared keywords: reinforcement learning, retrieval augmented generation
Teaching vision-language AI when a short answer is enough
Source published
Shared keywords: multimodal ai