TRANSMISSION // 2611.10638v1
When fewer missed deadlines is the wrong goal for an AI scheduler
Source published
A preprint benchmark finds that treating every late computing task equally can sacrifice urgent work. Correcting the reward nearly recovers the mathematical optimum—but trained reinforcement-learning agents still fall well short in larger simulated systems.
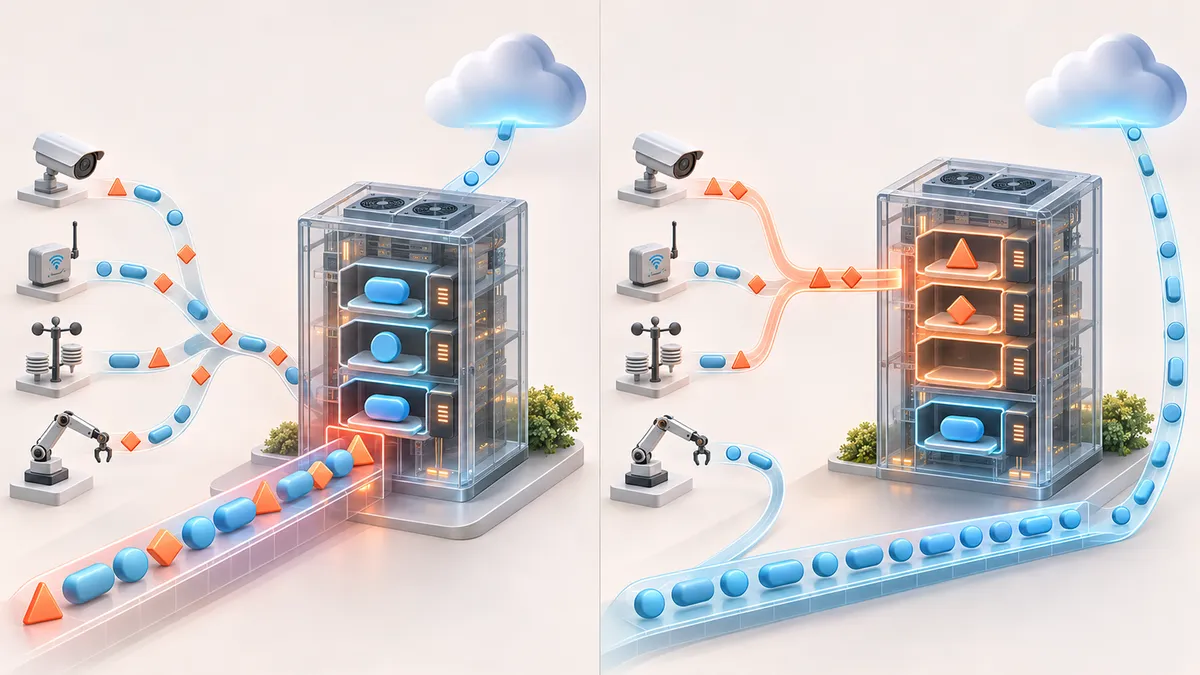
A scheduler can miss fewer deadlines overall while doing a worse job protecting the tasks that matter most. A study of simulated edge-and-cloud computing systems separates two reasons this happens: rewards that encode the wrong priorities, and learning algorithms that fail to achieve even a well-designed objective.
Which deadlines matter?
Internet-connected devices generate computing tasks that can run on nearby edge servers or be sent to the cloud. Choosing where each task runs becomes difficult when queues grow: a task with a relaxed deadline can occupy capacity that a more urgent task will need later.
In a preprint posted on November 7, 2026, Shilpa Golla, Tharun Kumar Korine Palli and Urmila Bandaru examine how reinforcement-learning schedulers handle that competition. Their study introduces no new learning algorithm. Instead, it builds small systems whose best possible scheduling policies can be calculated, exposing shortcomings that comparisons with weaker rules might hide.
The manuscript says it has been submitted to IEEE Transactions on Network and Service Management; the supplied evidence does not establish peer-reviewed acceptance.
A benchmark with a known answer
The researchers constructed four synthetic systems, ranging from two identical edge servers handling two task classes to four different-speed servers handling three classes. Each episode lasted 200 decisions. Queues held at most eight tasks, and background traffic competed for edge capacity. In the larger systems, cloud tasks had a class-dependent chance of meeting their deadlines.
The evaluation metric was a weighted cost of missed deadlines. Missing a critical task counted more heavily than missing a tolerant one. In the smallest system, those weights were 10 and 2.
Using dynamic programming, the team calculated the optimal policy by working backward through possible states and accounting for future consequences. They separately calculated the best policy for each reward design. This distinction isolates two problems: asking a learner to optimize the wrong score, and failing to learn the best behavior for that score.
They trained standard reinforcement-learning algorithms, including proximal policy optimization, or PPO, using ten random seeds for the main comparisons. Most trained policies were evaluated by propagating state probabilities through the exact model, rather than estimating performance from sampled test episodes. That removes evaluation sampling noise, but not variation between training runs.
A success bonus changes the priorities
One reward gave every missed task the same penalty. Another assigned penalties according to task importance. Both also awarded one point for meeting a deadline.
That bonus matters. With a penalty of 10, switching from success to failure changes the reward from plus one to minus ten: an eleven-point loss. A penalty of two produces a three-point loss. The intended importance ratio of five to one therefore becomes eleven to three, weakening the relative protection of critical tasks.
The authors corrected the penalties so that the combined loss—the penalty plus the forfeited bonus—matched the intended priorities proportionally. They retained the same average penalty across classes.
For undiscounted rewards, the best policy under this corrected design stayed within 0.13% of the minimum weighted miss cost across all four systems. A small extra charge for using the cloud explained the remaining discrepancy. By contrast, even a perfect learner of the equal-penalty reward would incur costs approximately 65% to 118% above the optimum.
These are results about reward objectives, not the performance of trained neural networks. They also require qualification: discounting future rewards, as the learners did, introduced additional departures from the undiscounted optimum.
Better rewards did not solve learning
In the smallest system, PPO with importance-weighted penalties finished about 11% above optimal cost; the corrected version finished about 9% above it. Corrected PPO beat a tuned capacity-reservation rule in nine of ten training seeds, although its advantage over ordinary weighted PPO was not statistically significant.
The trade-off was visible in the deadlines themselves. Equal-penalty PPO missed 11.3% of critical tasks and 0.2% of tolerant tasks. Weighted PPO missed 2.9% and 14.4%, respectively. The equal-penalty agent missed fewer tasks overall, but performed worse against the chosen importance-weighted goal.
Larger systems exposed a second limitation. PPO with either per-class reward remained 41% to 76% above optimal cost on average. A tuned rule that restricted which servers each class could use outperformed their means. These rules had access to the true model for tuning, whereas agents learned through simulator rewards.
Tenfold longer training in the largest system did not significantly improve the final results. A constrained PPO variant with achievable miss-rate targets also showed no significant advantage over weighted PPO.
What the result does—and does not—show
These were not deployed networks. The models used linear queue-dependent latency, simplified cloud reliability, exact queue observations, and no energy or transmission model. Exact calculation also scales poorly as servers are added. Algorithm tuning was limited, and longer training was tested in only one system with one configuration.
The evidence therefore supports a narrower lesson than declaring reinforcement learning unsuitable for scheduling: reward design and learning quality must be checked separately. Protecting important tasks requires the right objective, and beating a simple baseline does not establish that a scheduler is close to the best achievable policy.
- reinforcement learning
- edge computing
- cloud computing
- task offloading
- reward design
- dynamic programming
- deadline scheduling
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Reserving resources for AI agents when their workloads are unknown
Source published
Shared keywords: cloud computing, edge computing
AI-designed rewards help a fraud detector learn from blocked payments
Source published
Shared keywords: reinforcement learning, reward design
Can language-model feedback help edge servers share resources?
Source published
Shared keywords: edge computing
Language models help design rewards for two-stage payment fraud detection
Source published
Shared keywords: reinforcement learning
Can a game of hidden loyalties teach AI to spot deception?
Source published
Shared keywords: reinforcement learning