TRANSMISSION // 2611.10600v1
AI agents can group the right documents under the wrong parent
Source published
InfoOrgBench tests whether AI agents can reconstruct folder hierarchies, not merely collect related records. Across 45 model–harness combinations, higher-level relationships proved less reliable than local grouping—but ambiguous inputs and overlapping source material limit what the scores establish.
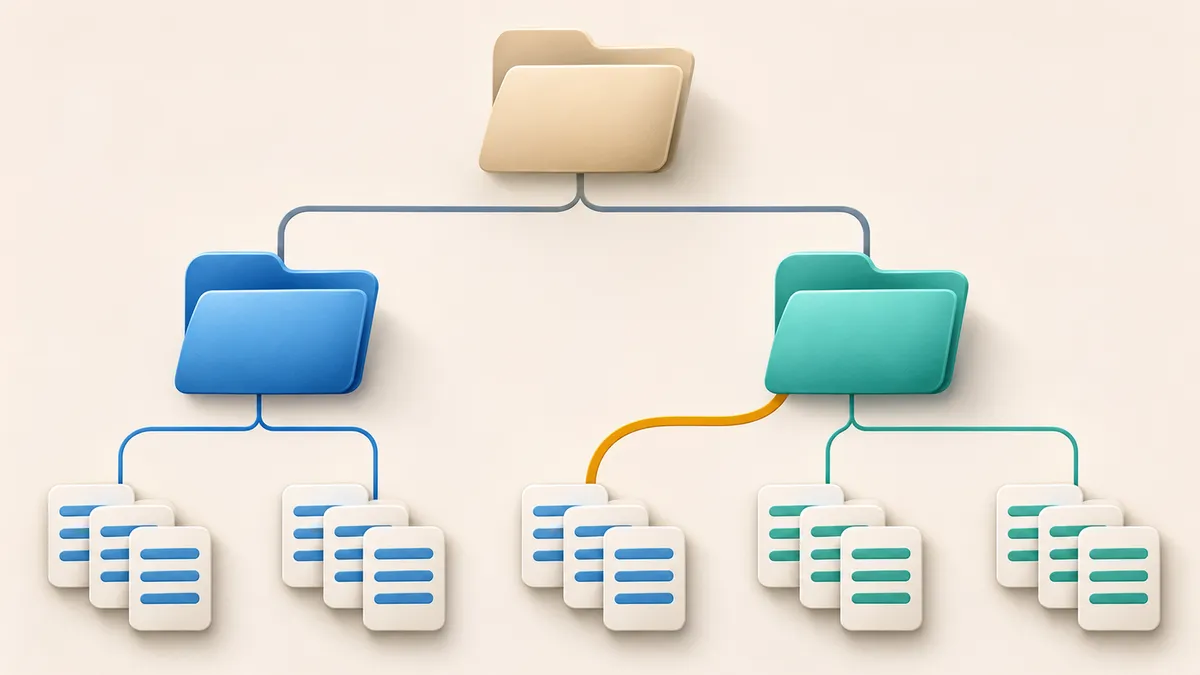
A folder can contain all the right documents and still sit in the wrong place. A new benchmark examines that distinction, finding that AI agents often recover small groups more reliably than the larger structure connecting them.
Imagine an assistant collecting excerpts from a software proposal. It correctly recognizes which passages belong together, preserves every file, and creates a tidy folder. Then it files that proposal under the wrong team. Nothing is missing, but the organization is wrong.
That distinction motivates InfoOrgBench, introduced by Justice Ou, Lanming Ma, Zijian Zhang and Yilun Zhao in an arXiv preprint posted on November 7, 2026. The study separates keeping records intact from reconstructing the relationships between them. Its results are preprint findings, not established conclusions about AI organization in general.
Rebuilding a hidden filing system
The benchmark contains 150 tasks, divided equally among three collections. Meeting-summary sentences must be organized by meeting and then summary section. Issue-tracker records must be grouped by parent issue and then subtask. Kubernetes design-proposal excerpts must be grouped by owning team and then proposal.
Agents receive text files with opaque identifiers and an organizing criterion. They inspect and move those files, while the evaluator retains the source hierarchy. The captured filesystem—not an agent’s claim that it finished—determines the result.
The researchers tested nine models with five agent harnesses: the software layers that provide tools, manage conversation history and control execution. These combinations produced 45 systems, each run once on every task in the main evaluation.
Measuring relationships, not folder names
An integrity check tests whether every record survives exactly once with unchanged content. Separately, a Structure Score measures agreement with the source hierarchy, ignoring folder names and sibling order.
Its basic comparison uses three records. If two share a deeper folder than either shares with the third, the hierarchy expresses a closer relationship between that pair. The evaluator checks whether the agent reproduces those relationships, balancing the parent and lower levels so that one does not dominate merely because it contributes more comparisons. It also penalizes excess folders with only one child.
This produces graded credit, but the score is not the percentage of tasks completed perfectly. Nor does 100 necessarily mean an identical hierarchy: additional subdivisions can preserve the relationships the metric measures. The paper therefore also examines complete-group recovery in selected runs.
The larger structure was harder
The highest overall Structure Score was 83.2 out of 100, achieved by GPT-6.1 Sol with DeepSeek Harness. The best scores differed sharply by collection: 77.8 for meeting recaps, 77.9 for issue threads and 95.8 for design proposals.
Across the configurations with detailed level-by-level data, parent relationships had higher error rates than lower-level relationships in all three collections. The mistakes took different forms.
For meeting summaries, agents often grouped notes by topic rather than by their original meeting. In the analysis, 54% of output folders mixed notes from different meetings. For issue threads, half of the analyzed outputs omitted the parent-issue layer, placing subtasks directly into top-level folders.
Design proposals showed the opening example particularly clearly. Of 1,250 outputs examined by level, 596 had owning-team errors without proposal-level relationship errors. The excerpts could be grouped correctly while the proposal groups were attached incorrectly above them.
Complete reconstruction was also rarer than the headline scores might suggest. In an additional analysis using the ReAct-FC harness, GPT-6.1 Sol exactly recovered one of 50 meeting hierarchies and two of 50 issue-thread hierarchies.
Model differences outweighed average harness effects
Mean scores across models spanned 27.2 points. By comparison, each harness’s average effect across models ranged from −0.7 to +0.6 points. That does not make harnesses interchangeable: their tools and history policies differed, and some individual models showed larger gaps.
Repeated runs also complicate small rankings. Three identical runs of GPT-5.6 Terra with Codex differed by at most 0.4 points in their overall means, but individual task scores changed by 5.9 points on average between runs. For that system, higher reasoning effort and two methods of combining three runs did not establish a meaningful average improvement. This is not evidence that extra computation never helps.
Some answers were not recoverable from the text
The benchmark’s target is the original source organization, not necessarily the most useful arrangement for a reader. Some inputs also lack decisive placement evidence. Twenty-two issue-thread tasks contained identical text assigned to different subtasks; content alone cannot distinguish those assignments. Design excerpts did not name their owning teams.
The tasks reuse source material, all issue-thread tasks draw from just three parent issues, and there is no source-disjoint held-out split. Possible exposure to public records during model training was not measured. Access conditions also differed: Codex could read outside the task root, and those reads were not audited.
The supported conclusion is narrower than a general verdict on automated filing: preserving files and recognizing local groups do not demonstrate that an agent has recovered the hierarchy connecting them.
- artificial intelligence
- AI agents
- InfoOrgBench
- information organization
- hierarchical clustering
- benchmark evaluation
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
DualWorldBench tests whether AI agents can turn delivery goals into workable plans
Source published
Shared keywords: ai agents, benchmark evaluation
AI design benchmark separates finished runs from verified delivery
Source published
Shared keywords: ai agents, benchmark evaluation
What an AI loses when it forgets the conversation
Source published
Shared keywords: ai agents, benchmark evaluation
A billion-star search maps the Milky Way’s nested structures
Source published
Shared keywords: hierarchical clustering
When AI agents change, should their permissions change too?
Source published
Shared keywords: ai agents, artificial intelligence