TRANSMISSION // 2611.10521v1
TimeHF 2.0 brings business plans into retail sales forecasts
Source published
A JD-led preprint combines regional sales histories, structured conditions and written business knowledge to forecast retail sales. Industrial comparisons report improved daily and planning-window accuracy, but do not establish inventory savings or the causal effects of promotions.
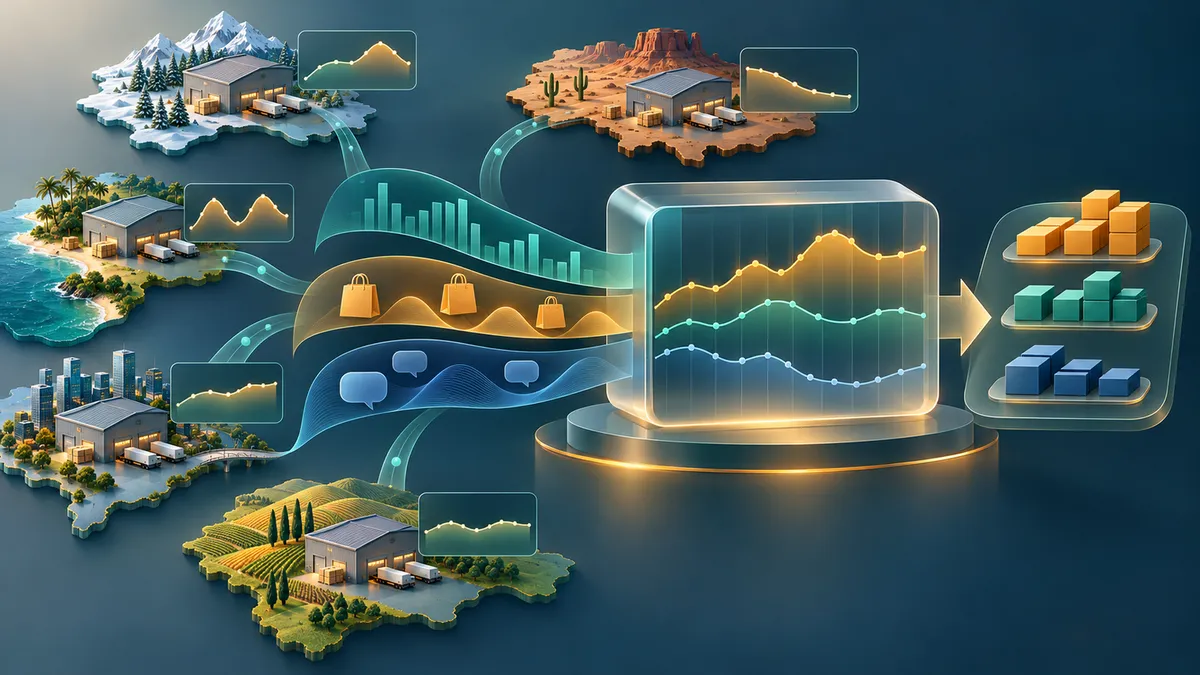
A sales history cannot tell a forecasting system that next week’s promotion has moved. TimeHF 2.0 lets written plans and business experience influence numerical predictions alongside regional sales records, while testing whether those additions improve forecasts.
What a sales history misses
How should a retailer forecast a product whose recent sales look flat, but which is about to enter a back-to-school campaign? Historical patterns supply part of the answer. Plans known to the business may supply another.
TimeHF 2.0, described in a JD-led technical report posted as an arXiv preprint, combines those sources. It predicts daily sales for individual products nationally and at distribution centers, then adds daily predictions into planning-window totals. These quantities support different decisions: national procurement, local inventory placement and replenishment.
The report presents company-run forecasting comparisons, not peer-reviewed confirmation or a trial demonstrating better inventory outcomes.
Connecting numbers, regions and words
The numerical model processes sales histories together with additional variables, called covariates. These include campaign schedules, weather forecasts and historical page views. Inputs must reflect what was available when a forecast was made: an already-issued weather forecast is allowed, but future observed weather is not. Missing records are distinguished from genuine zero sales.
Regional information sharing is selective. A distribution center with little local history can draw on national or peer-center sales, but the model weighs the relevance of those references using their observations and service areas. A rising national trend need not imply rising demand everywhere. National predictions are not forced to equal the sum of distribution-center predictions.
The language component handles descriptions of plans and business experience. A language model converts these into internal numerical representations. A trainable alignment module connects those representations with the target product’s numerical history, applying descriptions to their specified regions and future dates.
For example, moving a promotion to a later week can change the forecast without changing the sales history or retraining a separate model. The response is learned from sales supervision; a user’s expectation remains an input belief, not a future observation.
The decoder also uses a mixture of experts: shared neural processing plus a small selection of specialized processing modules chosen for the current context. These experts are learned transformations, not explicitly assigned roles such as “holiday specialist.”
Learning totals without chasing every spike
An isolated bulk order can produce a large sales peak without a corresponding campaign or weather signal. TimeHF 2.0 predicts probabilities over ordered sales ranges, with finer resolution around routine variation and coarser resolution at extremes. This reduces the need to reproduce every extreme amplitude exactly, while retaining high-sales observations in training.
Additional penalties constrain daily numerical predictions and accumulated sales over planning windows. The distinction matters: a forecast can get a period’s total roughly right while placing sales on the wrong days, or make small daily errors that accumulate into a poor replenishment estimate.
What the evaluation found
The authors evaluated 200,000 products during January–September 2026, using training data comprising 912 billion data points sampled from 2023–2025 retail records. Models were compared on matched product, region and forecast-origin records. The evaluated system paired a 380-million-parameter numerical backbone with a 0.8-billion-parameter language model.
Against the original production deep-learning baseline, reported relative accuracy improvements were:
- National daily sales: 18.25%.
- National planning-window sales: 17.94%.
- Distribution-center daily sales: 19.44%.
- Distribution-center planning-window sales: 18.99%.
Here, accuracy means one minus total absolute prediction error divided by total actual sales. The percentages describe relative increases in that score—not percentage-point gains or equivalent reductions in forecasting error. Absolute baseline scores are not supplied in the result tables.
Removing individual components weakened performance. Without text conditioning, distribution-center improvements fell to 18.02% daily and 17.65% over planning windows. Removing structured covariates, regional sharing or window supervision also reduced the reported gains. These comparisons support complementary contributions, rather than attributing the complete improvement to language alone.
Where the evidence stops
The report does not provide confidence intervals or repeated-run variability for these headline results. Its evaluation concerns one retailer, and fuller details of the language-model family are deferred to another report.
Sales can also be constrained by available stock, so recorded sales do not necessarily reveal unmet demand. Case studies retain missed peaks and timing errors. Finite sales-bin representatives limit the point forecasts possible for a given historical scale; text cannot remove that bound.
Finally, changing a forecast after editing a campaign note does not establish what executing that campaign would cause. The reported advance is improved conditional sales prediction. Faithful explanatory output remains a proposed future direction, not a demonstrated capability of this system.
- retail forecasting
- TimeHF 2.0
- supply chains
- language-conditioned forecasting
- regional collaboration
- mixture of experts
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Can customer reviews change which inventory deserves attention?
Source published
Shared keywords: supply chains
Changing lithium ownership may not secure supply, model suggests
Source published
Shared keywords: supply chains
AlterNet tests whether language models can learn when to stop computing
Source published
Shared keywords: mixture of experts
AdaOffload adapts CPU and GPU workloads to run large AI models
Source published
Shared keywords: mixture of experts
Telling Stable Diffusion’s close relatives apart
Source published
Shared keywords: mixture of experts