TRANSMISSION // 2611.10501v1
What would make an AI agent genuinely curious?
Source published
A position preprint proposes five requirements for computational curiosity: predicting environmental responses, learning from interaction, choosing informative actions, retaining improvements and, for open-ended inquiry, choosing what to investigate. It offers an architectural framework and proposed tests, not new experimental results.
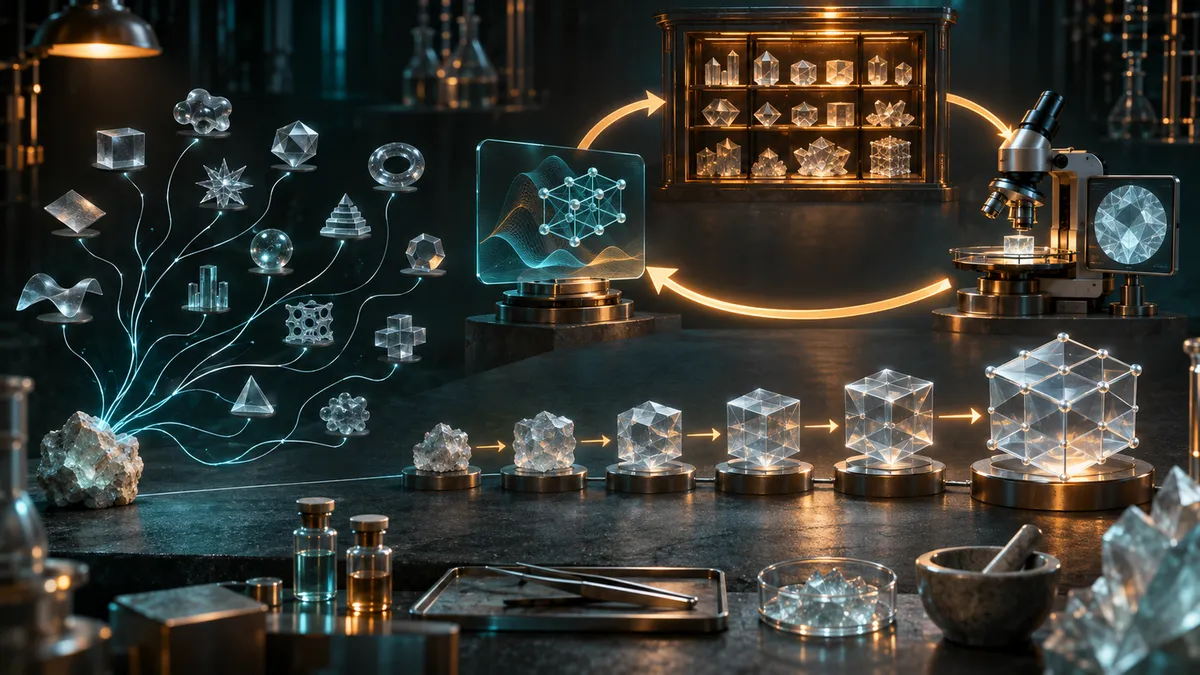
An AI agent can generate a hundred hypotheses without knowing which experiment would teach it the most. A new position paper argues that this distinction separates varied output from computational curiosity.
An AI agent tries different solutions, searches documents and runs experiments. Is it curious, or simply exploring a range of possibilities? In Sampling Is Not Curiosity: Why LLM Agents Should Investigate, Alfonso Amayuelas and colleagues argue that the difference lies in whether learning actively guides the next investigation.
This is a position preprint, not a report of a newly tested agent. Its contribution is a proposed definition, an analysis of existing system designs and a set of possible tests. Its claims about what should count as curiosity are an argued framework rather than an experimentally settled classification of all AI agents.
Variety is not the same as inquiry
During ordinary inference, a language model's trained weights remain fixed. Its answers can nevertheless change as it receives observations or retrieves information. Temperature settings alter how tokens are sampled; search methods compare alternative reasoning paths; retrieval supplies additional context.
These mechanisms can be useful. But, the authors argue, they do not by themselves establish that an agent maintains an improving predictive model of its environment and chooses actions because of what it expects to learn.
The distinction comes from research on reinforcement learning, where agents learn through actions and feedback. An intrinsic reward is a signal for pursuing something such as learning, rather than only completing an externally assigned task. Rewarding surprise alone can go wrong: unpredictable noise can remain endlessly surprising without becoming understandable. Rewarding learning progress instead asks whether predictions are actually improving.
Five commitments
The paper translates that tradition into four requirements for task-directed curiosity, plus a fifth for open-ended inquiry:
- Predict environmental responses. The agent needs predictions about what its actions will reveal or cause, not merely a measure of how unusual its own generated text is.
- Update from current interaction. Observations during the investigation must improve those predictions. Previously acquired knowledge alone does not demonstrate this.
- Act to learn. Expected predictive improvement must influence which action comes next. Learning incidentally while pursuing a task is not enough.
- Retain the improvement. What was learned must remain available for later decisions beyond the context window that originally contained the observations.
- Choose what to investigate. For open-ended curiosity, the agent must originate its prediction targets rather than only explore a human-specified problem.
Consider the paper's example of investigating a material. One agent generates diverse hypotheses and tests them in arbitrary order. Another maintains competing hypotheses, predicts their experimental consequences, chooses an informative experiment and revises its beliefs afterward. Only the second closes the proposed prediction–action–learning loop.
Importantly, this need not require changing the language model's weights. The predictive component could consist of revisable natural-language hypotheses, structured data or another persistent representation.
What the analysis finds
The authors examine published architectural descriptions rather than conducting a new benchmark comparison. Under their criteria, bonuses based on generated-text novelty target the wrong object: output diversity rather than environmental understanding. Stored reflections or skill libraries can improve task performance without making expected learning determine the next action.
They also distinguish autonomous work inside a human-defined search space from choosing the search space itself. Generating subgoals does not automatically meet their stronger requirement for open-ended curiosity.
The paper identifies partial architectural precedents. It presents WorldLLM as an example meeting the four task-directed commitments through updated hypotheses without weight changes. It discusses SENSEI's learned world model and AutoDiscovery's hypothesis search as other ways to connect investigation with learning. These are interpretations of earlier work, not newly reproduced performance results. The authors argue that satisfying all five commitments together remains unresolved.
How could the claim be tested?
The proposed tests ask an agent to predict outcomes before acting, measure whether controlled observations improve predictions, and check whether informative actions are preferred when their task value is otherwise similar. Removing the intrinsic learning signal should remove that preference. A context reset should preserve predictive gains when persistent state survives, but not when that state is also erased.
These tests are proposals, not reported experimental findings. Recognizing predictive learning hidden inside a system remains difficult. The authors explicitly caution that, for such systems, curiosity may be undemonstrated, rather than absent.
They also acknowledge that in-context learning can improve predictions from current observations. Their objection is that this alone does not establish learning-directed action selection or durable retention. The practical question is therefore not whether an agent sounds inquisitive, but whether evidence changes what it predicts, what it investigates next and what it carries forward.
- AI agents
- computational curiosity
- intrinsic motivation
- reinforcement learning
- world models
- in-context learning
- open-ended discovery
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
An AI maze navigator remembers by updating its world model
Source published
Shared keywords: world models
WorldMind tests spatial reasoning without turning every imagined view into an image
Source published
Shared keywords: reinforcement learning, world models
When an AI Queries a Database, How Does It Know What You Mean?
Source published
Shared keywords: reinforcement learning
Can a Small Selector Learn Which Examples Help a Language Model?
Source published
Shared keywords: in context learning
Training AI agents to learn from different execution guides
Source published
Shared keywords: ai agents, reinforcement learning