TRANSMISSION // 2611.10477v1
PatternBloom gives search agents a memory of how to connect facts
Source published
An arXiv version of a paper reported as accepted at NeurIPS 2026 describes an AI system that retrieves reusable reasoning patterns alongside evidence. Benchmark gains are promising, but inconsistent headline comparisons and Wikipedia-only testing limit the conclusions.
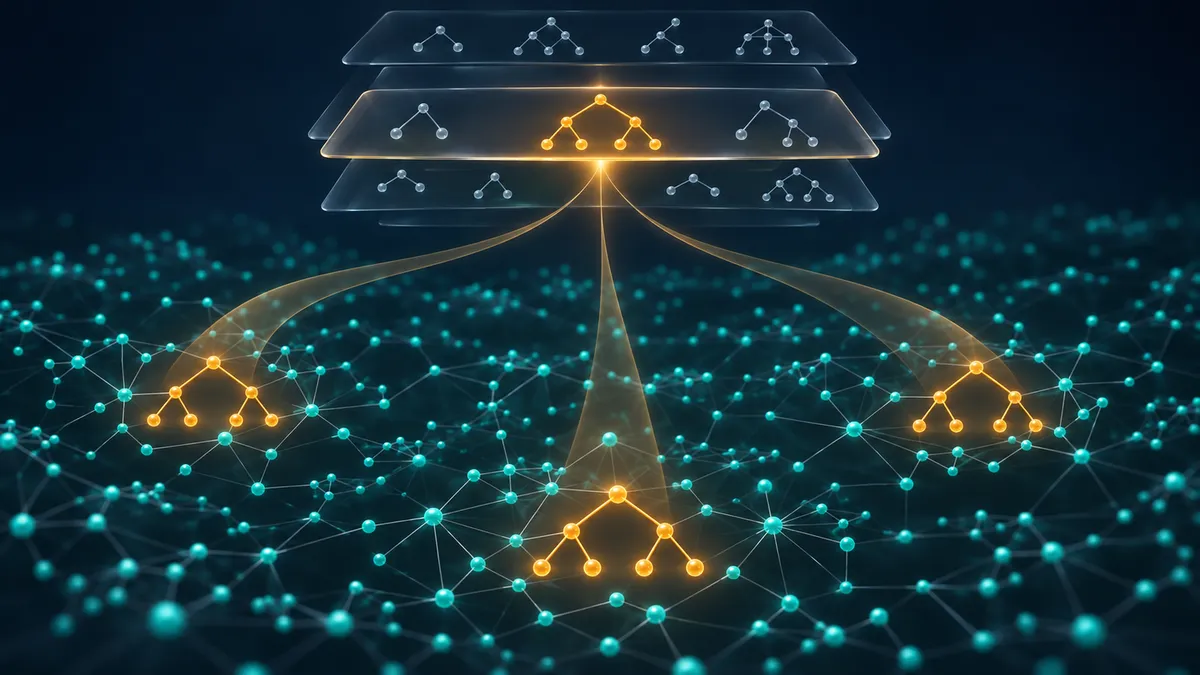
Finding the right facts is not the same as knowing how to connect them. PatternBloom tests whether an AI search agent can improve by storing successful reasoning structures and retrieving them for new questions.
An AI answering a question about a film director’s nationality needs more than a relevant passage. It must identify the film, find its director, then establish that person’s nationality. Different questions can require the same sequence of operations, even when every name changes. Could an agent save that structure instead of reconstructing it each time?
In the arXiv version of their PatternBloom paper, reported as accepted at NeurIPS 2026, Yi Ge and Heng Huang propose an external memory of reusable graph patterns. Their experiments suggest that combining this memory with reinforcement learning improves question answering. However, some broad claims exceed what the reported comparisons clearly establish.
Saving a procedure, not just a fact
Retrieval-augmented generation, or RAG, gives a language model access to external evidence. PatternBloom still retrieves factual material: it searches a Wikipedia-derived hypergraph, which groups related entities and facts from the same passage. Its additional retrieval target is a small structural template describing how relationships can connect.
A conceptual example is film → director → nationality. Such a template does not supply the answer; the agent must retrieve evidence to fill its slots. It instead suggests which relationships to investigate and in what sequence.
The implementation is less finely typed than the paper’s film-and-person illustrations might imply. Its main experiments use coarse categories such as entity, year, number and Boolean value. Almost all stored node occurrences fall into the generic entity category. The reusable structure therefore depends substantially on relationship names and question categories, rather than detailed semantic types.
Two training stages
First, the agent learns to assemble useful evidence graphs. A separate, frozen language model scores how much the graph increases the probability of the known correct answer compared with receiving no evidence. The system divides that improvement by graph size and converts it into a bounded reward. The intention is to encourage compact, informative evidence rather than a pile of loosely relevant facts.
This score is a model-based proxy for evidence quality, not an independent check that every fact is true.
The researchers then extract patterns from high-scoring training trajectories, abstract away specific entities and merge similar entries. The resulting memory contains 27 patterns derived from 14,000 training questions.
In the second stage, the agent receives rewards combining answer-token overlap with coverage of a retrieved pattern. At the default setting, these contribute 80% and 20%, respectively. This encourages the agent to use the memory rather than merely receive it as optional advice.
During deployment, the memory stays fixed. The agent retrieves up to three matching patterns as hints, searches for evidence and generates an answer. Neither the training-time scoring model nor further learning is required.
What the benchmarks show
Training used HotpotQA and 2WikiMultiHopQA. Evaluation covered those datasets plus five held-out benchmarks, using 1,000 questions per dataset except Bamboogle, which contributed its full 125 questions.
The principal seven-billion-parameter model achieved 49.0% average exact match across the five held-out datasets. Exact match measures whether an answer matches a reference after normalization. R1-Searcher scored 34.0%, giving the advertised 15-percentage-point advantage over that particular comparator. However, Search-R1 scored 38.1%, making the margin over that stronger seven-billion-parameter comparator 10.9 points. The 15-point headline should not be read as the lead over the strongest baseline overall.
Component-removal experiments support a contribution from the memory and training scheme. Across four multi-step benchmarks, average answer-token F1 fell from 55.9 to 46.6 without the pattern memory, and to 44.1 without the second-stage pattern-coverage reward.
Harder questions remained difficult. In the reported MuSiQue depth breakdown, PatternBloom’s exact match declined from 52.6% for two supporting facts to 17.4% for five or more. Its relative advantage persisted, but the absolute percentage-point lead over R1-Searcher narrowed rather than increased.
What remains uncertain
All experiments used a fixed Wikipedia-based retrieval substrate. Held-out datasets therefore test transfer between question collections, not demonstrated transfer into medicine, law or finance. The paper reports fixed-seed experiments without error bars, and its human evaluation covers only 30 questions.
Some narrative claims also conflict with the tables: the seven-billion-parameter model does not lead every dataset, despite a statement that it does. Reported failure modes include ambiguous entity names, arithmetic mistakes, inconsistent relationship wording and questions without a matching stored pattern.
The reported conference acceptance does not resolve these methodological limitations. The work’s useful contribution is a testable design: make recurring search procedures explicit, retrievable and trainable. The evidence supports further investigation, not a general solution to reliable reasoning.
- PatternBloom
- retrieval-augmented generation
- reinforcement learning
- graph pattern memory
- multi-hop question answering
- procedural memory
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
ArcRAG Tests Whether AI Can Search Differently Built Knowledge Graphs
Source published
Shared keywords: multi hop question answering, retrieval augmented generation
FondueQA tests how AI fills gaps in retrieved evidence
Source published
Shared keywords: multi hop question answering, retrieval augmented generation
Wiki-style memory helps AI agents repeat workplace tasks in preprint study
Source published
Shared keywords: procedural memory
When an AI Queries a Database, How Does It Know What You Mean?
Source published
Shared keywords: reinforcement learning
GraphRail checks the evidence behind search agents’ reasoning
Source published
Shared keywords: multi hop question answering