TRANSMISSION // 2611.10441v2
How separate image generators can make coordinated outputs
Source published
Split and Bridge (SnB) connects pretrained diffusion models during generation rather than training a single joint model. It shares part of a generation path, then branches into modality-specific paths linked by a bridge. Tests on image-and-mask benchmarks and other tasks show promising results, but performance varies with bridge design, split timing and starting modality. The MRI demonstrations are not clinical validation, and the work should be read as a preprint.
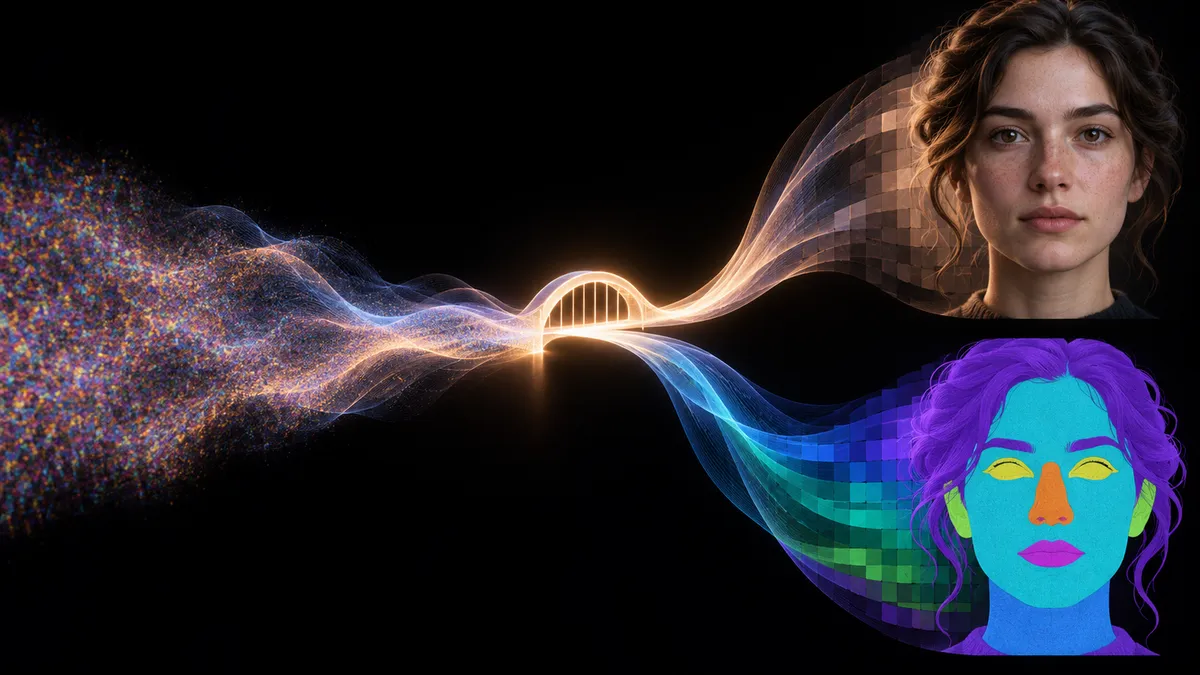
A face and its segmentation mask describe the same person in very different ways: one is a detailed image, the other maps regions such as hair and skin. Can separate image generators be coordinated to create related outputs without retraining them together? A paper called **Split and Bridge** proposes sharing part of their diffusion process, then steering each generator toward its own kind of output.
Diffusion models generate images by gradually turning noise into a coherent sample. For multiple related outputs—a face and a segmentation mask, for example—the challenge is to make them agree on shared features while preserving what is specific to each format. Many existing approaches train a joint model around a shared internal representation. The authors argue that this top-down strategy can be difficult to scale to complex, high-resolution visual data and can limit flexibility through its shared-latent design.
The proposed alternative, Split and Bridge (SnB), combines separate pretrained diffusion models during generation. It starts with one shared reverse-diffusion trajectory: a developing noisy state is used as a common starting point. At a chosen split point, the process branches. Each modality then follows its own generator, while a bridge helps make the intermediate state suitable for the second model.
The bridge can be simple or learned. An identity bridge passes the intermediate state along while the process switches to a different model, prompt or model adaptation. For modalities that differ more substantially, such as faces and segmentation masks, the authors introduce a trainable bridge network. They also add noise to the bridge’s output so it better matches the noisy state expected by the diffusion process. In everyday terms, SnB aims to share enough of the generative journey to establish common structure, then let specialized generators fill in their own details.
The researchers tested SnB on PolyMNIST, a dataset of digit images with different backgrounds, and CelebAMask-HQ, which pairs faces with segmentation masks. They also explored image co-generation and editing using PIE-Bench++, style combinations using model adaptations, and MRI synthesis using a subset of the ROCO radiology dataset. Evaluations included measures of image quality and measures intended to assess whether paired outputs corresponded. For face-and-mask generation, the authors created a learned coherence measure based on how close the two outputs’ representations were in a shared embedding space.
The paper reports that SnB can produce related outputs while maintaining image quality, though results differ by task and configuration. On PolyMNIST, an identity bridge was sufficient for this relatively simple setting. On CelebAMask-HQ, the learned bridge helped coordinate faces and masks; the reported results vary with the point at which trajectories split. Sharing more of the trajectory generally increased coherence over part of the tested range, but a split that leaves too little denoising time can make it harder to move into the second modality. The authors also find that bridge design and capacity affect outcomes.
Results for co-generation are not uniformly better across every measure. In experiments comparing SnB with independent generation and shared-noise baselines, image-quality and text-alignment scores were broadly comparable, while some consistency measures favored SnB and others did not. For MRI synthesis, the reported comparisons show similar image-quality and text-alignment scores across methods, while SnB had stronger results on the listed measures of consistency in the tested settings. These findings support the method’s potential on the selected tasks, not a general guarantee of improvement.
The paper’s own examples show limits: some generated faces do not fully match their conditioning masks, with accessories, hairstyles or expressions missing or changed. The authors note that performance can depend on which modality starts the trajectory, the split point and the bridge design, so these settings may need empirical tuning. SnB also assumes suitable pretrained models are available for each modality, which can be costly or impractical in some settings.
The MRI demonstrations require particular caution. They show synthesis on a curated ROCO subset, not diagnostic accuracy or clinical usefulness. The authors say that clinical metrics and expert assessment are needed before real-world deployment. More broadly, benchmark scores and a learned coherence measure describe performance on selected tests; they do not establish that generated pairs are correct in every relevant sense.
The source is an arXiv preprint and includes a NeurIPS 2026 heading, but the supplied evidence does not establish that the work was accepted or presented at the conference. Preprints may not have undergone peer review, so the results should be interpreted accordingly. SnB’s central idea is compositional: reuse specialized generators and coordinate them during sampling. Whether this approach remains robust across more modalities and independent evaluations is still an open question.
- diffusion models
- multimodal generation
- image synthesis
- generative AI
- medical imaging
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Using generated ultrasound images to choose real ones worth labeling
Source published
Shared keywords: diffusion models, medical imaging
Can one credit balance bring different AI tools together?
Source published
Shared keywords: generative ai
Can one medical-image detector learn across X-rays and mammograms?
Source published
Shared keywords: medical imaging
EvoML checks machine-learning workflows in stages and saves successful fixes
Source published
Shared keywords: medical imaging
Medical image AI faces a cross-site test
Source published
Shared keywords: medical imaging