TRANSMISSION // 2611.10360v1
MambaLoc trains Wi-Fi indoor positioning with ultra-wideband guidance
Source published
MambaLoc uses ultra-wideband measurements during training to guide a lightweight Wi-Fi positioning model. On the OPERAnet dataset, the authors report a median localization error of 0.230 metres, with lower computational cost and latency than their Transformer baseline.
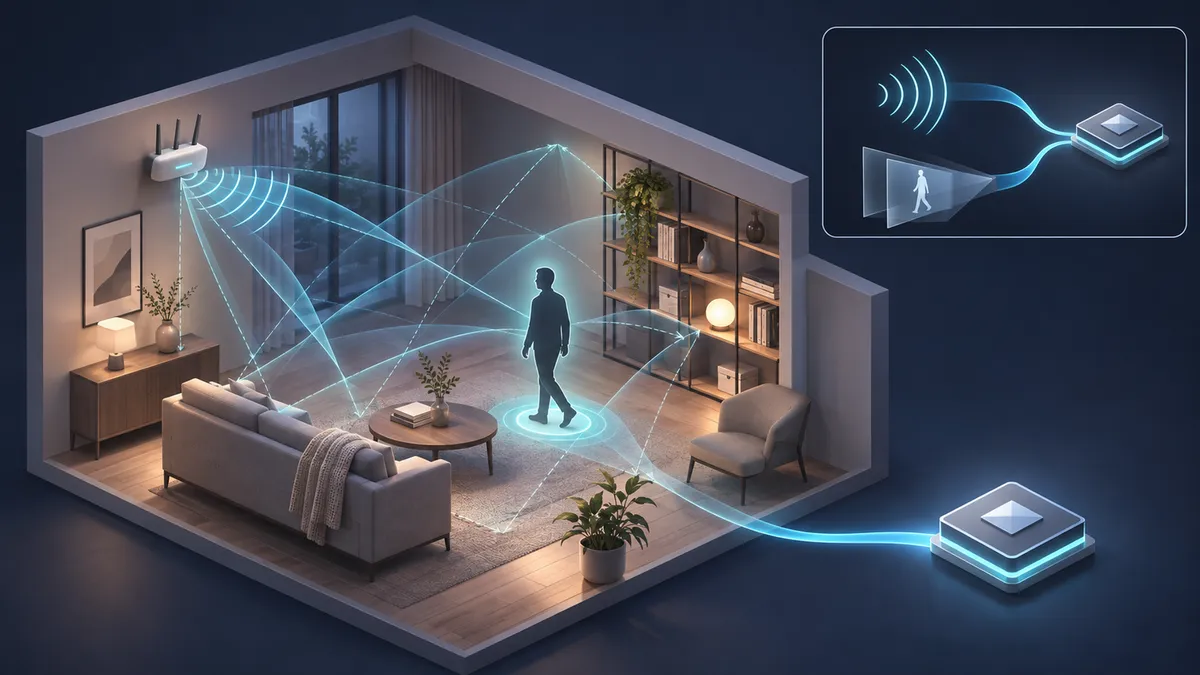
Can a Wi-Fi positioning system benefit from a more precise sensing technology without needing that technology when it runs? MambaLoc explores this approach by transferring information from an ultra-wideband model to a smaller model that estimates indoor positions from Wi-Fi signals alone.
The positioning problem
Indoor radio signals reach receivers along multiple paths, including reflections and diffraction around obstacles. This multipath propagation complicates the relationship between a measured signal and a location.
Wi-Fi Channel State Information, or CSI, records fine-grained amplitude and phase measurements across parts of a wireless channel called subcarriers. These measurements contain spatial information, but extracting it reliably requires dealing with multipath distortion. Ultra-wideband, or UWB, offers precise ranging but requires dedicated infrastructure.
Mohab Bahnassy, Omar Saqr, Hamada Rizk and Moustafa Youssef propose MambaLoc to combine these technologies during training while retaining only Wi-Fi inputs during operation. The supplied metadata lists the work in the proceedings of the 2026 IEEE International Conference on Mobile Data Management; an arXiv version was submitted on November 7, 2026.
Different sensors for training and operation
MambaLoc uses cross-modal knowledge distillation: a model trained with one kind of sensor data guides another model that uses different inputs.
The teacher is a Transformer trained on UWB channel impulse responses, which describe how a radio channel responds over time. The student uses Mamba, a selective state-space model, to process Wi-Fi CSI sequences. Mamba updates an internal state as inputs arrive, with sequence-processing cost that grows linearly with sequence length. The paper contrasts this with the quadratic scaling of standard Transformer self-attention.
A Feature Alignment Module projects the teacher’s and student’s internal representations into a shared space. Its training objectives encourage agreement between those representations, including attention-based matching of relevant features. This transfers more information than matching final position estimates alone.
Training proceeds in three stages: teacher training, an initial alignment stage with both model backbones frozen, and student training combining coordinate supervision, feature alignment and distillation. The relative influence of these objectives changes during training. Afterward, the teacher and UWB components are discarded; localization uses only the CSI student.
Representing spatial ambiguity
Both models use a Gaussian mixture output head with 16 components. This represents a distribution using several Gaussian components rather than producing coordinates through a conventional deterministic regression head.
An important implementation detail qualifies the paper’s broader language about avoiding implausible averages. The reported coordinate estimate is still the mixture’s expected value—a weighted average of component means—and training minimizes its squared distance from the ground-truth position. Component covariance is fixed rather than learned. Distillation matches the teacher’s and student’s mixture weights, not their complete Gaussian distributions.
The authors report that replacing this head with deterministic regression made the distilled student perform worse than the standalone CSI-Mamba baseline. That supports its usefulness in their training setup without establishing that the final estimate cannot average between possible locations.
What the experiments found
The evaluation uses OPERAnet, a dataset with synchronized CSI, UWB measurements and ground-truth positions. It covers approximately eight hours in two furnished indoor environments, including walking, sitting, standing and other daily activities.
MambaLoc achieved a reported median localization error of 0.230 metres. The corresponding results were 0.318 metres for DeepFi, 0.240 metres for AARES-CNN and 0.238 metres for the Transformer-based TIPS system. The authors retrained these baselines on OPERAnet.
A standalone CSI-Mamba model achieved 0.2957 metres. The authors report a 22.2% error reduction with MambaLoc. Intermediate experiments using same-modality and cross-architecture teachers also improved on the standalone student, with the UWB-Transformer teacher producing the lowest reported error.
For efficiency, MambaLoc required approximately 0.39 billion floating-point operations per forward pass, compared with 1.12 billion for TIPS. Reported inference latency was 6.94 milliseconds versus 16.55 milliseconds. The paper reports reductions of 65.1% in operations and 58% in latency relative to TIPS.
The scope of the evidence
These latency measurements used single-sample inference on an NVIDIA GeForce GTX 1650 GPU. They establish the comparison on that hardware, rather than measured performance across resource-constrained devices generally.
Cross-building evaluation and adaptation to different environments remain future work identified by the authors. Extensions to activity recognition, environmental mapping and additional sensors are proposals, not demonstrated results. The present finding is narrower: on this dataset, UWB-guided training improved a Wi-Fi-only student’s localization accuracy while retaining lower inference cost than the tested Transformer baseline.
- indoor localization
- Wi-Fi CSI
- ultra-wideband
- Mamba
- knowledge distillation
- edge AI
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Can a Small Selector Learn Which Examples Help a Language Model?
Source published
Shared keywords: knowledge distillation
Teaching diffusion models to do more with fewer decoding steps
Source published
Shared keywords: knowledge distillation
AI agents may not need every reasoning trace their teachers produce
Source published
Shared keywords: knowledge distillation
IDSISA proposes a more selective approach to AI forgetting
Source published
Shared keywords: knowledge distillation
Compressing Small Language Models: When Combining Techniques Helps—and When It Fails
Source published
Shared keywords: knowledge distillation