TRANSMISSION // 2611.10351v1
Can a quantum reservoir forecast turbulent flow on a real mesh?
Source published
A 52-qubit quantum reservoir helped forecast simulated fluid and chemical patterns, but the result is a proof of predictive value—not evidence that quantum hardware beats classical solvers.
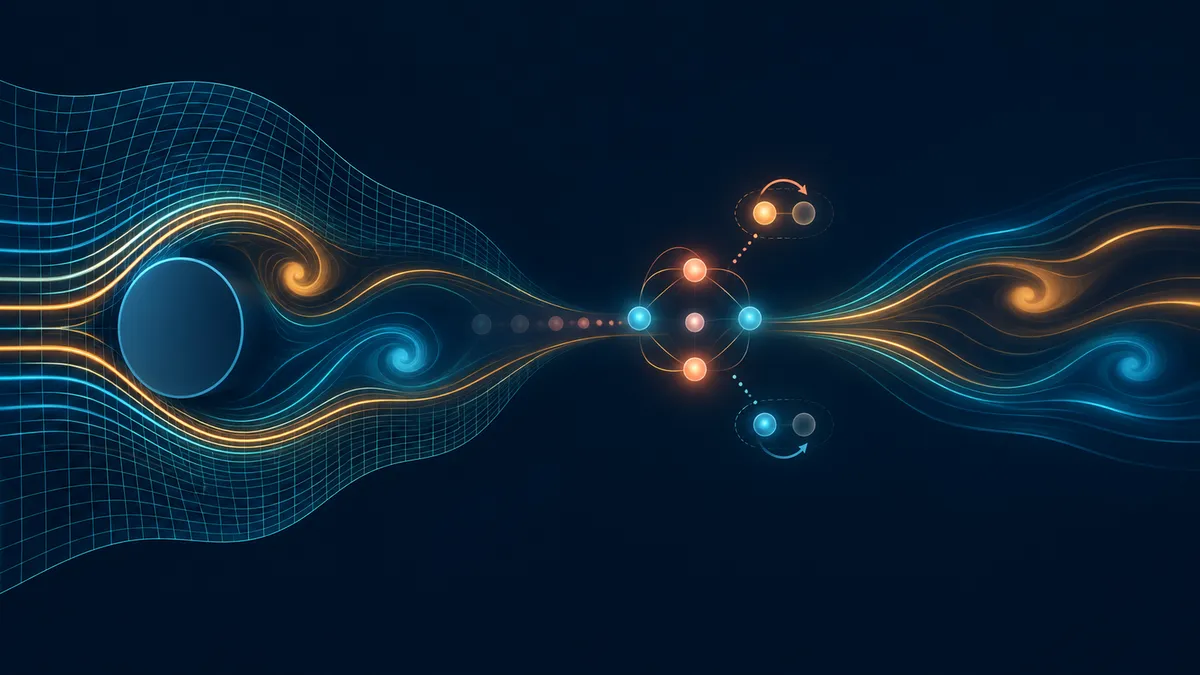
How can a quantum processor help predict a flow described on tens of thousands of irregularly arranged cells, when its qubits lose their coherence quickly? A new preprint combines a graph-based compressor with a quantum reservoir that keeps a fading memory through repeated partial measurements and resets. The authors tested it on superconducting hardware, then compared its forecasts with a simpler classical prediction pipeline.
Compress first, then forecast
A partial differential equation (PDE) describes how quantities such as velocity, pressure or chemical concentration change across space and time. Large simulations often divide space into cells. In an unstructured mesh, those cells need not form a neat rectangular grid, which makes it harder to map the problem onto a quantum circuit.
The researchers’ solution is a hybrid pipeline. First, a graph autoencoder compresses each field snapshot into a smaller vector, called a latent state. For the cylinder-flow problem, the mesh contained 33,824 cells, and the model used 13 latent values for velocity. A separate 48-value representation encoded pressure for a task in which pressure was predicted from velocity. The autoencoder handles the mesh; the quantum processor does not directly store every cell’s field value.
Next, a fixed quantum circuit transforms each latent state into features. This is a quantum reservoir network: the circuit’s gates are not trained. Instead, the researchers fit a classical linear readout to predict the next latent state from both the measured quantum features and the current state. That design avoids tuning circuit parameters through a variational algorithm, though the surrounding classical models are still trained.
The reservoir uses two groups of qubits. One stores a fading trace of past inputs; the other is partially exchanged with it, measured, and reset. The resulting back-action gradually erases older information while retaining more recent inputs. The researchers report circuit runs lasting up to about 28 times the median qubit T1 lifetime and 24 times the median T2 lifetime. These ratios describe circuit duration relative to coherence benchmarks—not a claim that individual qubits remain coherent throughout the entire run.
Measurements also create a practical bottleneck: estimating every possible correlation among many qubits would require too many samples. The team extracts Pauli-Z correlations from the same measurement records and keeps only terms up to a chosen weight. Higher-weight terms capture more complex correlations but can be less reliable under noise and finite sampling. Choosing this cutoff after measurement lets them trade feature richness against the available shot budget.
Tests on flow and reaction patterns
The team evaluated two simulated systems: flow around a cylinder at Reynolds number 1,000 on the irregular 33,824-cell mesh, and the nonlinear Gray–Scott reaction–diffusion system on a 128-by-128 grid. It ran circuits in CUDA-Q simulations and on IBM superconducting processors with 26 or 52 qubits. Prediction tasks included forecasting the next velocity or concentration field, estimating cylinder pressure one step later from velocity, and feeding predictions back into a ten-step forecast.
For one-step and pressure-observer predictions, adding quantum-reservoir features reduced normalized prediction error by about 21% to 43% compared with a linear readout using the same compressed representation but without those features. The comparison isolates the extra value of the reservoir features within this pipeline. It does not show superiority to the strongest classical forecasting systems: the authors say such comparisons and broader ablations are still needed. In Gray–Scott one-step forecasting, the reported error was the same in simulation and on both 26- and 52-qubit hardware configurations.
The authors also demonstrated closed-loop forecasts on hardware, where each predicted state becomes input to the next step. Results varied: the paper reports that, in its cylinder-flow rollout experiments, added noise was associated with lower ten-step error, and suggests noise may regularize the fitted readout. But the simulation and hardware circuits did not use matched random seeds, and the trend is limited to those tests; it is not evidence that noise generally improves quantum computation.
A capability demonstration, not a speedup
The paper’s central advance is a demonstration that a non-variational quantum reservoir can contribute predictive features on noisy hardware for PDE datasets that include an unstructured mesh. Its 52-qubit runs exceed what the authors could simulate by exact state-vector sampling, but that is not the same as beating classical methods. The reported execution-time comparison is against exact simulation of the same quantum circuits, not against classical PDE solvers; the authors explicitly note that conventional solvers would likely be faster and more accurate for these examples.
The evidence is also bounded by the test set and selected models. The study uses two simulated physical systems, and the mesh-flow dataset comes from a numerical model rather than a reported experimental flow measurement. Field reconstruction depends on the autoencoder as well as the forecasting readout. Whether this approach can scale into useful scientific workflows—perhaps as a warm start for a classical solver—remains open. The article is a preprint, not a claim of established practical quantum advantage.
- quantum reservoir computing
- partial differential equations
- superconducting quantum processors
- unstructured meshes
- fluid dynamics
- reaction–diffusion
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
An AI model can reveal a fluid’s properties without letting us control them
Source published
Shared keywords: fluid dynamics
Stretching coordinates helps neural networks learn sharp solution changes
Source published
Shared keywords: partial differential equations
PINNeval asks physics-informed AI benchmarks to test the whole training pipeline
Source published
Shared keywords: partial differential equations