TRANSMISSION // 2611.10317v1
TripleGrader organizes human review of AI-extracted knowledge
Source published
An open-source platform combines independent scoring, discussion and revision of extracted relationships. In two small datasets, most language-model outputs needed editing to match existing benchmarks—but the study did not test whether the platform makes reviewers faster or more accurate.
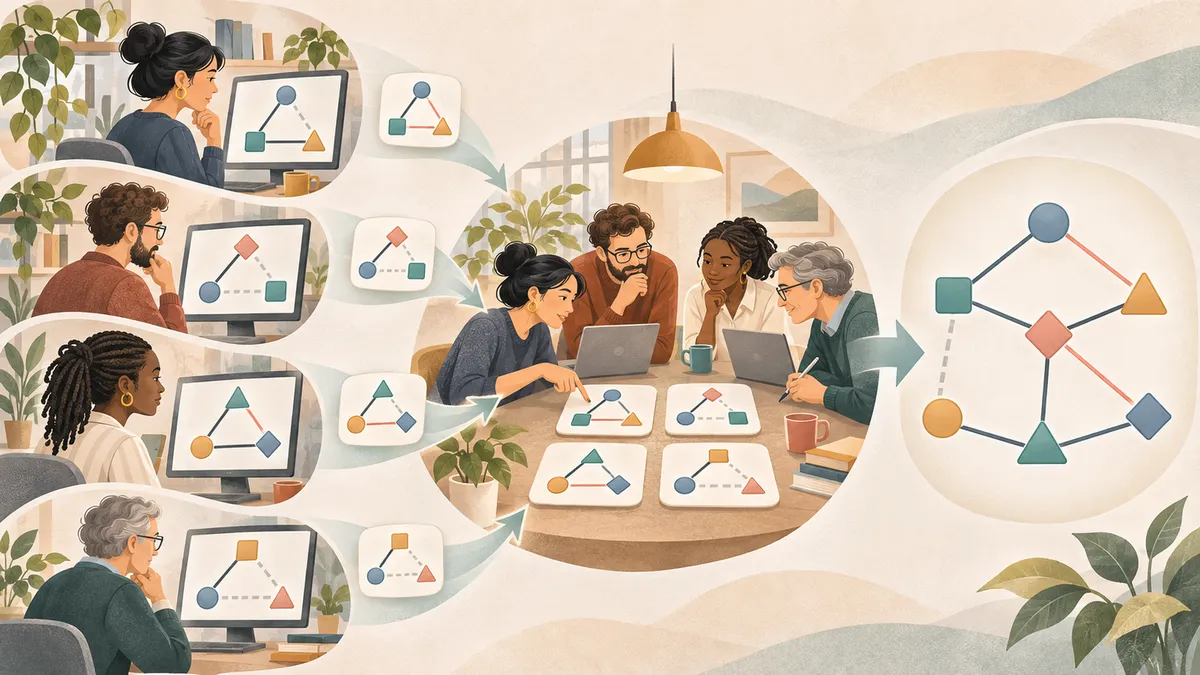
Turning text into a knowledge graph requires more than extracting plausible relationships. Those relationships must also be checked for accuracy and completeness. In an arXiv preprint, Rajan Lamichhane and Songhui Yue introduce TripleGrader, a web platform designed to keep that human review process, its revisions and its agreement statistics together.
What reviewers are checking
Knowledge graphs represent relationships as subject–predicate–object triples: a subject, the relationship it participates in, and an object. Automated extraction systems, including large language models, can produce these triples from text. But a candidate may contain an incorrect relationship, leave a pronoun unresolved or miss information that the source expresses.
The researchers ask two questions: can a dedicated platform support the full process from independent grading to an exported benchmark, and how much editing do language-model candidates need to match existing reference datasets?
TripleGrader focuses on relationships that have already been extracted, rather than on marking passages and assigning categories within raw text. Its contribution is the combination of graded judgments, discussion, approved revisions and renewed scoring—not a claim that no other annotation tool supports numerical ratings or weighted agreement.
Independent scores, then discussion
Reviewers score each triple from 0 to 10. This is an ordinal scale: scores express an ordering of quality rather than simply labeling a relationship correct or incorrect. Reviewers also rate whether a sentence’s triples capture its meaning completely and whether their predicates follow the relevant schema and guidelines.
Peer scores remain hidden until a reviewer has rated the item. Participants can then discuss candidates in comment threads, suggest changes or additions, and vote on proposals. A session owner approves revisions and publishes versions.
Crucially, scores are tied to the wording reviewed. When a new version is published, grades for changed triples are discarded so reviewers can assess the revised wording. Sentence-level ratings are similarly removed when their underlying triples change. Unaffected grades remain.
The final benchmark is not selected by an automatic score threshold. Grades guide discussion, while approval and removal decisions determine which triples enter the benchmark export.
Measuring agreement without confusing it with truth
For two reviewers, TripleGrader calculates quadratic-weighted Cohen’s kappa. For three or more, it uses a quadratic-weighted Fleiss-type measure. These statistics compare observed disagreement with disagreement expected from the score distributions. Quadratic weighting penalizes large score differences more strongly than small ones.
Agreement is not evidence that a relationship is true: reviewers can share the same misunderstanding. The paper also illustrates how a small sample with scores concentrated near the top of the scale can produce an unstable kappa. The platform reports no value when all grades are identical or fewer than two items have been rated by multiple reviewers.
Three kinds of evaluation
The authors report 72 automated tests, including 18 scenarios exercising the backend through its web interface for software requests. These checked permitted operations, rejection of prohibited actions, storage, version handling and agreement calculations. They did not test the contents of Excel, Word or PDF exports, or truly concurrent writes.
A separate experiment injected 10 types of error into a reference dataset, including incorrect triple components, missing entries and duplicates. Scripted repairs reversed the injected changes while preserving unaffected records, with no differences in the final row-level comparison.
However, the repair script knew what had been altered. This demonstrated that the workflow could carry out prescribed corrections, not that human reviewers could discover the errors.
The third evaluation used four language models to extract candidates from two small collections: 15 software-ethics units with a 66-triple benchmark, and 40 biomedical units with 69 reference relationships. Each model’s output became a separate review session.
Only 10.3% to 31.7% of candidates remained unchanged. Between 53.2% and 71.4% were retained after modification, and reviewers added 11 to 29 missing triples per model and corpus. These results show substantial editing was needed to reach the chosen references.
What the results cannot establish
Each corpus was graded by one author with its benchmark available. The final datasets matched those benchmarks by design, so this experiment measures editing requirements—not independent benchmark discovery or agreement between reviewers. Some changes reflected naming conventions, including identifier suffixes and biomedical namespaces, rather than incorrect underlying relationships.
The counts describe single extraction runs. Repeat runs through one model-serving API reproduced only 34% to 97% of candidates despite a temperature setting of zero.
The work is an arXiv preprint. It provides software-workflow evidence and a limited curation study, but no controlled comparison showing reduced review time or workload. Evaluation with several independent graders also remains outstanding.
- TripleGrader
- knowledge graphs
- triple annotation
- large language models
- human review
- inter-rater agreement
- benchmark curation
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
AI agreement on crisis labels is not the same as accuracy
Source published
Shared keywords: inter rater agreement, large language models
FinEvolveKG improves financial AI extraction while keeping prompt edits traceable
Source published
Shared keywords: large language models
When graphs help AI agents—and why better retrieval is not enough
Source published
Shared keywords: knowledge graphs, large language models
Type-aware graph rankings offer a way to guide AI retrieval
Source published
Shared keywords: knowledge graphs
Can AI Models Help Check Each Other’s Explanations of Legacy Code?
Source published
Shared keywords: human review, large language models