TRANSMISSION // 2611.10151v1
WorldMind tests spatial reasoning without turning every imagined view into an image
Source published
An arXiv preprint connects a vision-language model directly to a world model’s internal representations, reporting better spatial benchmark scores while leaving questions about simulation reliability and computational cost.
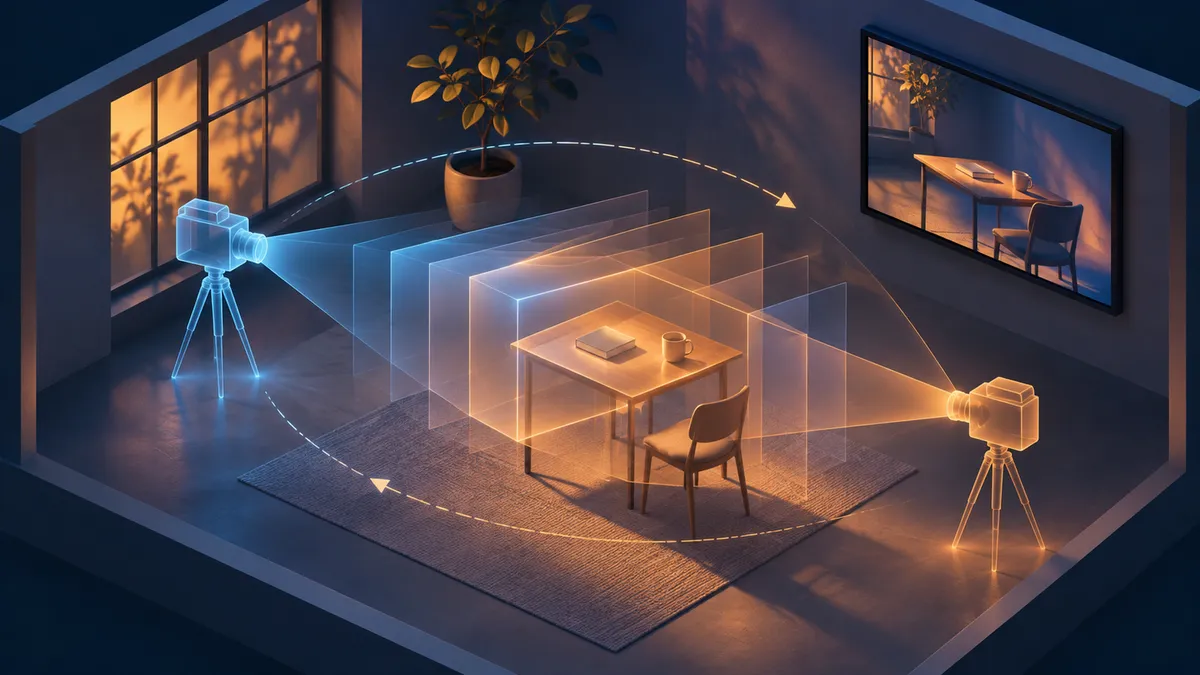
If you walked around a table and faced the opposite direction, which objects would now be on your left? WorldMind tackles this kind of question by letting an AI request simulated viewpoint changes and examine their internal representations rather than rendered pictures.
Recognizing a chair in a photograph is different from working out where that chair would appear after moving across the room. The second task requires reasoning about a viewpoint that the original image does not show. A vision-language model, which processes images and language together, may identify the objects correctly yet struggle with that transformation.
In an arXiv preprint, Haoming Wang, Yongjian Fu, Ju Ren and Wei Gao introduce WorldMind, a system designed to make those transformations part of the reasoning process. Their central proposal is to give the language-and-vision model access to a world model’s internal features, rather than communicating every simulated view through a newly generated image. The supplied source is a preprint, not evidence of journal publication or peer review.
Simulating a view without rendering it
Here, a world model is a generative system that predicts how a scene would look following a camera movement. Existing approaches can ask such a model to produce a new view, then feed the resulting picture into a vision-language model.
WorldMind changes that interface. It uses a frozen world model called Stable Virtual Camera, or SVC, and extracts selected internal representations known as latent features. A trained adapter translates these features into a form the vision-language model can use.
The distinction matters because generating a picture and then analyzing it again introduces an additional conversion. The authors argue that spatial information may be lost or poorly represented along that route. Direct access to latent features offers an alternative, although those features still describe a model-generated state rather than a fresh observation of the real world.
WorldMind retains ordinary image inputs. During reasoning, it generates a textual step and a camera action, receives latent features from the simulated transformation, and adds them to its context. It can repeat this interaction before producing its answer.
Learning which simulations help
Not every internal feature carries equally useful spatial information. The researchers build a candidate bank from four world-model layers and four denoising timesteps, then select eight layer–timestep combinations through offline feature ablation. That selection remains fixed during subsequent training and inference.
Training proceeds in stages. First, 40,000 examples align the adapter with the vision-language model. Then 10,000 synthetic reasoning trajectories teach the system to interleave reasoning, camera actions and returned latent features. Finally, reinforcement learning uses 5,000 questions to improve the policy’s own trajectories. The authors state that evaluation-split samples were excluded from training.
The reinforcement-learning reward considers more than the final answer. Intermediate progress is weighted by whether the camera action matches the intended instruction and whether the simulated state is reliable. For synthetic scenes, state reliability is assessed by comparing generated latent features with features extracted from a ground-truth view rendered at the requested camera pose. A separate penalty discourages unnecessary world-model calls.
These checks supply training signals; they do not establish that every later simulation is correct.
What the benchmark tables report
The main tables show improvements over Qwen3-VL-8B-Instruct, the base model. On VSI-Bench, which combines multiple-choice and numerical spatial questions, the reported overall score rises from 57.4 to 71.1. MMSI-Bench rises from 29.4 to 43.4, while MindCube-Tiny rises from 40.9 to 59.2.
The benefits are not uniform. On VSI-Bench, route planning rises from 32.0 to 55.4, whereas object size changes only from 74.1 to 75.7. This pattern supports the authors’ interpretation that simulation is especially useful when a question requires transformed viewpoints or several spatial reasoning steps.
A smaller experiment compares reasoning interfaces more directly. Latent simulation scores above RGB-image simulation on all three benchmarks, although the MindCube difference is only 48.5 versus 48.4. The paper explicitly distinguishes these smaller experiments from its full-scale results.
What remains uncertain
The system still depends on a generative world model, which can become unreliable when asked to extrapolate beyond observed views. Its training-time state check benefits from synthetic scenes with known target views; that is not the same as having ground truth available for an unfamiliar real scene.
The reported tables do not provide uncertainty intervals, and the paper does not quantify end-to-end latency or memory savings. Avoiding image conversion therefore should not be read as a demonstrated overall speedup. The supported result is narrower: this trained combination improves the reported spatial benchmark scores, with direct latent communication offering a promising alternative to exchanging imagined pictures.
- spatial reasoning
- vision-language models
- world models
- latent representations
- test-time scaling
- reinforcement learning
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
How well can AI see the details biologists need?
Source published
Shared keywords: spatial reasoning, vision language models
An AI model can reveal a fluid’s properties without letting us control them
Source published
Shared keywords: latent representations, world models
Teaching vision-language AI when a short answer is enough
Source published
Shared keywords: vision language models
EvoWorld tests whether AI-generated worlds can change while the camera looks away
Source published
Shared keywords: vision language models, world models
An AI maze navigator remembers by updating its world model
Source published
Shared keywords: world models