TRANSMISSION // 2611.09634v1
LambdaMix trains language models to offer adjustable trade-offs
Source published
A preprint describes jointly trained adapters that let one language model shift between competing objectives without retraining. Benchmark results show broader control than tested conditioned baselines, but gains depend on the model, task and reward normalization.
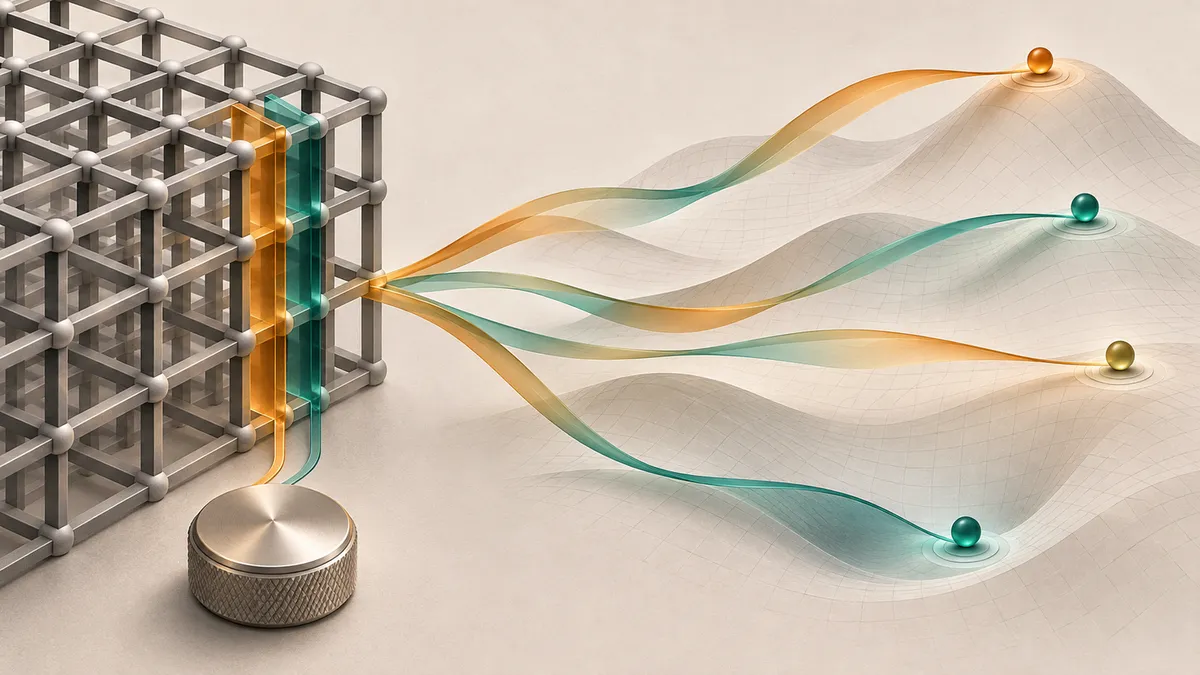
Can a language model change its balance between answering helpfully and avoiding harm without another round of training? LambdaMix learns adjustable mixtures of small parameter updates, then lets a preference setting choose the balance at generation time.
Learning more than one balance
Training a language model to satisfy several goals usually requires deciding how much each goal matters. But those priorities may change after training. A model solving a mathematics problem, for example, might need to balance getting the answer right against following restrictive formatting instructions.
In a preprint under review, Constantinos Karouzos and Nikolaos Aletras of the University of Sheffield introduce LambdaMix. Rather than producing one fixed compromise, their method learns a family of behaviors that users can select without further training. The experiments test two objectives at a time—not arbitrary combinations of many goals.
One preference controls generation and learning
LambdaMix freezes the underlying language model and adds one low-rank adapter per objective. These adapters are compact, trainable parameter updates. A preference vector assigns nonnegative weights that sum to one, determining how strongly each adapter contributes to the model’s weights.
The same preference also controls the learning signal. During training, the mixed model generates eight responses to each prompt. Every response receives a score for every objective. LambdaMix standardizes each objective’s scores separately within that response group, then combines them using the preference weights. It normalizes the combined values across the generation batch before applying a group-relative reinforcement-learning update.
Separate normalization reduces the influence of differences in raw reward scales. It also means the preference is not a literal exchange rate between raw scores: the effective balance depends on variation among the sampled responses.
Only the adapters are updated, with a penalty discouraging excessive departure from the starting model. Training begins with equal priorities and progressively introduces stronger preferences. Although each adapter is associated with an objective, it can learn from feedback involving both objectives.
After training, changing the preference changes the adapter mixture. Generation requires neither reward scoring nor parameter optimization.
What the benchmarks measured
The researchers tested Qwen3-4B, Olmo 3 7B, Qwen3.5-9B and Qwen3.6-27B on two tasks. One used separate learned evaluators to score helpfulness and harmlessness. The other paired GSM8K mathematics problems with two response constraints, measuring numerical correctness in the required answer format and compliance with the constraints.
The two largest models also rewrote synthetic forum comments. Here, the objectives were preserving wording and reducing evidence for supplied personal attributes, such as age or occupation. Wording retention used ROUGE-1 word overlap; attribute-support rejection used judgments from another language model.
Conditioned models were evaluated at eleven preference settings, using one greedily generated response per test prompt and setting. Test sets contained 1,354 helpfulness–harmlessness prompts, 300 mathematics problems and 111 rewriting comments.
The main comparison used hypervolume: the area covered by the available score combinations above a reference point. Higher hypervolume indicates a stronger set of trade-offs under those metrics, not necessarily that every setting beats every competitor.
Better coverage, with an important exception
On the first two tasks, LambdaMix achieved higher hypervolume than every tested conditioned and policy-merging baseline across all four models. It was not the overall winner everywhere: hierarchical expert routing, called HoE, achieved higher hypervolume on Olmo 3 7B in both tasks.
On Qwen3.5-9B, helpfulness–harmlessness hypervolume was 0.8735, versus 0.7760 for prompt conditioning, the strongest baseline on that comparison. For mathematics on Qwen3.6-27B, increasing the correctness preference raised accuracy from 47.0% to 95.3%, while instruction compliance fell from 97.8% to 74.5%. All eleven settings offered distinct, non-dominated compromises within that sweep.
Controlled experiments on Qwen3.5-9B held architecture, initialization and training budgets fixed. Varying both adapter mixtures and objective weights produced higher hypervolume and wider score ranges than varying either alone.
Normalization was not universally beneficial. It improved helpfulness–harmlessness coverage on every model, but reduced mathematics hypervolume on two models. The rewriting task performed best without per-objective normalization on both tested models.
Efficiency does not establish safety
For Qwen3.5-9B, LambdaMix used one training run, 32,000 generated completions and 13.2 million stored adapter parameters. Five separately trained specialists required 160,000 completions and 33.1 million adapter parameters. These are completion and storage comparisons, not measured training-time savings; prompt conditioning stored fewer parameters than LambdaMix.
The results also depend on what the scorers recognize. Learned helpfulness and harmlessness scores are not guarantees of safe behavior. Rejecting attribute support in synthetic comments does not establish protection against real-world inference, and word overlap does not establish preservation of meaning. Training and evaluation used the same rewriting scorers.
Preference changes were not consistently ordered across every experiment, and some settings produced identical aggregate scores. Users therefore cannot assume a perfectly calibrated control. The authors also warn that allowing lower harmlessness weights may produce more harmful responses. LambdaMix demonstrates adjustable benchmark trade-offs, not unrestricted deployment readiness.
- LambdaMix
- language models
- multi-objective reinforcement learning
- low-rank adapters
- preference conditioning
- AI safety
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Turning AI adapters back into readable instructions
Source published
Shared keywords: language models
Can switching off AI safety components make a model harder to jailbreak?
Source published
Shared keywords: ai safety
Biomedical fine-tuning often reduced AI models’ caution in paired audit
Source published
Shared keywords: ai safety
UpSafe°C lets language models adjust their safety routing
Source published
Shared keywords: ai safety
Targeted weight edits help restore AI refusal behavior after fine-tuning
Source published
Shared keywords: ai safety, language models