TRANSMISSION // 2611.09554v1
Changing positional signals helps AI models retrieve overlooked evidence
Source published
A preprint reports that question-dependent changes to positional encoding improve long-context retrieval without deleting text or retraining models. Gains on question answering are smaller, and the method adds processing before answers begin.
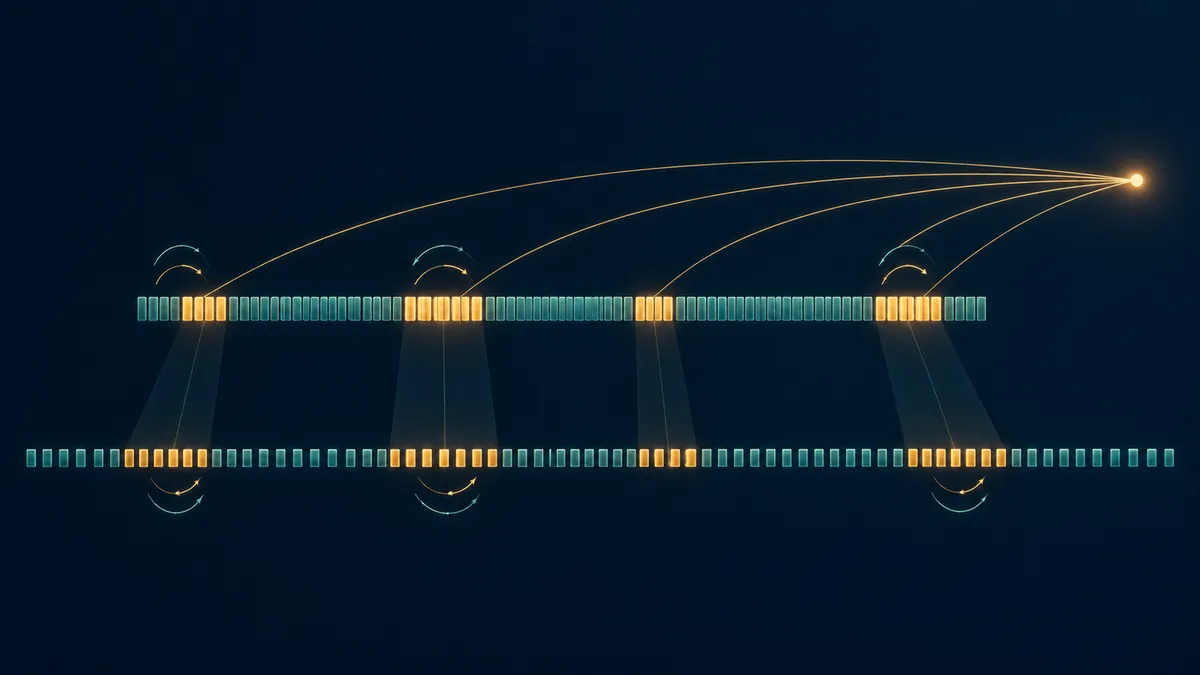
Why can a language model accept a long document yet miss evidence inside it? A new preprint explores whether changing how the model represents distances—not shortening or rearranging the document—can help it retrieve information relevant to a question.
A long input is not necessarily a usable one
Language models can overlook information in the middle of their input while using its beginning and end more successfully. This “lost-in-the-middle” problem means that accepting more text does not guarantee using it effectively.
In a November 2026 preprint, Peiyu Zhang and colleagues propose Query-Guided Positional Modulation, or QGPM. It changes positional signals according to the question while keeping every input token—the units into which text is divided—in its original order. The aim is better use of an existing context window, not a larger one.
Changing encoded distances, not the document
The method targets rotary position embedding, usually called RoPE. This encodes position by rotating components of the numerical vectors used to calculate attention, the mechanism through which a model draws information from earlier text. Different pairs of components rotate at different rates.
The authors argue that fast-rotating components provide a less consistent distance signal across long separations. Slower components retain a broader positional structure. Their proposed intervention reduces selected encoded distances on the fast components while leaving the slow components approximately unchanged. This is a proposed contributor to retrieval failures, not proof that RoPE explains every instance of lost-in-the-middle behavior.
QGPM first processes the prompt with ordinary positions. A small, previously selected set of attention heads—individual attention mechanisms within the model—provides signals for ranking context sentences by relevance to the question. Those heads are selected separately for each model using labeled calibration examples disjoint from evaluation examples. Thus, “training-free” means no model weights change; it does not mean no calibration is needed.
The sentence ranking produces two relevance maps. A broad map preserves several candidate sentences in lower model layers. A sharper map emphasizes fewer sentences in upper layers. The authors hypothesize that earlier layers need broader context to construct representations, while later layers benefit from fewer competing sentences.
During a second, answering pass, low-ranked text advances by smaller positional increments on fast-rotating components. Compressing the intervening positional distance can bring evidence closer to the question in those components. Instructions and question tokens retain ordinary increments, as does a protected context prefix before the first sentence classified as relevant. No text is deleted or reordered.
Stronger retrieval, modest question-answering gains
The researchers tested four instruction-tuned models: Qwen2.5-7B, Qwen3-4B, Ministral-8B and Granite-3.3-8B. Comparisons included the unchanged models, the token-compression method LLMLingua-2, and three other positional methods.
NoLiMa tests retrieval where questions and evidence share little literal wording. Evaluations used contexts of roughly 4,000 to 32,000 tokens. Four tasks from RULER covered question answering and retrieval at lengths up to roughly 64,000 tokens. Responses were scored by whether they contained the required reference answers.
QGPM achieved the highest five-task average among the compared methods for every model, improving over unchanged models by 2.4 to 8.9 percentage points. These are benchmark averages, not estimates of general-purpose reliability.
On Qwen2.5, average NoLiMa accuracy increased from 28.5% without modification to 46.1% with QGPM; STRING, the strongest baseline on this comparison, reached 33.1%. On Granite’s task requiring retrieval of one target value among similar keys, average accuracy increased from 66.0% to 85.1%.
Question-answering improvements were much smaller. Qwen3’s multi-hop question-answering average actually slipped from 56.6% to 56.2%. Better retrieval did not translate into uniformly better answers.
What remains unresolved
Long inputs remained difficult. At NoLiMa’s 32,000-token setting, Qwen3 reached only 8.3% accuracy with QGPM, versus 4.0% unchanged. On Qwen2.5 at that length, replacing estimated relevance with annotated evidence improved QGPM’s result by another 5.7 percentage points, suggesting relevance identification remained a bottleneck.
Keeping every token also does not preserve every positional detail. Small increments blur local ordering within low-ranked text on fast components, although slow components retain its broader placement.
Practical costs matter. QGPM requires access to internal model vectors and positional tables, so it cannot be applied through an ordinary text-only model API. Its extra initial processing increases time before the first generated token, although the authors report unchanged per-token decoding cost and attention-cache size. Ministral’s 64,000-token results also exceed its configured 32,768-token window and require that qualification.
The preprint supports a narrower conclusion than solving long-context understanding: question-dependent positional changes improved retrieval on the tested benchmarks. It does not establish a general cure for reasoning errors or unreliable answers.
- long-context language models
- lost in the middle
- rotary position embedding
- query-guided positional modulation
- information retrieval
- attention
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
CHARM+ rearranges GPU communication to speed up distributed attention
Source published
Shared keywords: long context language models
Keeping the right evidence when AI inputs must shrink
Source published
Shared keywords: long context language models
An AI memory proposal would preserve organizational judgments, not just records
Source published
Shared keywords: information retrieval