TRANSMISSION // 2611.09536v1
Can language help a video detector spot unusual events?
Source published
A preprint combines video features, corrected captions and language-model-generated descriptions to improve anomaly detection on two benchmarks. The gains depend on how those information sources are combined, and do not establish reliability outside the tested datasets.
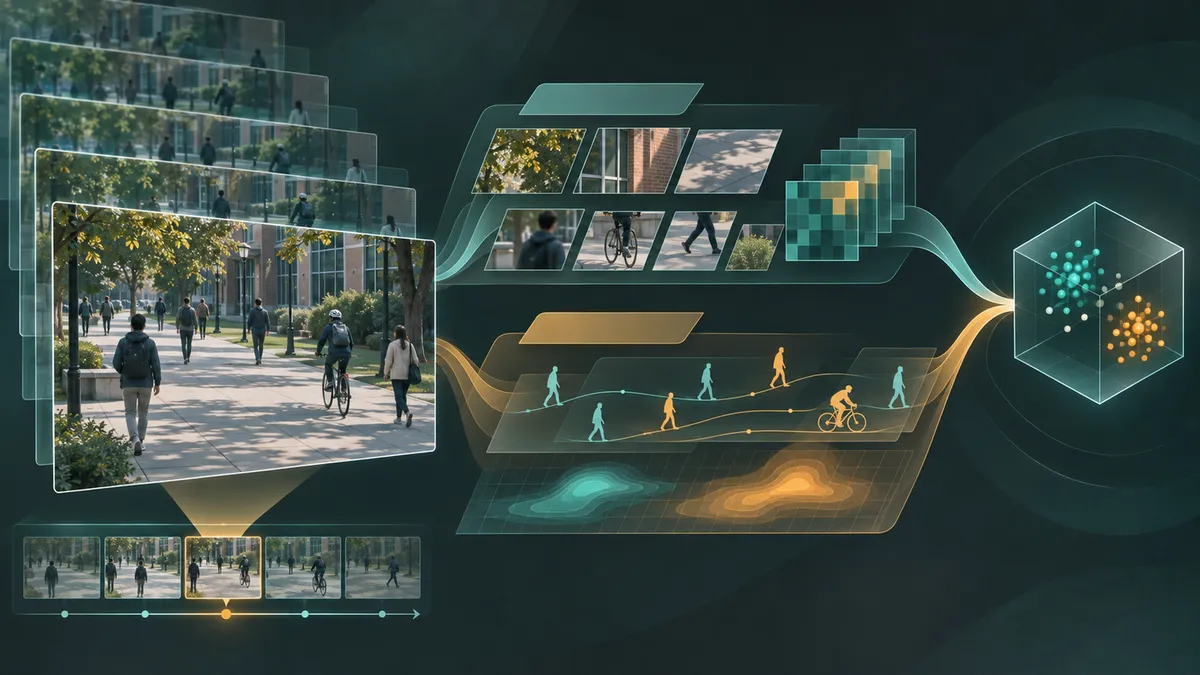
A video can be labelled as containing an unusual event without anyone marking exactly when it happens. A new study investigates whether generated descriptions of normal and abnormal activity can help a detector learn from those incomplete labels.
Learning without a timestamp for every event
How can a computer learn to locate an unusual event when its training label only says that something unusual happens somewhere in a video?
That is the problem of weakly supervised video anomaly detection. Video-level labels reduce the need for detailed annotation, but leave the model to discover which moments explain each label. In a November 2026 preprint, Xiao Tan of Xidian University proposes adding textual information to this learning process: descriptions of expected activities, descriptions of anomalies and captions of the footage itself.
The study reports improved results on ShanghaiTech and UCF-Crime. These are benchmark findings from a preprint, not evidence that the system is ready for unrestricted surveillance or other safety-critical uses.
Two different roles for language
The method uses language in two distinct ways.
First, human-written prompts ask GPT-3 to generate descriptions of normal and anomalous situations relevant to each dataset. For ShanghaiTech, the supplied examples treat ordinary walking on a campus street as normal and activities such as cycling or fast running as abnormal. These categories reflect the particular detection task, not universal definitions of suspicious behaviour.
The generated descriptions are encoded numerically using BART. A technique called dictionary learning then represents that information through a compact collection of reusable patterns. The aim is to reduce redundancy before introducing the descriptions into the detector.
Second, the system generates captions for video frames using BLIP. The paper identifies a problem here: similar frames can receive inconsistent descriptions. It therefore supplies an LLM with both the captions and object detections from YOLOv8, asking it to correct the descriptions.
This correction depends on an explicit assumption: the object detector provides more accurate supporting information. It is not a guarantee that the resulting caption matches the scene.
Combining appearance, motion and descriptions
The detector processes three information streams: RGB imagery, optical flow representing motion between frames, and text. Pretrained I3D models extract the visual features, while BART encodes the textual descriptions.
Two successive attention stages combine visual and textual information. Attention lets one representation assign different weights to information in another. Here, visual features first guide the selection of textual information; the resulting representation then attends back to visual features.
A final component, called Knowledge Traction, uses the generated normal and anomalous descriptions to reweight the fused features before classification. The training objective includes a constraint intended to prevent this guidance from excessively distorting those features.
The detector is trained with video-level labels rather than detailed frame annotations. However, it also draws on pretrained models and generated task-specific knowledge: weak supervision does not mean that the video labels are its only information source.
Higher benchmark scores, with unequal margins
The evaluation uses frame-level area under the receiver operating characteristic curve, or AUC. This measures how well anomaly scores distinguish normal from anomalous frames across decision thresholds. It is not the percentage of frames classified correctly at a particular operating threshold.
The full method reaches 98.17% AUC on ShanghaiTech. The highest competing value listed in that table is 97.48%, a difference of 0.69 percentage points.
On UCF-Crime, it reaches 87.11%, compared with the table’s strongest competing result of 86.98%: a smaller difference of 0.13 percentage points. The comparisons also involve different feature extractors and inputs; the proposed method uses both RGB and optical flow.
Component-removal experiments show that the combination matters. Adding Knowledge Traction to a configuration with only one attention direction reduces performance. With both attention stages present, it improves the reported scores. More generated knowledge is not automatically better either: 5,000 normal and 5,000 anomalous descriptions outperform both smaller and larger balanced collections in the reported tests.
What remains uncertain
The comparison tables provide no uncertainty intervals or repeated-run variability, making the small UCF-Crime lead difficult to assess statistically. Testing on two datasets also does not establish transfer to unfamiliar settings.
Some implementation reporting is inconsistent. The main experiments specify balanced normal and anomalous knowledge collections, while the appendix describes UCF-Crime anomalies as one third of the generated samples. That leaves the precise sampling arrangement unclear.
The appendix also acknowledges remaining false detections in normal videos with rapid scene changes or unusual-looking scenes. The result is therefore a qualified one: generated language can help this detector on the reported benchmarks, but its usefulness depends on the prompts, supporting models and feature-fusion design.
- video anomaly detection
- weakly supervised learning
- multimodal learning
- large language models
- dictionary learning
- cross-modal attention
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
When words, voice and faces disagree, an emotion AI changes its approach
Source published
Shared keywords: large language models, multimodal learning
A fitted DNA ‘plug’ lets frozen language models answer gene questions
Source published
Shared keywords: multimodal learning
Finding surprising shopping patterns without abandoning statistics
Source published
Shared keywords: large language models
Similar examples give AI coding models a modest boost in a selected test
Source published
Shared keywords: large language models
AI radiology summaries can miss small words with important meanings
Source published
Shared keywords: large language models