TRANSMISSION // 2611.09520v1
Better AI training may start with where the data came from
Source published
A preprint finds that choosing data sources before individual examples can reduce labelling needs and improve accuracy on poorly served groups—when source metadata reveals meaningful differences.
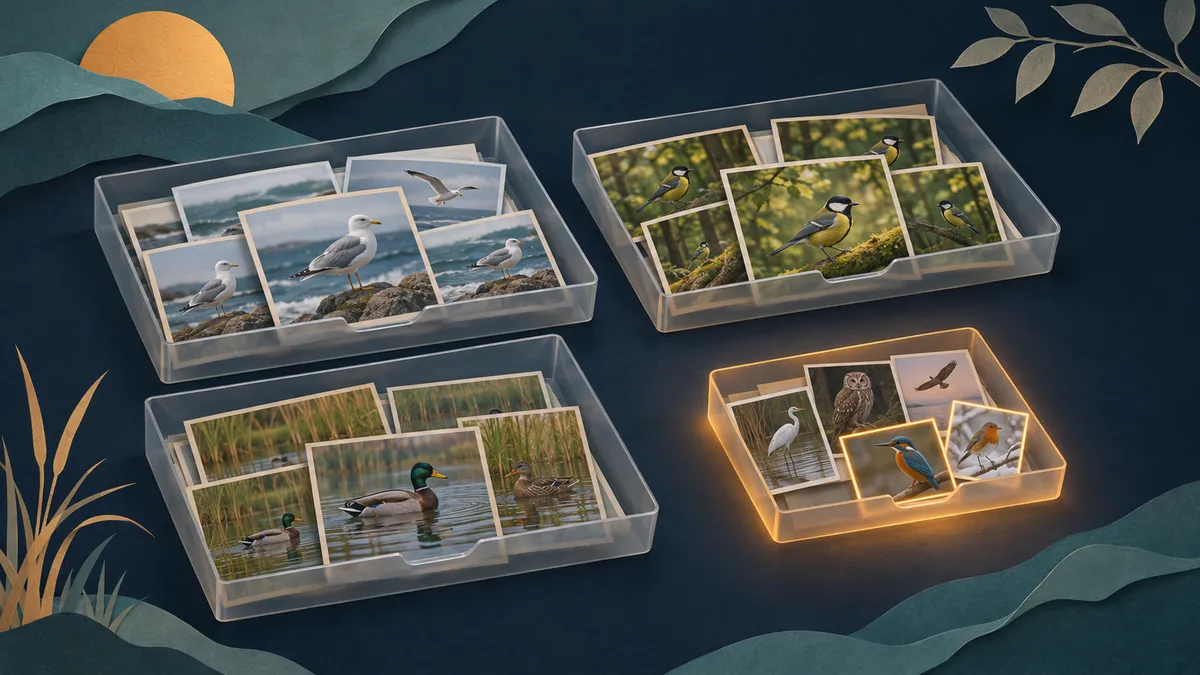
Which examples should an AI model ask someone to label? Choosing the ones it finds most confusing sounds sensible. But a confidently wrong model may overlook precisely the examples it needs.
When confidence hides a shortcut
Active learning aims to reduce the expense of labelling training data. A model starts with a small labelled dataset, selects more examples for annotation, then learns from the answers. Many selection methods prioritise examples whose predictions are uncertain.
In Active Learning of Robust Models, Mizu Nishikawa-Toomey and colleagues examine how that strategy can fail when models learn misleading correlations. Their preprint, submitted on 6 November 2026, proposes using information about where examples came from to guide selection.
Consider classifying land birds and water birds. If most training photographs show birds in their usual habitats, the model can learn to recognise backgrounds rather than birds. A water bird standing on land might then receive a confident but incorrect prediction—and never become a priority for labelling.
This matters under subpopulation shift: a change in the relative frequency of existing groups of examples. A model that looks accurate when unusual bird-background combinations are rare may struggle when those combinations become common. The paper targets this particular kind of change, not every possible difference between training and deployment.
Choose a source, then choose examples
The researchers distinguish underlying environments from observable sources. An environment describes a different relationship between predictive features and labels. A source is a metadata category, such as the hospital that supplied an image. Sources need not correspond neatly to environments: several hospitals might supply similar data, while one hospital could contain a mixture.
Their method uses these imperfect source identifiers without requiring the true environment labels.
First, it estimates uncertainty for each unlabelled example. The experiments use Monte Carlo dropout: repeated predictions with parts of the network randomly disabled. Across 100 such passes, the method averages predictive entropy, a measure of how spread out the predicted class probabilities are.
It then averages those example-level scores within each source. Rather than immediately selecting the most uncertain individual examples across the entire pool, it allocates the labelling budget according to source-level uncertainty.
The strongest reported variant, Top1-SoftRank, chooses the source with the highest average score at each round. Within that source, it samples examples using an existing uncertainty-rank-based batch selection method. Another variant spreads the budget across sources using a probability weighting.
The rationale is that averaging can expose an informative source despite unreliable confidence estimates for individual examples. The paper also develops a supporting mathematical argument, but under a restricted linear-Gaussian model with sufficiently many examples per source—not a general guarantee for neural networks.
What the experiments found
The authors tested three controlled image-classification benchmarks: ColoredMNIST, Waterbirds and CelebA. They constructed sources with different proportions of examples that reinforced or contradicted a spurious correlation.
All methods used the same pretrained DINO vision-transformer backbone. Comparisons included random selection, conventional uncertainty methods, diversity-based methods and a baseline that sampled equally from each source. Experiments were repeated across five random seeds.
The main benchmark measure was worst-group accuracy: accuracy on whichever predefined group performed least well. Those group labels were available for evaluation, not for training or example selection.
On ColoredMNIST, Top1-SoftRank reached 60% worst-group accuracy with an average of 67 labelled points, compared with 257 for equal sampling across sources. At 70%, the corresponding counts were 106 and 360. These are results for that experimental setup, not universal estimates of annotation savings.
The researchers also tested Camelyon17 lymph-node tissue images from five hospitals, using hospital identity as source metadata. They deliberately varied hospital representation to create more challenging mixtures. Because underlying group labels were unavailable, they measured accuracy on the worst-performing hospital instead.
Top1-SoftRank reached 90% worst-source accuracy with an average of 66 labelled points, compared with 464 for equal source sampling and 322 for the diversity-based BAIT method. Worst-hospital accuracy is a proxy here; it does not establish performance for every subgroup within a hospital.
Where the advantage weakens
The method depends on metadata carrying useful information. When the researchers mixed environments more heavily within sources, its advantage declined. Gains were also smaller when the reliable feature was relatively easy to learn, as in their initial CelebA setup.
Increasing the number of similar majority sources exposed another distinction: equal source sampling spent more effort on redundant sources, while selecting the highest-scoring source remained effective in the tested settings.
The evidence comes from three controlled benchmarks and one medical-image dataset. It does not demonstrate clinical readiness or reliable performance at entirely unseen hospitals. The practical finding is narrower: when source metadata reflects meaningful differences, using it to decide where to request labels can improve the weakest measured performance while requiring fewer annotations.
- active learning
- subpopulation shift
- spurious correlations
- source metadata
- worst-group accuracy
- image classification
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
ACTOR uses delayed labels to improve later image classifications
Source published
Shared keywords: active learning, image classification
Using generated ultrasound images to choose real ones worth labeling
Source published
Shared keywords: active learning
When a Prediction Model Benefits From Forgetting Data
Source published
Shared keywords: active learning
ALTO study tests detection of online gender-based violence in three language settings
Source published
Shared keywords: active learning
Using AI Disagreement to Improve Microdroplet Design
Source published
Shared keywords: active learning