TRANSMISSION // 2611.09511v1
V-STORM tests whether video AI can connect the evidence it finds
Source published
A preprint introduces video questions with explanations tied to specific times and locations. Its tests suggest that finding relevant evidence and combining it correctly are distinct challenges, while targeted training improves both answers and evidence alignment.
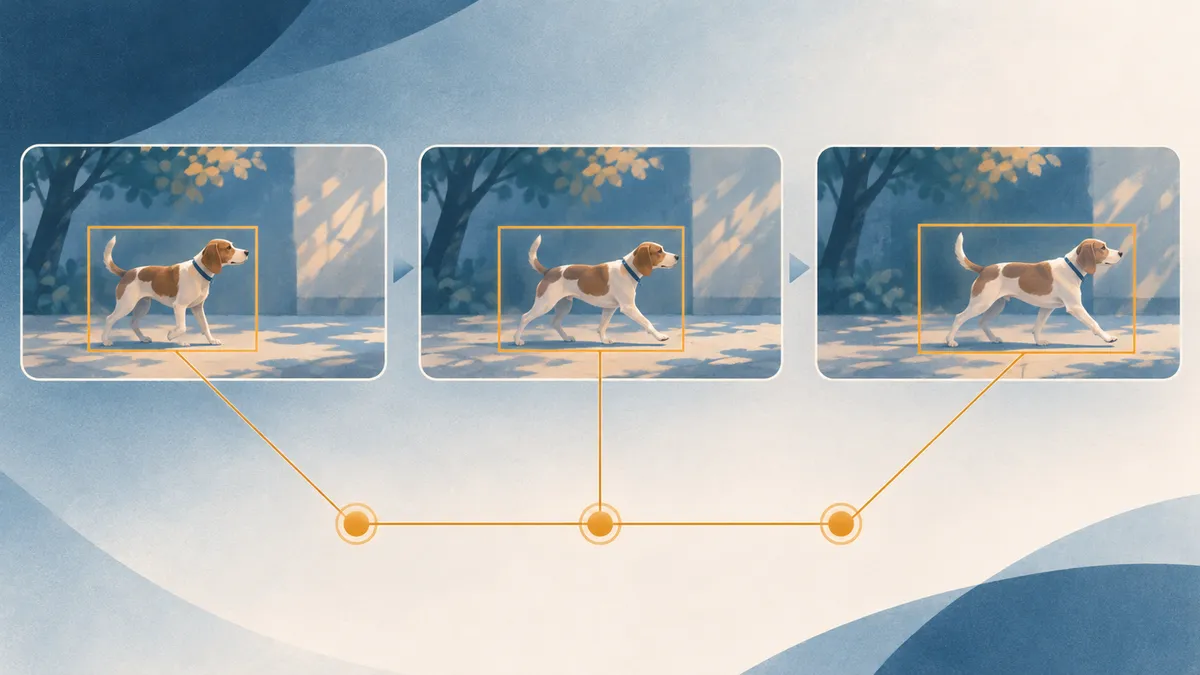
Recognizing a dog in a video is different from tracking that same dog several seconds later. V-STORM, a new research dataset and evaluation framework, asks video AI systems to support their answers with evidence showing not just what happened, but when and where.
Looking beyond the final answer
An AI system can choose the right answer to a video question without identifying the right supporting evidence. Conversely, it can locate relevant objects yet fail to connect their actions across time. A preprint by Dian Jiao and colleagues at Zhejiang University and the National University of Singapore investigates that distinction.
The researchers introduce V-STORM, a framework for building video questions, evidence-linked explanations and evaluation data. The paper, posted on November 6, 2026, describes roughly 260,000 training examples and a human-verified benchmark of about 3,300 examples. Its contribution is a data construction and testing approach, rather than a new model architecture.
The central question is whether video-language models can do more than recognize a scene: can they locate the necessary evidence and combine it into a correct multi-step answer?
Turning videos into connected observations
V-STORM starts by organizing videos into a spatio-temporal scene graph. In plain language, this is a structured record of objects, their locations, their relationships and how they change over time.
The pipeline uses Florence-2 to propose objects in selected frames and SAM2 to track them. A multimodal language model helps resolve ambiguous identities. Observations are first organized frame by frame, then combined within short segments. Only high-confidence matches connect objects across segments, reducing reliance on uncertain long-range tracking.
Software then samples connected paths through this graph. Those paths supply the evidence for questions, correct answers and step-by-step explanations. A language model translates the structured material into readable language, while alternative graph elements provide plausible but incorrect multiple-choice options.
The resulting explanations, called Grounded Chain of Thought, cite timestamps and object locations. For example, a question might identify a dog at one moment and ask where it appears several seconds later. The explanation must connect those two observations rather than merely describe the dog.
A separate verification stage retrieves relevant visual evidence and checks generated questions and answers for consistency. Eight trained experts inspected every benchmark example. Training data received automated checks plus human sampling. In a 400-example audit, reported accuracy rose from 73.8% before verification to 95.0% afterward.
Finding evidence is not the same as using it
The benchmark measures three things separately: answer accuracy, the logical consistency of generated explanations and the alignment of cited evidence with annotated times and locations. The latter two receive scores ranging from 0 to 5. Explanation quality is assessed using a Qwen model, with additional checks described by the authors.
The results show a recurring gap between simpler temporal questions and questions requiring several observations to be combined. For the model labeled GPT-5.2, temporal-reasoning accuracy was 79.12%, compared with 41.71% on compositional reasoning. Its grounding scores remained relatively high: 3.58 and 3.75, respectively.
That pattern supports the authors’ interpretation that locating evidence and composing it into an answer are separate capabilities. However, aggregate grounding scores do not establish that every wrong answer used entirely correct evidence.
Targeted training brings large gains
Fine-tuning Qwen3-VL-2B-Instruct with V-STORM increased overall benchmark accuracy from 52.83% to 79.42%. Its compositional-reasoning accuracy rose from 19.85% to 73.28%, while its overall grounding score increased from 3.22 to 4.38.
Those results put the trained model ahead of all other models evaluated on this benchmark. They do not establish superiority across video understanding generally.
A separate comparison using about 95,000 training examples helps clarify the contribution of the explanations. Training without reasoning traces already produced substantial gains. Adding grounded traces improved overall accuracy by another 1.97 percentage points, and by 1.27 points compared with coarser explanations. Improvements on four external benchmarks were smaller.
What the evidence does not settle
The study remains a preprint. Its automatically constructed training material is not error-free, as the audits themselves show, and explanation scoring partly depends on another AI model. Most evaluated systems received two sampled frames per second, whereas Gemini3-Flash used one, creating a comparison difference.
The tasks are multiple-choice questions drawn from short and medium-length videos. Strong performance therefore should not be treated as proof of reliable operation in unrestricted real-world settings. Evidence-linked explanations make outputs easier to check, but are not direct measurements of a model’s internal reasoning.
V-STORM’s clearest message is narrower: evaluating the answer alone can miss important differences between seeing relevant evidence and using it correctly.
- V-STORM
- video understanding
- multimodal AI
- spatio-temporal reasoning
- evidence grounding
- AI evaluation
- preprint
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
AdaAlloc helps video AI decide where to look closely
Source published
Shared keywords: multimodal ai
AI diagram errors shift from counting to seeing when code takes over
Source published
Shared keywords: ai evaluation, multimodal ai
A financial AI benchmark separates good answers from well-supported facts
Source published
Shared keywords: evidence grounding
GraphRail checks the evidence behind search agents’ reasoning
Source published
Shared keywords: evidence grounding
Can combining biopsy images and clinical data improve predictions in inflammatory bowel disease?
Source published
Shared keywords: multimodal ai