TRANSMISSION // 2611.09433v1
DexDICE teaches robots from cautious and fast demonstrations
Source published
A preprint describes a way to learn efficient behavior from one set of demonstrations and safety boundaries from another. Simulations and a small robot experiment show promise, but its mathematical safety guarantee does not cover the practical controller.
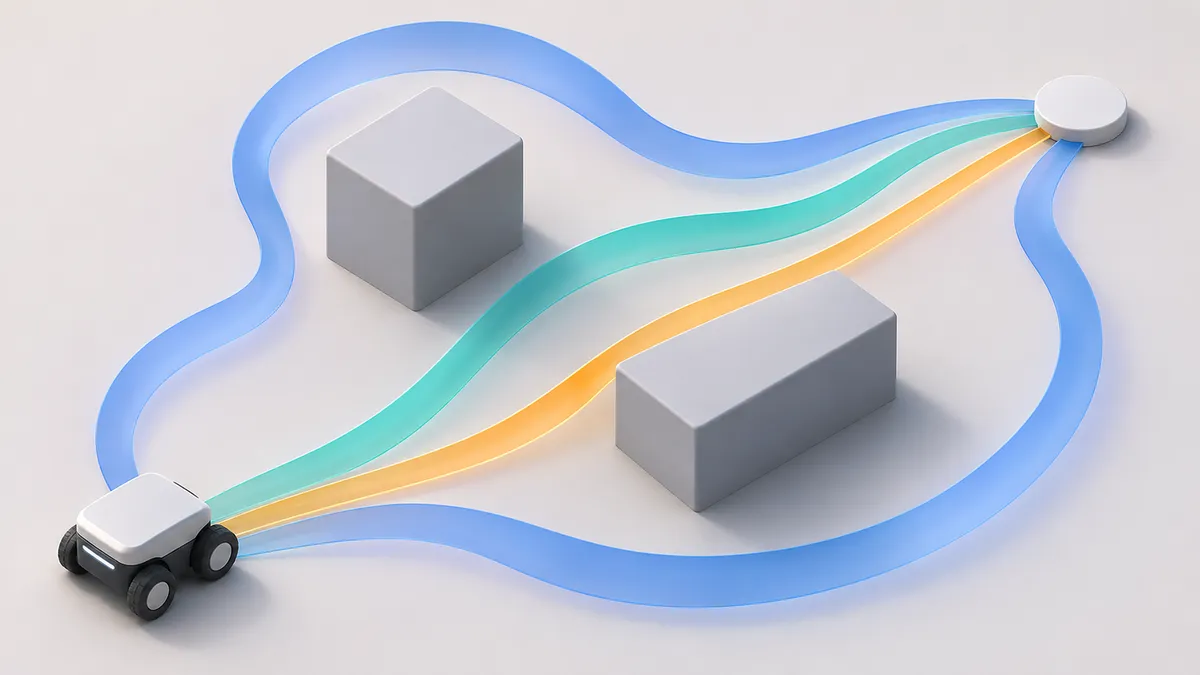
A cautious robot may avoid obstacles but take too long to finish its job. A faster demonstrator may show useful shortcuts while getting dangerously close to objects. DexDICE attempts to learn from both without copying either demonstrator wholesale.
Two teachers with different priorities
Teaching a robot by example presents a dilemma: demonstrations that combine excellent performance with reliable safety can be difficult to collect. Cautious examples may be slow, while efficient ones may include risky actions.
In a preprint posted to arXiv on November 6, 2026, Seokin Seo and colleagues introduce DexDICE, an offline imitation-learning method designed around that distinction. It uses separate sets of safety-focused and performance-focused demonstrations, plus a larger collection of unlabeled examples. Training proceeds entirely from recorded data, without additional interaction with the environment.
The question is whether a learner can imitate efficient behavior while remaining inside boundaries inferred from cautious demonstrations—without being given explicit numerical rewards or safety penalties during training.
Learning boundaries, not cautious habits
DexDICE distinguishes between which situations and actions appear in safe behavior and how frequently the cautious demonstrator chooses them. The researchers call the former the safe “support”: the region of state-and-action combinations represented by the underlying safe demonstration distribution.
Matching a cautious demonstrator’s behavior too closely can reproduce its inefficiency. DexDICE instead seeks behavior resembling the performance-focused expert, subject to staying within the estimated safe support. Conceptually, this means learning which maneuvers are permissible without necessarily adopting the cautious expert’s preference for slower ones.
Two neural-network classifiers compare the expert datasets with the larger unlabeled collection. One provides a performance signal; the other helps estimate the safe support. A threshold calibrated using safe examples determines which state-and-action pairs are accepted.
The method then uses distribution correction estimation, or DICE, to calculate weights for recorded examples while accounting for how actions lead to subsequent states. A final controller learns through weighted behavioral cloning: examples receiving larger weights exert more influence on its choices.
Promising results, with a specific definition of safety
The researchers adapted 38 tasks from the DSRL offline safe reinforcement-learning benchmark, covering Safety Gymnasium, Bullet Safety Gym and MetaDrive. For each task, they sampled 10 safe and 10 high-performing trajectories, with the full offline dataset supplying unlabeled examples.
Although DexDICE did not receive numerical reward or cost labels during training, those quantities were used to construct the demonstration groups. The approach therefore still depends on meaningful separation of safe and high-performing examples.
With one fixed threshold parameter across tasks, DexDICE met the benchmark’s cost constraint on 31 of 38 tasks. It achieved the highest return among constraint-satisfying methods on 19 tasks, counting ties within one standard error. Results were averaged over five random seeds.
Here, “safe” means that mean accumulated cost stayed within an allowed budget—not that every action was free of violations. DexDICE was neither universally safe nor always the highest-performing method. Its main advantage was the reported balance between these objectives.
Controlled experiments on six tasks also tested smaller demonstration sets and less favorable mixtures of examples. Performance deteriorated under extreme scarcity or very limited overlap between safe and efficient behavior.
A small physical-robot test
For a hardware demonstration, one operator collected 114 joystick-controlled navigation episodes using a SUMMIT-XL-Steel mobile robot. Ten aggressive runs supplied performance examples, 10 conservative runs supplied safety examples, and all 114 formed the unlabeled collection.
In an arena with two obstacles, DexDICE reached the goal in all 10 physical trials, with no measured safety-distance violations. Its mean time to goal was 16.9 seconds across those 10 successes. BC-Safe, a controller trained only to copy safe demonstrations, averaged 36.0 seconds across its eight successful trials out of 10. Failed trials were excluded from both time-to-goal averages.
A violation meant that the nearest LiDAR-measured obstacle distance fell below 0.65 metres. These results concern a small number of trials in the tested layout; they do not establish reliability across unfamiliar environments. Candidate policies were also checked in a calibrated simulator before hardware deployment.
Why the guarantee stops short of deployment
The paper proves a high-probability, zero-unsafe-visitation result for an ideal controller that obeys the support constraint exactly. It assumes uncontaminated safe demonstrations, sufficiently accurate classification, suitable separation between safe and unsafe regions, and adequate data coverage.
The practical controller does not satisfy that exact constraint. Its Gaussian action distribution can propose actions outside the estimated safe support. A separate action-adjustment experiment reduced such mismatches substantially but did not eliminate them.
The authors also acknowledge that the theoretical conditions are monitored through empirical diagnostics rather than certified. DexDICE offers encouraging evidence for learning safety and efficiency from different teachers—not a general guarantee of safe robot deployment.
- DexDICE
- imitation learning
- robot safety
- offline learning
- dual-expert learning
- mobile robot navigation
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Helping AI learn from demonstrations that leave an uneven picture
Source published
Shared keywords: imitation learning, offline learning
What Hidden Bids Can Tell Sellers About Auction Reserve Prices
Source published
Shared keywords: offline learning
Language models help design rewards for two-stage payment fraud detection
Source published
Shared keywords: offline learning
HomeLoop tests whether home robots investigate before intervening
Source published
Shared keywords: robot safety
Editing a Robot Model’s Hidden Goal Without Changing Its Instructions
Source published
Shared keywords: robot safety