TRANSMISSION // 2611.09411v1
DataHelix coordinates data preparation to keep AI training moving
Source published
A preprint reports that coordinating CPU preprocessing with accelerator progress can speed up video and multimodal model training. Across 11 workloads, DataHelix achieved 2.72 times the throughput of rank-local data loaders, though its benefits came with communication costs and workload-dependent trade-offs.
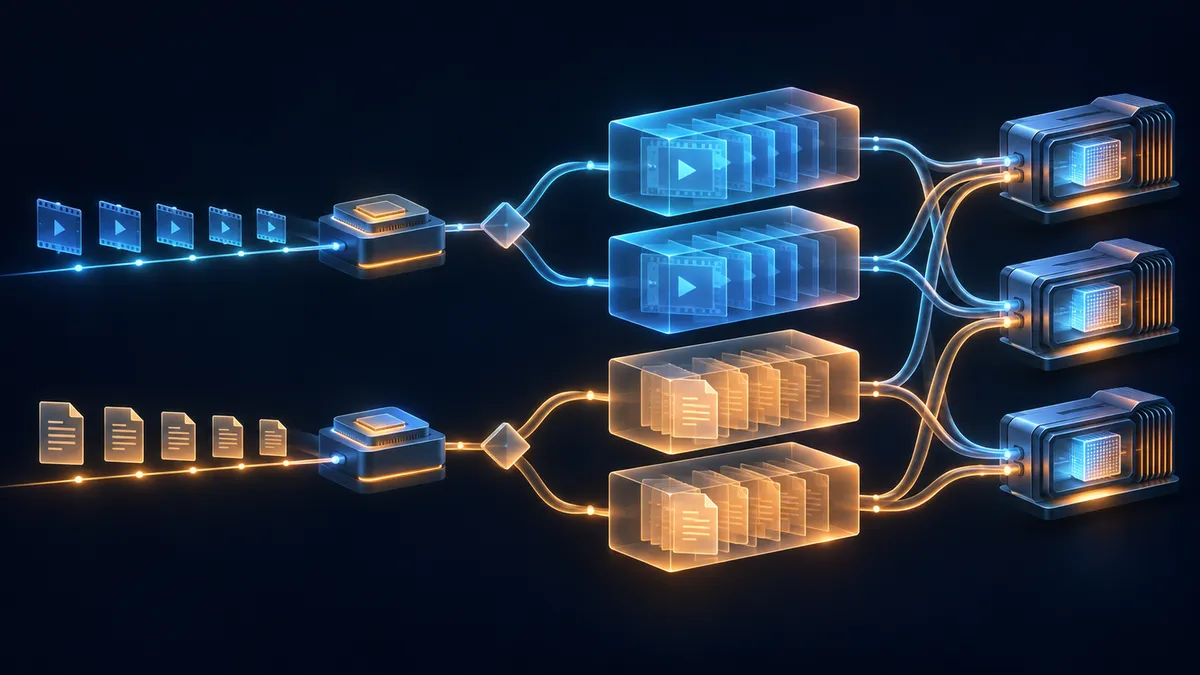
Powerful AI accelerators can spend substantial time waiting for their next batch of training data. A new preprint presents DataHelix, a system that schedules data preparation around when each training process will need its inputs, rather than simply trying to keep preprocessing workers busy.
When one slow batch holds everyone back
Training models on video and text creates an uneven workload. A short, low-resolution clip may be relatively quick to decode and process. A longer or higher-resolution clip can demand much more preparation and produce a larger input for the model.
Dividing samples equally among training processes therefore does not necessarily divide the work equally. In synchronous training, processes periodically synchronize their model updates. A process delayed by data preparation can consequently leave other accelerators waiting too.
The DataHelix preprint, by Yuanhe Li and colleagues at Shanghai Jiao Tong University and Xiamen University, asks whether coordinating preprocessing with accelerator execution can reduce these stalls. Its central argument is that preparing more data per second is not enough: the right batch must reach each process at the right time.
Scheduling before data becomes bulky
DataHelix treats the time spent computing on the current batch as a preparation window for the next one. Its scheduler estimates whether a candidate preprocessing server can finish and deliver that next batch within the available window.
Those estimates include CPU processing, input reading, queueing and the cost of transferring the prepared output. A remote server with an empty queue is not automatically preferable if delivering its result would take too long. When candidates can meet the target, the system favors keeping work local.
Crucially, these decisions happen before decoding. At that point, samples are represented by lightweight descriptors containing information such as file locations, frame counts and resolution. Moving or reassigning those descriptors is much cheaper than moving the large tensors produced after processing.
A central coordinator handles this metadata, while separate DataServers perform preprocessing and deliver results directly. This keeps bulky training inputs out of the coordinator’s path.
Balancing both preparation and computation
DataHelix also tries to distribute the model’s computational work more evenly. Before decoding, it groups samples by their profiles and assigns them using estimates of token or latent counts—the representations that help determine how much work the model must perform.
Estimates cannot capture every variation. A second balancing stage can therefore redistribute already processed samples using their actual properties, but only when the predicted reduction in waiting justifies the transfer cost. For this correction, DataHelix can use the accelerator communication infrastructure also used in distributed training.
Background threads dispatch future requests and collect completed batches while the current training step runs. Results retain their iterator order, and the training loop keeps a standard DataLoader-style interface. The authors describe implementations for PyTorch and MindSpore.
What the experiments found
The main evaluation covered 11 video and multimodal workloads on a server with eight Ascend 910B accelerators, using Kinetics and OpenVid data and several training models.
Across those workloads, DataHelix’s selected configuration achieved 2.72 times the geometric-mean throughput of the native, rank-local DataLoader baseline. The authors also report a 67.8% reduction in mean deadline-miss rate and an 87.0% reduction in mean 95th-percentile input-wait latency relative to that baseline. Here, a deadline miss means that input waiting exceeded a configured threshold.
To test whether additional CPU capacity alone explained the gains, the researchers compared DataHelix with a Ray actor pool under the same provisioned budget of 96 CPU cores. DataHelix achieved 1.82 times Ray’s geometric-mean throughput and a lower mean deadline-miss rate.
It did not win every metric. Ray had a lower mean 95th-percentile input wait: 7.902 seconds, compared with DataHelix’s 9.216 seconds. Both were substantially below the native baseline’s 70.848 seconds.
Gains with boundaries
Adding preprocessing servers was not consistently beneficial. Increasing the remote-server count from 16 to 24 often reduced throughput, with the authors attributing the regressions to contention. Component tests also showed that deadline-aware scheduling increased cross-server data movement in all four examined workloads, while not improving every latency or throughput result.
The strongest aggregate results came from a single accelerator server. A separate multi-node test using four machines with two A100 GPUs each reported a smaller, 1.36-fold geometric-mean throughput improvement across six matched workloads.
This is a preprint, and the reported benchmarks establish performance for the tested configurations, not a universal speedup or improved model quality. The practical lesson is narrower: coordinating data placement, preparation and delivery around training progress can reduce wasted accelerator time, but communication and resource contention remain important constraints.
- DataHelix
- multimodal model training
- data preprocessing
- distributed training
- CPU scheduling
- AI accelerators
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
FP4Quant speeds up GPU communication, with a measurable accuracy trade-off
Source published
Shared keywords: distributed training
Split-KV aims to make long-context drafter training faster
Source published
Shared keywords: distributed training
AMD researchers test ways to keep training data moving through GPUs
Source published
Shared keywords: distributed training