TRANSMISSION // 2611.09377v1
A substrate-aware model for enzyme kinetics reports small, uncertain gains
Source published
KineCouple lets a substrate’s molecular features influence which enzyme residues an AI model emphasizes. The preprint reports modest prediction improvements, but conflicting benchmark numbers and incomplete evaluation records limit the conclusions.
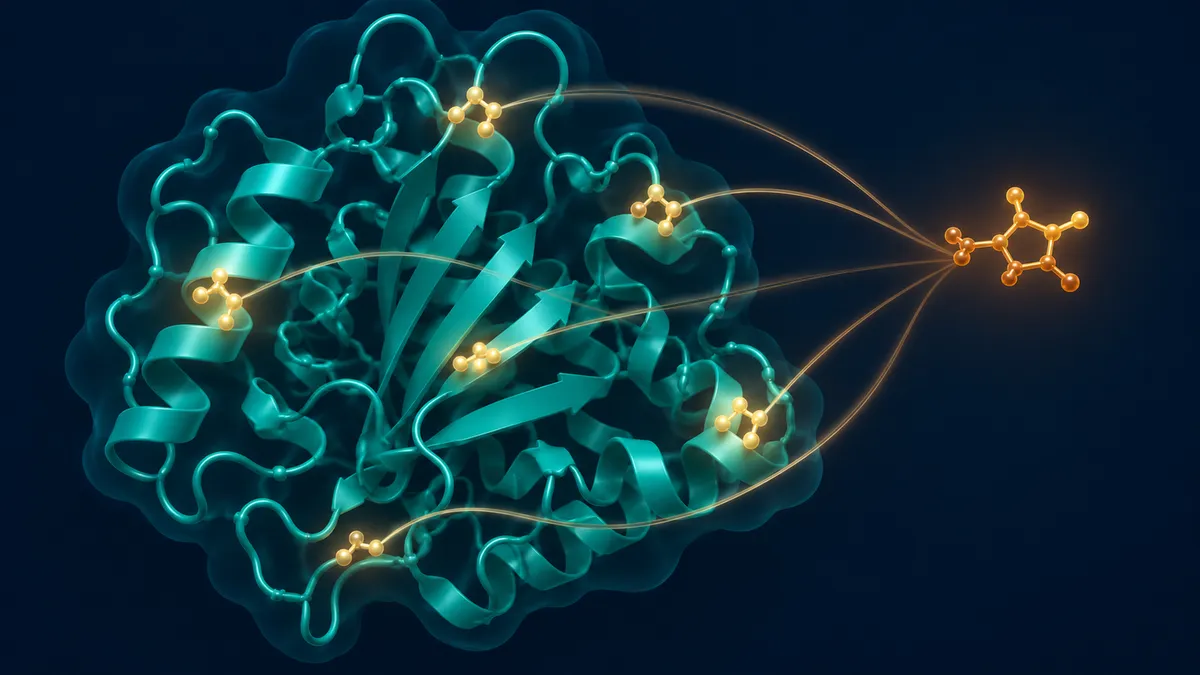
An enzyme’s behavior depends on the molecule it acts on. KineCouple brings that relationship into an AI model’s protein-summary step, rather than combining the substrate with an already-compressed protein representation. The idea is clear; the evidence for its advantage remains unsettled.
Can an AI model predict an enzyme’s behavior more accurately by changing which parts of the protein it emphasizes for each substrate? A preprint by Chun Kang and colleagues introduces KineCouple, a model designed to do that. Its reported improvements are small, and inconsistencies within the manuscript make their precise size uncertain.
Enzymes accelerate chemical reactions, but predicting how a particular enzyme will behave with a particular substrate—the molecule it acts on—remains difficult. Laboratory measurements are labor-intensive, and their results depend on conditions such as temperature and acidity. Computational estimates could help researchers prioritize experiments and construct models of metabolism, without replacing experimental characterization.
Two quantities, two prediction tasks
KineCouple predicts two standard kinetic parameters using separate models. The turnover number, kcat, describes the reaction rate per catalytic site when substrate is abundant. The Michaelis constant, Km, is the substrate concentration at which the reaction reaches half its maximum rate under Michaelis–Menten kinetics. Km is not simply a direct measurement of binding strength.
Both predictions use base-10 logarithms, allowing the models to handle values spanning many orders of magnitude. Consequently, the reported prediction errors are on a logarithmic scale, not in units of reaction rate or concentration.
Letting the substrate influence the protein summary
The model builds on pretrained systems called ProtT5 and MolT5. ProtT5 converts an enzyme’s amino-acid sequence into numerical features for individual residues. MolT5 supplies a numerical representation of the substrate, supplemented by a molecular fingerprint encoding chemical features. Both pretrained systems remain frozen: their internal parameters are not updated during kinetic training.
In the baseline approach, residue features are averaged into one protein vector before being combined with substrate information. That average cannot change with the substrate, although the later predictor can still learn interactions between the two global representations.
KineCouple adds cross-attention before this compression. A query derived from the whole substrate assigns weights to residue features, allowing the same enzyme to receive different summaries for different substrates. This is residue-level selection, not an atom-by-atom model of physical contacts.
The new summary does not replace the original protein average. Instead, the model subtracts a uniformly weighted summary from the attention-weighted summary, producing a correction. Uniform attention therefore yields no correction. A learned gate controls how much of that correction enters the original protein representation; it starts at zero, preserving the loaded baseline prediction function initially.
The researchers first train the baseline, then train the added branch together with the existing prediction head. The modification adds 533,249 trainable parameters, so substrate conditioning is not the only difference from the starting model.
Small gains, conflicting records
The abstract reports turnover prediction error falling from 1.333 to 1.330, with Pearson correlation rising from 0.492 to 0.496. For Km, error falls from 0.998 to 0.997 and Pearson correlation rises from 0.633 to 0.634. Lower error and higher correlation are preferable, but these changes are modest.
Other sections give different numbers. The main comparison table reports turnover errors of 1.327 for reproduced CataPro and 1.319 for KineCouple. The extended table instead gives KineCouple a turnover error of 1.330. These discrepancies prevent a single, unambiguous estimate of the improvement.
The main comparison combines held-out predictions across folds—subsets used to separate training from evaluation. However, the manuscript says fold assignments, sample counts and checkpoint-selection rules are unavailable, and complete protocol agreement has not been verified. Comparisons with other published methods also mix evaluation sources, so their rankings do not establish superiority under a common test.
A component-removal study reports that further baseline training accounts for some gains and that the full model performs better than mean pooling or substrate-independent attention. Yet its text describes ten folds while its caption names only four. Later sections also describe some already-reported controls as still needed. The experimental record therefore requires clarification, not just stronger statistical analysis.
What remains unproven
Without accessible raw predictions and uncertainty estimates, the report does not establish whether the gains reliably exceed training variability. Higher overall correlations also do not show that the model predicts mutation effects or differences between substrates for the same enzyme more accurately.
Practical limitations remain. The inputs omit explicit pH and temperature. For proteins longer than 1,000 residues, preprocessing retains only the first and last 500, discarding the middle. Attention weights describe model behavior, not experimentally established catalytic roles.
KineCouple offers a concrete way to make protein aggregation substrate-dependent. Whether that design provides a reproducible practical advantage awaits reconciled results, transparent evaluation records and stronger validation.
- enzyme kinetics
- KineCouple
- substrate-conditioned attention
- protein language models
- kcat
- Michaelis constant
- machine learning
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
A clearer view inside protein AI—but steering useful proteins remains harder
Source published
Shared keywords: protein language models
Machine learning connects atomic physics to simulations of stellar winds
Source published
Shared keywords: machine learning
PHISHREV+ uses explicit rules to reconsider phishing alerts
Source published
Shared keywords: machine learning
Satellite links detect rain better when neighboring receivers share information
Source published
Shared keywords: machine learning
Heart failure prediction models need stronger validation, review finds
Source published
Shared keywords: machine learning