TRANSMISSION // 2611.09364v1
Checking AI commands before connected devices act
Source published
SafeOrchestrate improved device-command execution across eight simulated tasks by translating requests into explicit rules and checking runtime conditions. The preprint does not establish real-world safety, and its stronger consistency checks do not cover multi-action responses.
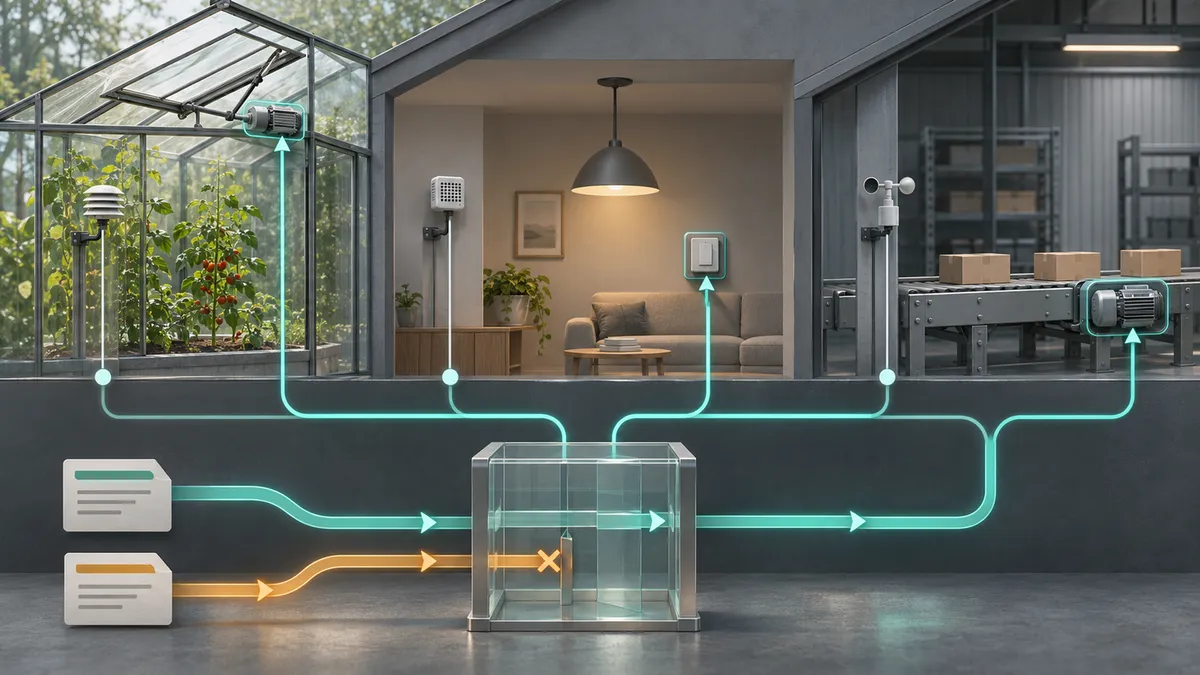
Asking an AI to coordinate lights, sensors or machinery is easy. Making sure it chooses the right action, respects the trigger and follows the intended order is harder. SafeOrchestrate tests an approach that separates interpreting a request from authorizing device commands.
A doorbell rings. An automated assistant should lower the speaker volume, notify the resident and restore the previous setting. Choosing the right commands is only part of the task: their order matters, and none should run without the trigger. What happens when a language model manages that coordination directly?
In a November 2026 preprint, Muhammad Ashfaq and colleagues present SafeOrchestrate, a prototype that places explicit rules and runtime checks between a natural-language request and connected devices. Across eight simulated tasks, it followed expected command sequences more closely than a direct language-model-to-tool baseline. The findings support a bounded reliability claim, not a guarantee of physical safety.
From requests to executable rules
SafeOrchestrate starts by splitting a request into smaller goals, each pairing a condition with a response. For example: if a robot arm holds an item, start the conveyor belt. The prototype uses fixed sentence and trigger cues for this decomposition, preserving the order in which goals appear.
A language model then converts each goal into a logical formula. Another model matches the formula’s symbols to available device interfaces. Crucially, it distinguishes observations from actions: checking whether an air conditioner is on is not the same operation as turning it on. Numeric comparisons, such as temperature exceeding a threshold, are attached through rule-based processing.
The implementation uses Web of Things descriptions, which list what devices can sense or do. These capabilities become tools and resources through the Model Context Protocol, or MCP. That common interface makes devices accessible; it does not itself establish that a model has understood their meaning.
For each goal, the orchestrator samples the relevant device state. If the condition is false, it does not execute the response. For responses containing a single action, a second check uses the Z3 constraint solver to ask whether that action is consistent with the whole grounded formula and any supplied deployment safety constraints.
The paper illustrates why this could matter with a conveyor example. An item in the robot’s hand might permit the belt to start, while an obstacle rule forbids it. Checking both rules together can block a command that passes its own trigger condition. An emergency-stop constraint can also prevent execution.
Better command traces in simulation
The researchers compared SafeOrchestrate with VanillaOrchestrate, which maps goals directly to MCP calls without runtime verification. Tasks covered occupancy-controlled lighting, temperature switching, greenhouse coordination, robot workflows and several household event sequences.
The grounding and action-argument stages used GPT-4.1; formula generation used the nl2spec tool with GPT-3.5 Turbo. Results were averaged over ten runs per atomic goal. The baseline was limited to three reactive tool-calling steps to prevent runaway behavior, a design choice that matters when interpreting comparisons on longer sequences.
Two measurements captured different kinds of success. Required-action accuracy checked whether every expected action occurred correctly at least once. It did not penalize extra actions or incorrect ordering. MCP Execution Similarity compared expected and observed sequences of state-changing calls, penalizing missing, additional, substituted or misordered calls. Read-only state queries were excluded.
Both systems scored 100% on both measures for the simple occupancy and temperature tasks. Differences widened on more involved workflows. For the doorbell task, the baseline scored 17% required-action accuracy and 13% execution similarity; SafeOrchestrate scored 100% on both.
SafeOrchestrate achieved 100% required-action accuracy across all eight tasks. Execution similarity was 100% for seven and 92% for the coming-and-leaving-home task, where it made an additional lighting action outside the expected sequence. That distinction matters: completing every required action does not mean doing only what was intended.
Where the checks stop
The strongest safety-related checks were illustrated in the worked example, not evaluated extensively. The eight benchmark tasks supplied no additional deployment safety constraints, and most contained only one rule. They primarily tested trigger and precondition enforcement.
Multi-action responses have a further restriction: they receive precondition gating but bypass the solver-based consistency check. The prototype also takes one state snapshot per goal and does not refresh it between that goal’s checks. It neither verifies action outcomes nor recovers from equipment failures.
Despite using temporal-logic-style formulas, the implementation strips temporal operators rather than checking behavior across time. Duration requirements work only when an available device operation accepts a duration parameter. Continuous monitoring and workflows whose later conditions depend on earlier action results are unsupported.
Finally, a well-formed formula, device mapping or argument can still be semantically wrong. The study did not isolate individual components’ contributions, test physical deployments or measure latency and scalability. Its contribution is evidence that structured interpretation and explicit execution checks can improve these simulated workflows—not that natural-language control is ready to operate machinery without further validation.
- SafeOrchestrate
- large language models
- cyber-physical systems
- runtime verification
- Web of Things
- Model Context Protocol
- device orchestration
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
MCPGuard Finds Protocol Checks Missing from Two Official MCP SDKs
Source published
Shared keywords: model context protocol
A conversational assistant explores the trade-offs in metal 3D printing
Source published
Shared keywords: model context protocol
Similar examples give AI coding models a modest boost in a selected test
Source published
Shared keywords: large language models
A spreadsheet map can help AI ask for less data
Source published
Shared keywords: large language models
When AI learns new facts, its confidence may lag behind
Source published
Shared keywords: large language models